Scrapers / Developer & File Tools
crates.io Scraper
hipersoft/crates-scraper
Search crates.io or look up exact Rust crates and get description, downloads, versions, license, keywords, categories, repository and documentation links.
Total users
1Monthly users
1Total runs
118Per crate scraped
$0.004Last rebuilt
Oct 26, 2026Overview
Search crates.io or look up exact Rust crates by name and get back clean, structured JSON: description, all-time and recent download counts, latest and max-stable versions, license, keywords, categories, and repository, homepage and documentation links. It pulls from the official crates.io public API — no account, no API key. Built for Rust developers, dependency auditors and OSS analysts who need reliable, ready-to-use crate data. Export to JSON, CSV or Excel.
Features
- 🔎 Free-text search — run any crates.io query (
web framework,async runtime) and collect matching crates in bulk. - 🎯 Exact lookups — pass precise crate names like
tokioorserdeand combine them with search results in one run. - 📊 Download metrics — capture both all-time
downloadsandrecentDownloadsfor popularity and trend analysis. - 🗂️ Rich detail — optional per-crate detail adds
license,keywords,categoriesand version count/size. - ↕️ Flexible sorting — order results by relevance, all-time downloads, recent downloads, recent updates or newest.
- 🔗 Ready-to-use links — every record includes
repository,documentation(docs.rs fallback),homepageand the canonicalcratesUrl. - ⚙️ Reliable by design — descriptive User-Agent plus retry-with-backoff so runs finish cleanly.
What you get
Each crate becomes one clean JSON record.
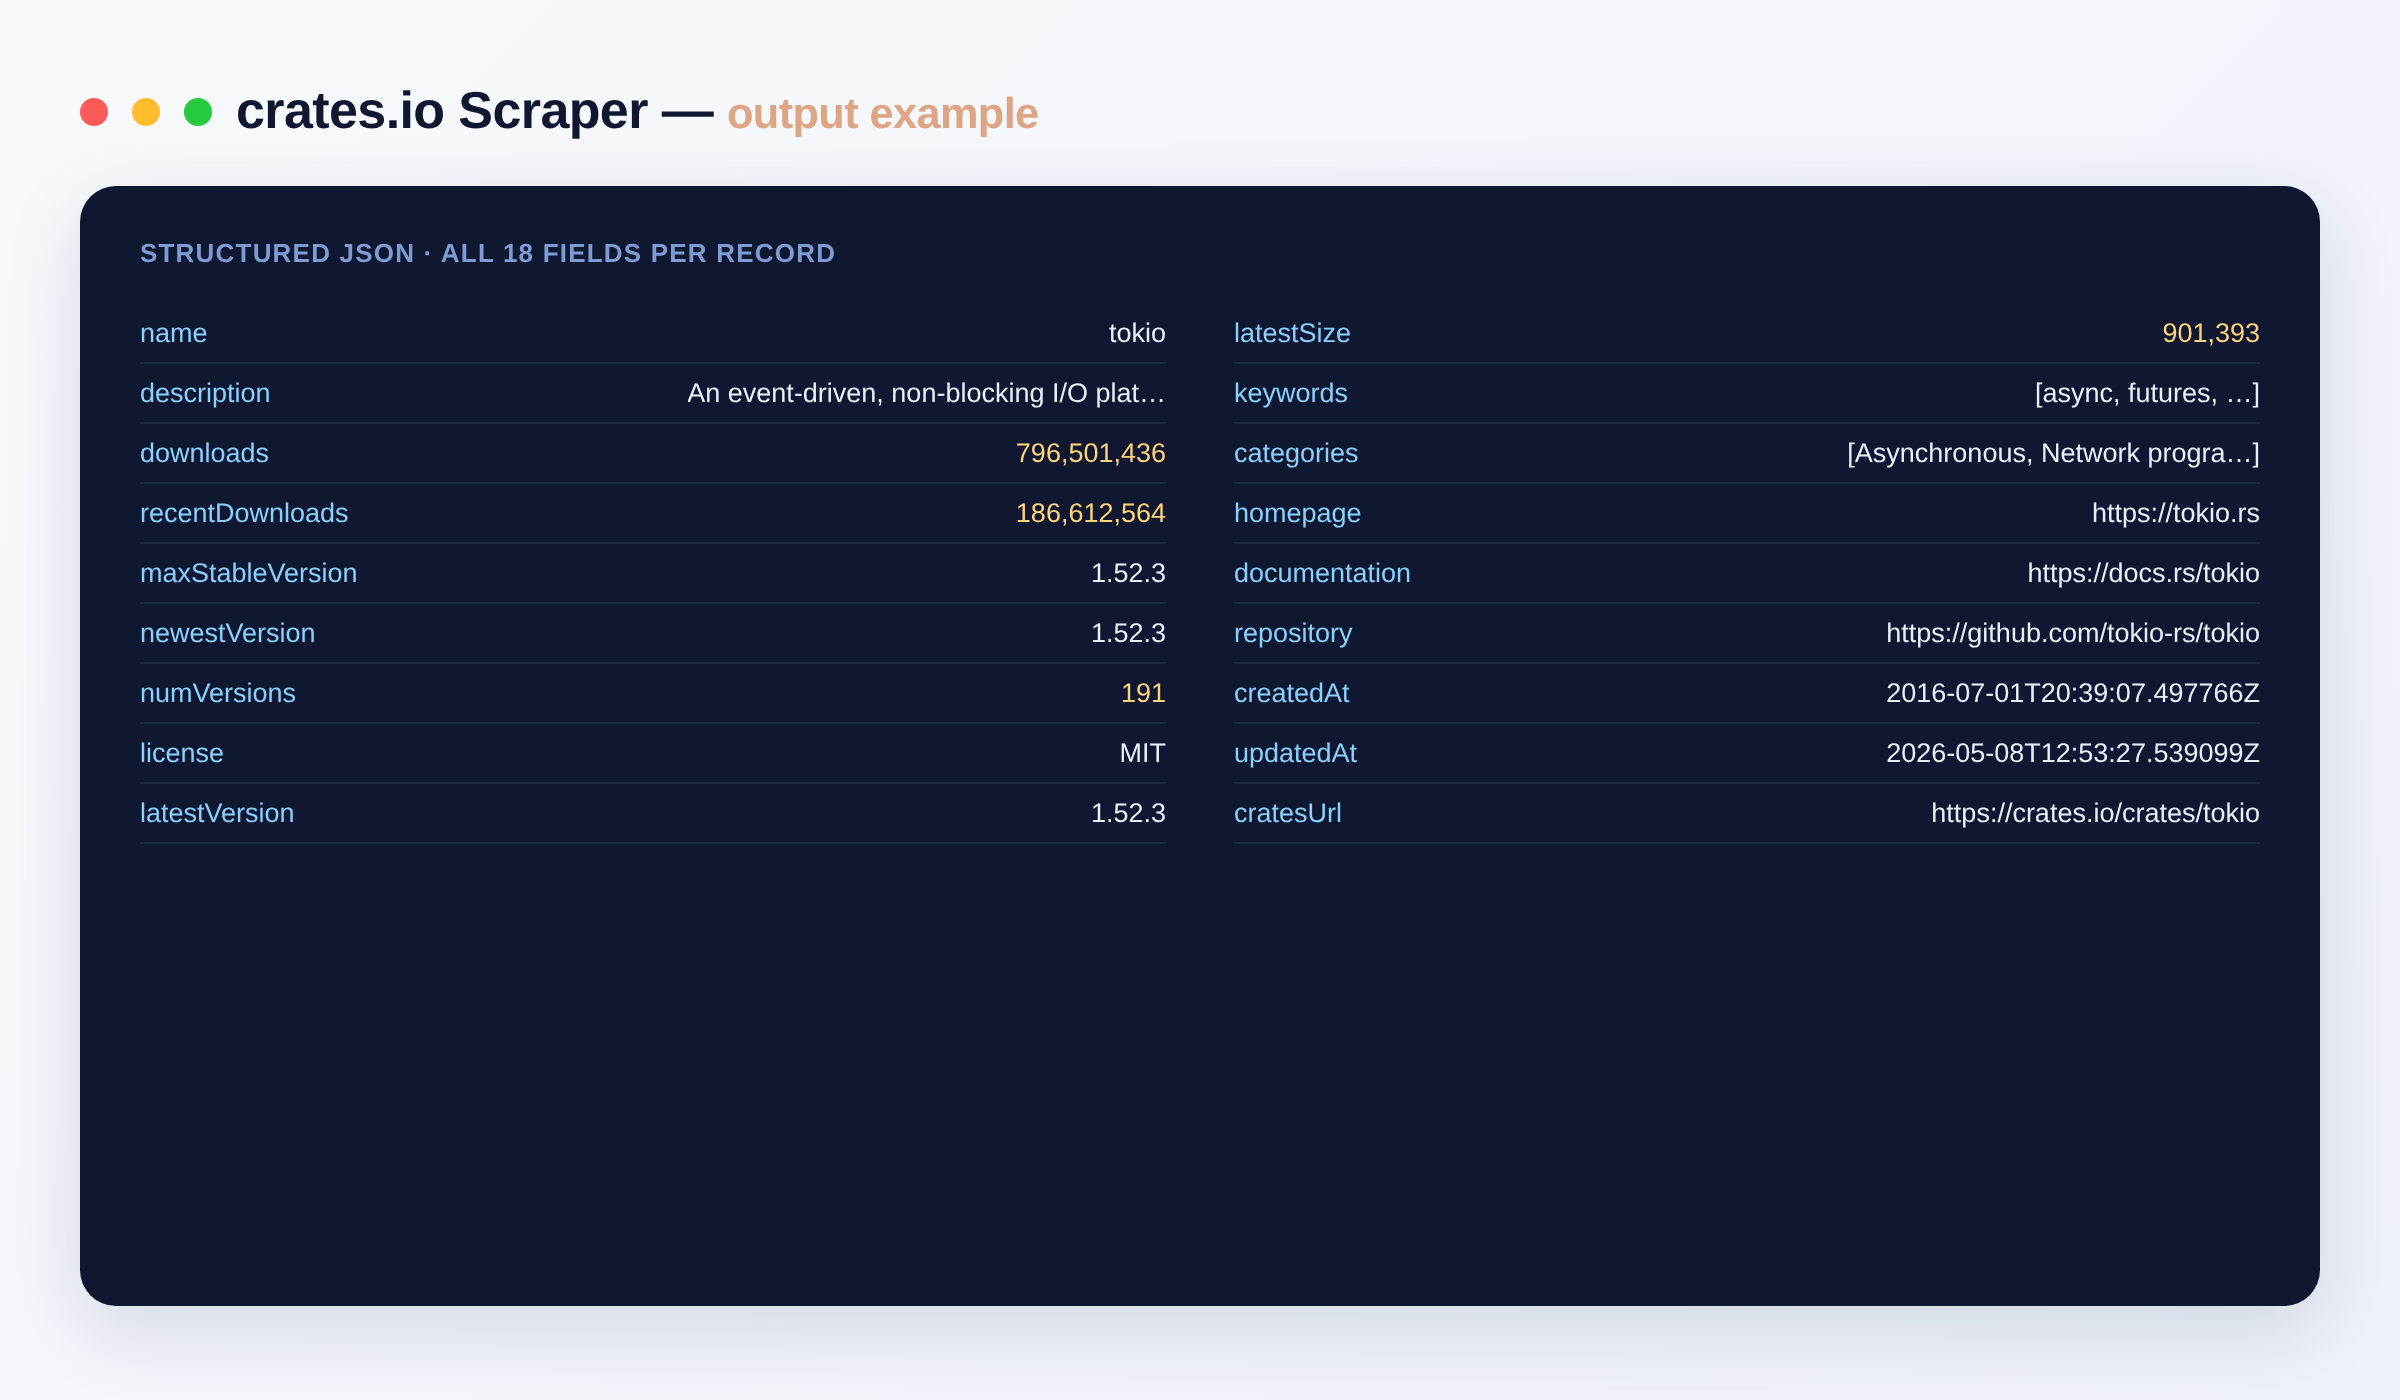
{
  "name": "tokio",
  "description": "An event-driven, non-blocking I/O platform for writing asynchronous I/O backed applications.",
  "downloads": 289456123,
  "recentDownloads": 41234567,
  "maxStableVersion": "1.38.0",
  "newestVersion": "1.38.0",
  "numVersions": 254,
  "license": "MIT",
  "latestVersion": "1.38.0",
  "latestSize": 812345,
  "keywords": ["async", "io", "non-blocking", "futures"],
  "categories": ["asynchronous", "network-programming"],
  "homepage": "https://tokio.rs",
  "documentation": "https://docs.rs/tokio",
  "repository": "https://github.com/tokio-rs/tokio",
  "createdAt": "2016-06-27T12:00:00.000000+00:00",
  "updatedAt": "2024-05-30T09:12:33.000000+00:00",
  "cratesUrl": "https://crates.io/crates/tokio"
}
Output schema
| Field | Type | Description |
|---|---|---|
name |
string | Crate name. |
description |
string | Short crate description. |
downloads |
integer | All-time download count. |
recentDownloads |
integer | Downloads in the recent period. |
maxStableVersion |
string | Highest stable version published. |
newestVersion |
string | Most recently published version (may be a pre-release). |
numVersions |
integer | Total number of published versions. |
license |
string | SPDX license identifier. |
latestVersion |
string | Version the detail metrics refer to. |
latestSize |
integer | Size of the latest version's .crate file in bytes. |
keywords |
array | Keywords assigned to the crate. |
categories |
array | crates.io categories the crate belongs to. |
homepage |
string (URL) | Project homepage URL. |
documentation |
string (URL) | Documentation URL (docs.rs fallback). |
repository |
string (URL) | Source repository URL. |
createdAt |
string (ISO date) | When the crate was first published. |
updatedAt |
string (ISO date) | When the crate was last updated. |
cratesUrl |
string (URL) | Canonical crates.io page for the crate. |
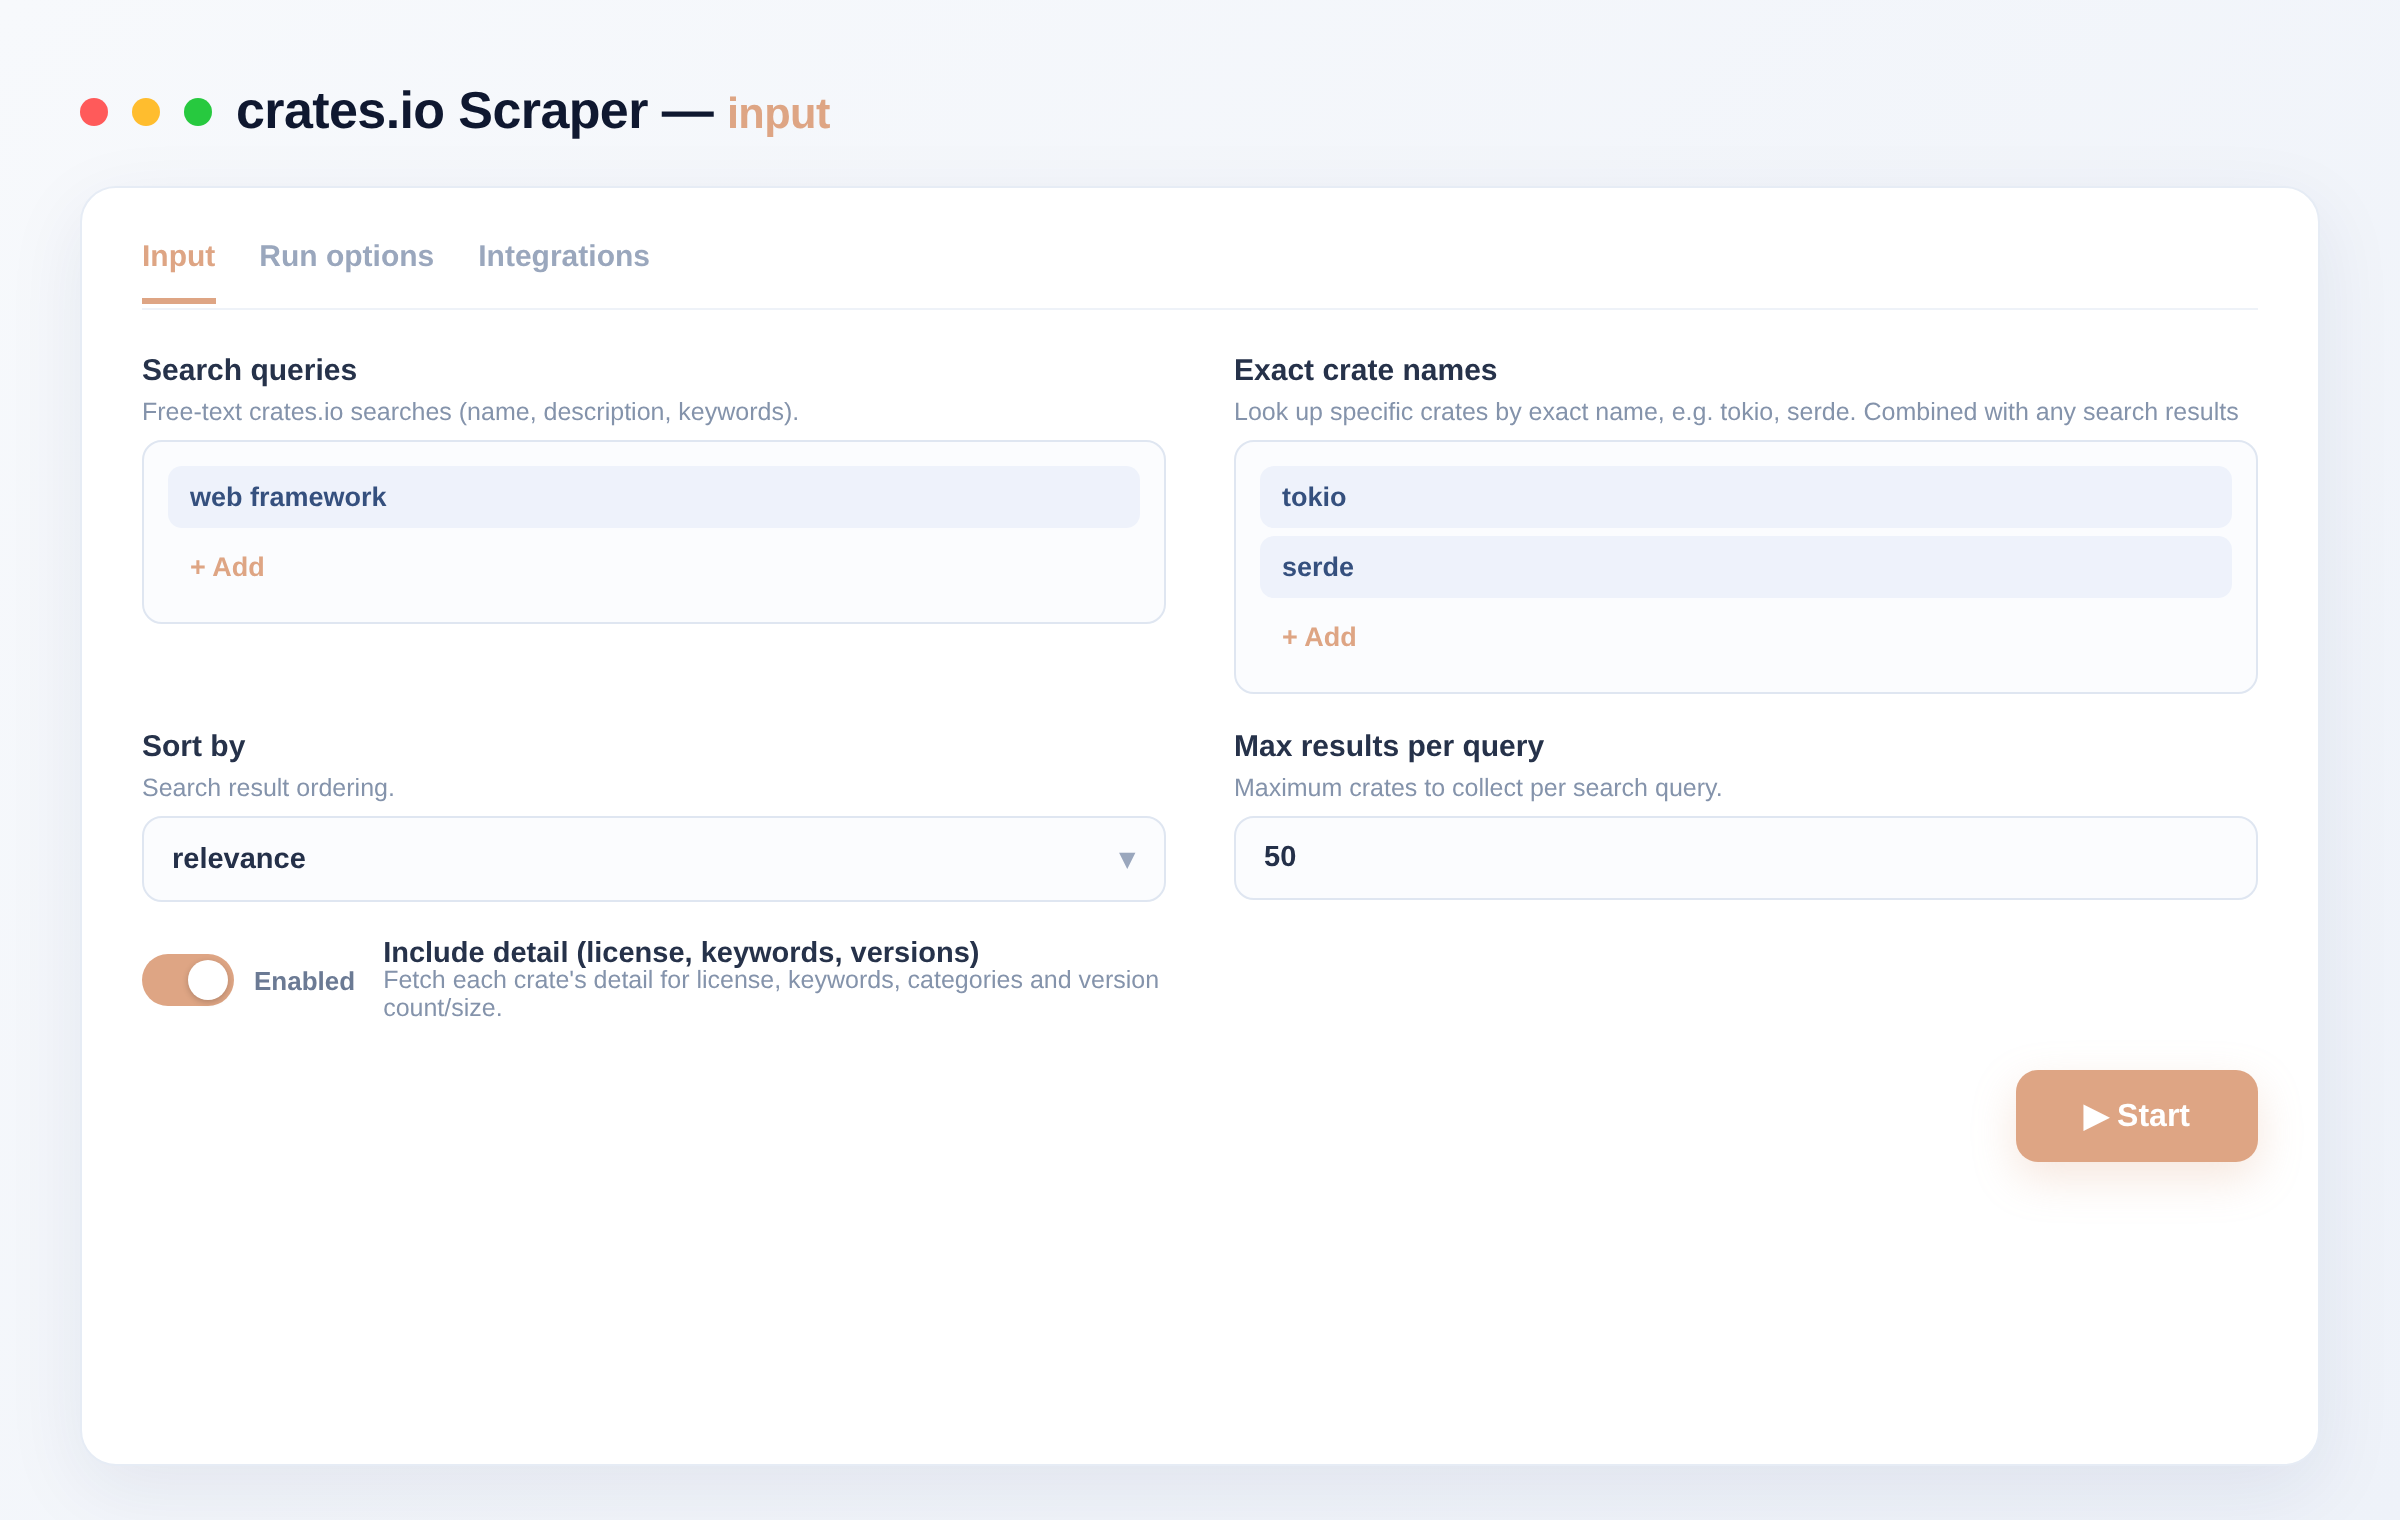
Input
{
  "queries": ["web framework", "async runtime"],
  "crates": ["tokio", "serde"],
  "sort": "downloads",
  "maxPerQuery": 50,
  "includeDetail": true
}
| Field | Description |
|---|---|
queries |
Free-text crates.io searches (name, description, keywords). Each is scraped separately. |
crates |
Exact crate names to look up, combined with any search results. |
sort |
Result ordering: relevance, downloads, recent-downloads, recent-updates or new. |
maxPerQuery |
Maximum crates to collect per search query (1–1000). |
includeDetail |
Fetch each crate's detail for license, keywords, categories and version count/size. |
Use cases
- Audit the licenses of crates used across your Rust workspace before shipping.
- Track download momentum to compare competing crates in a category.
- Build a catalog of crates for a topic (e.g. web frameworks) for research or content.
- Enrich an internal dependency dashboard with descriptions, versions and repo links.
Pricing
Pay-per-event: you're billed a small amount per run and per item scraped — you only pay for what you get. See the Pricing tab for current rates.
FAQ
Do I need a crates.io account or API key? No. The actor reads from the official crates.io public JSON API, so no account, login or API key is required.
How many crates can I scrape per run?
Each free-text query can return up to 1000 crates (maxPerQuery), and you can add any number of exact crate names like tokio or serde in the crates field, all in one run.
Is scraping crates.io allowed? This actor only reads publicly available crate data through the official crates.io API and sends a descriptive User-Agent as their crawler policy requests. Review the crates.io usage policy before large-scale or commercial reuse.
What's the output format?
Structured JSON — one record per crate with fields such as description, downloads, recentDownloads, maxStableVersion, license, keywords, categories and repository/docs links. Export as JSON, CSV, Excel or via the API.
Can I sort or filter results?
Yes. Use sort to order results by relevance, all-time downloads, recent downloads, recent updates or newest, and set includeDetail to add license, keywords, categories and version count/size per crate.
Can I connect this Actor to other apps? The crates.io Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Tracking packages across ecosystems? Pair this with our other developer-data scrapers:
- npm Package Scraper — search and look up npm packages with metadata, dependencies and downloads.
- PyPI Package Scraper — metadata, dependencies, licenses and downloads for Python packages.
- GitHub Scraper — repositories and user profiles with stars, topics, licenses and leads.
- Docker Hub Scraper — image metadata, pulls, stars and tags from Docker Hub.
Notes
This actor uses the public crates.io JSON API and reads only publicly available package data. It is an independent tool and is not affiliated with, endorsed by, or sponsored by crates.io or the Rust Foundation; "crates.io" and "Rust" are trademarks of their respective owners.
Input
| Field | Type | Description |
|---|---|---|
queriesSearch queries | array | Free-text crates.io searches (name, description, keywords). |
cratesExact crate names | array | Look up specific crates by exact name, e.g. tokio, serde. Combined with any search results. |
sortSort by | string · relevance, downloads, recent-downloads, recent-updates, new | Search result ordering. Default: "relevance" |
maxPerQueryMax results per query | integer | Maximum crates to collect per search query. Default: 50 |
includeDetailInclude detail (license, keywords, versions) | boolean | Fetch each crate's detail for license, keywords, categories and version count/size. Default: true |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~crates-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "queries": [
    "web framework"
  ],
  "crates": [
    "tokio",
    "serde"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/crates-scraper").call(run_input={
"queries": [
"web framework"
],
"crates": [
"tokio",
"serde"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/crates-scraper').call({
"queries": [
"web framework"
],
"crates": [
"tokio",
"serde"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Crate scraped One Rust crate with description, downloads, version, license, keywords, categories and repository | $0.004 | $0.002 |
| Search request One crates.io search page (up to 100 results) | $0.001 | $0.001 |
| API request One crate detail fetch (license, keywords, versions) | $0.0003 | $0.0003 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Bulk Image Downloader
Download thousands of images from a list of URLs and store each in the key-value store with a public link. Returns content type, size, dimensions and SHA-256 per image. Bulk-ready. Great for datasets, backups and media pipelines.
8,102 runs · 103 users · $0.056 / url processed
Text to Speech
Convert any text to natural-sounding speech as an MP3 download. 300+ premium neural voices across 70+ languages, adjustable rate, pitch and volume. Great for voiceovers, videos, accessibility and audio content. No setup.
278 runs · 22 users · $0.01 / audio generated
Google Maps Email Extractor
Search Google Maps for businesses, then crawl each business website to extract emails, social profiles and extra phone numbers. Turns any Maps search into a ready lead list. No setup.
159 runs · 8 users · $0.006 / business lead scraped
Website Screenshot
Capture full-page or viewport screenshots of any URL as PNG or JPEG, at any device size. For monitoring, previews, thumbnails and automation workflows.
156 runs · 3 users · $0.004 / screenshot captured
Bulk URL Status Checker
Check thousands of URLs over plain HTTP: status codes, broken links (404/410/5xx), full redirect chains, response time, content type, page title and SSL certificate expiry.
154 runs · 13 users · $0.002 / url checked
Google Search Scraper
Scrape Google Search results (organic listings) for any query: title, URL, displayed URL, snippet and position. Multi-query, per-country/language, pagination. Uses Google SERP proxy — reliable, no captcha, no setup.
121 runs · 8 users · $0.001 / result scrapedSend the site and the fields. We build it and you get it first.