Scrapers / Developer & File Tools
Bulk Image Downloader
hipersoft/bulk-image-downloader
Download thousands of images from a list of URLs and store each in the key-value store with a public link. Returns content type, size, dimensions and SHA-256 per image. Bulk-ready. Great for datasets, backups and media pipelines.
Total users
103Monthly users
24Total runs
8,102Per url processed
$0.056Last rebuilt
Oct 26, 2026Overview
Bulk Image Downloader takes a list of image URLs and downloads every one, stores each file in your run's key-value store, and returns its content type, size, pixel dimensions and SHA-256 hash plus a direct link to the stored file. Export the metadata to JSON, CSV, Excel or XML. Fast and reliable, with no login or API key to run. Great for building image datasets, mirroring and backups, media pipelines and deduplicating creative assets.
What does the Bulk Image Downloader do?
Give it hundreds or thousands of image URLs and it fetches each one in parallel, saves the bytes to your run storage, and records a metadata row per image. The result is a clean dataset you can filter, deduplicate by hash, or wire into a downstream media pipeline.
What data do you get per image?
| Data point | Description |
|---|---|
| Source | url, finalUrl |
| Status | ok, error |
| File info | contentType, sizeBytes |
| Dimensions | width, height |
| Hash | sha256 |
| Storage | key, storedUrl |
What you get
Each image produces one metadata row plus the stored file itself. Export the dataset to JSON, CSV, Excel or XML.
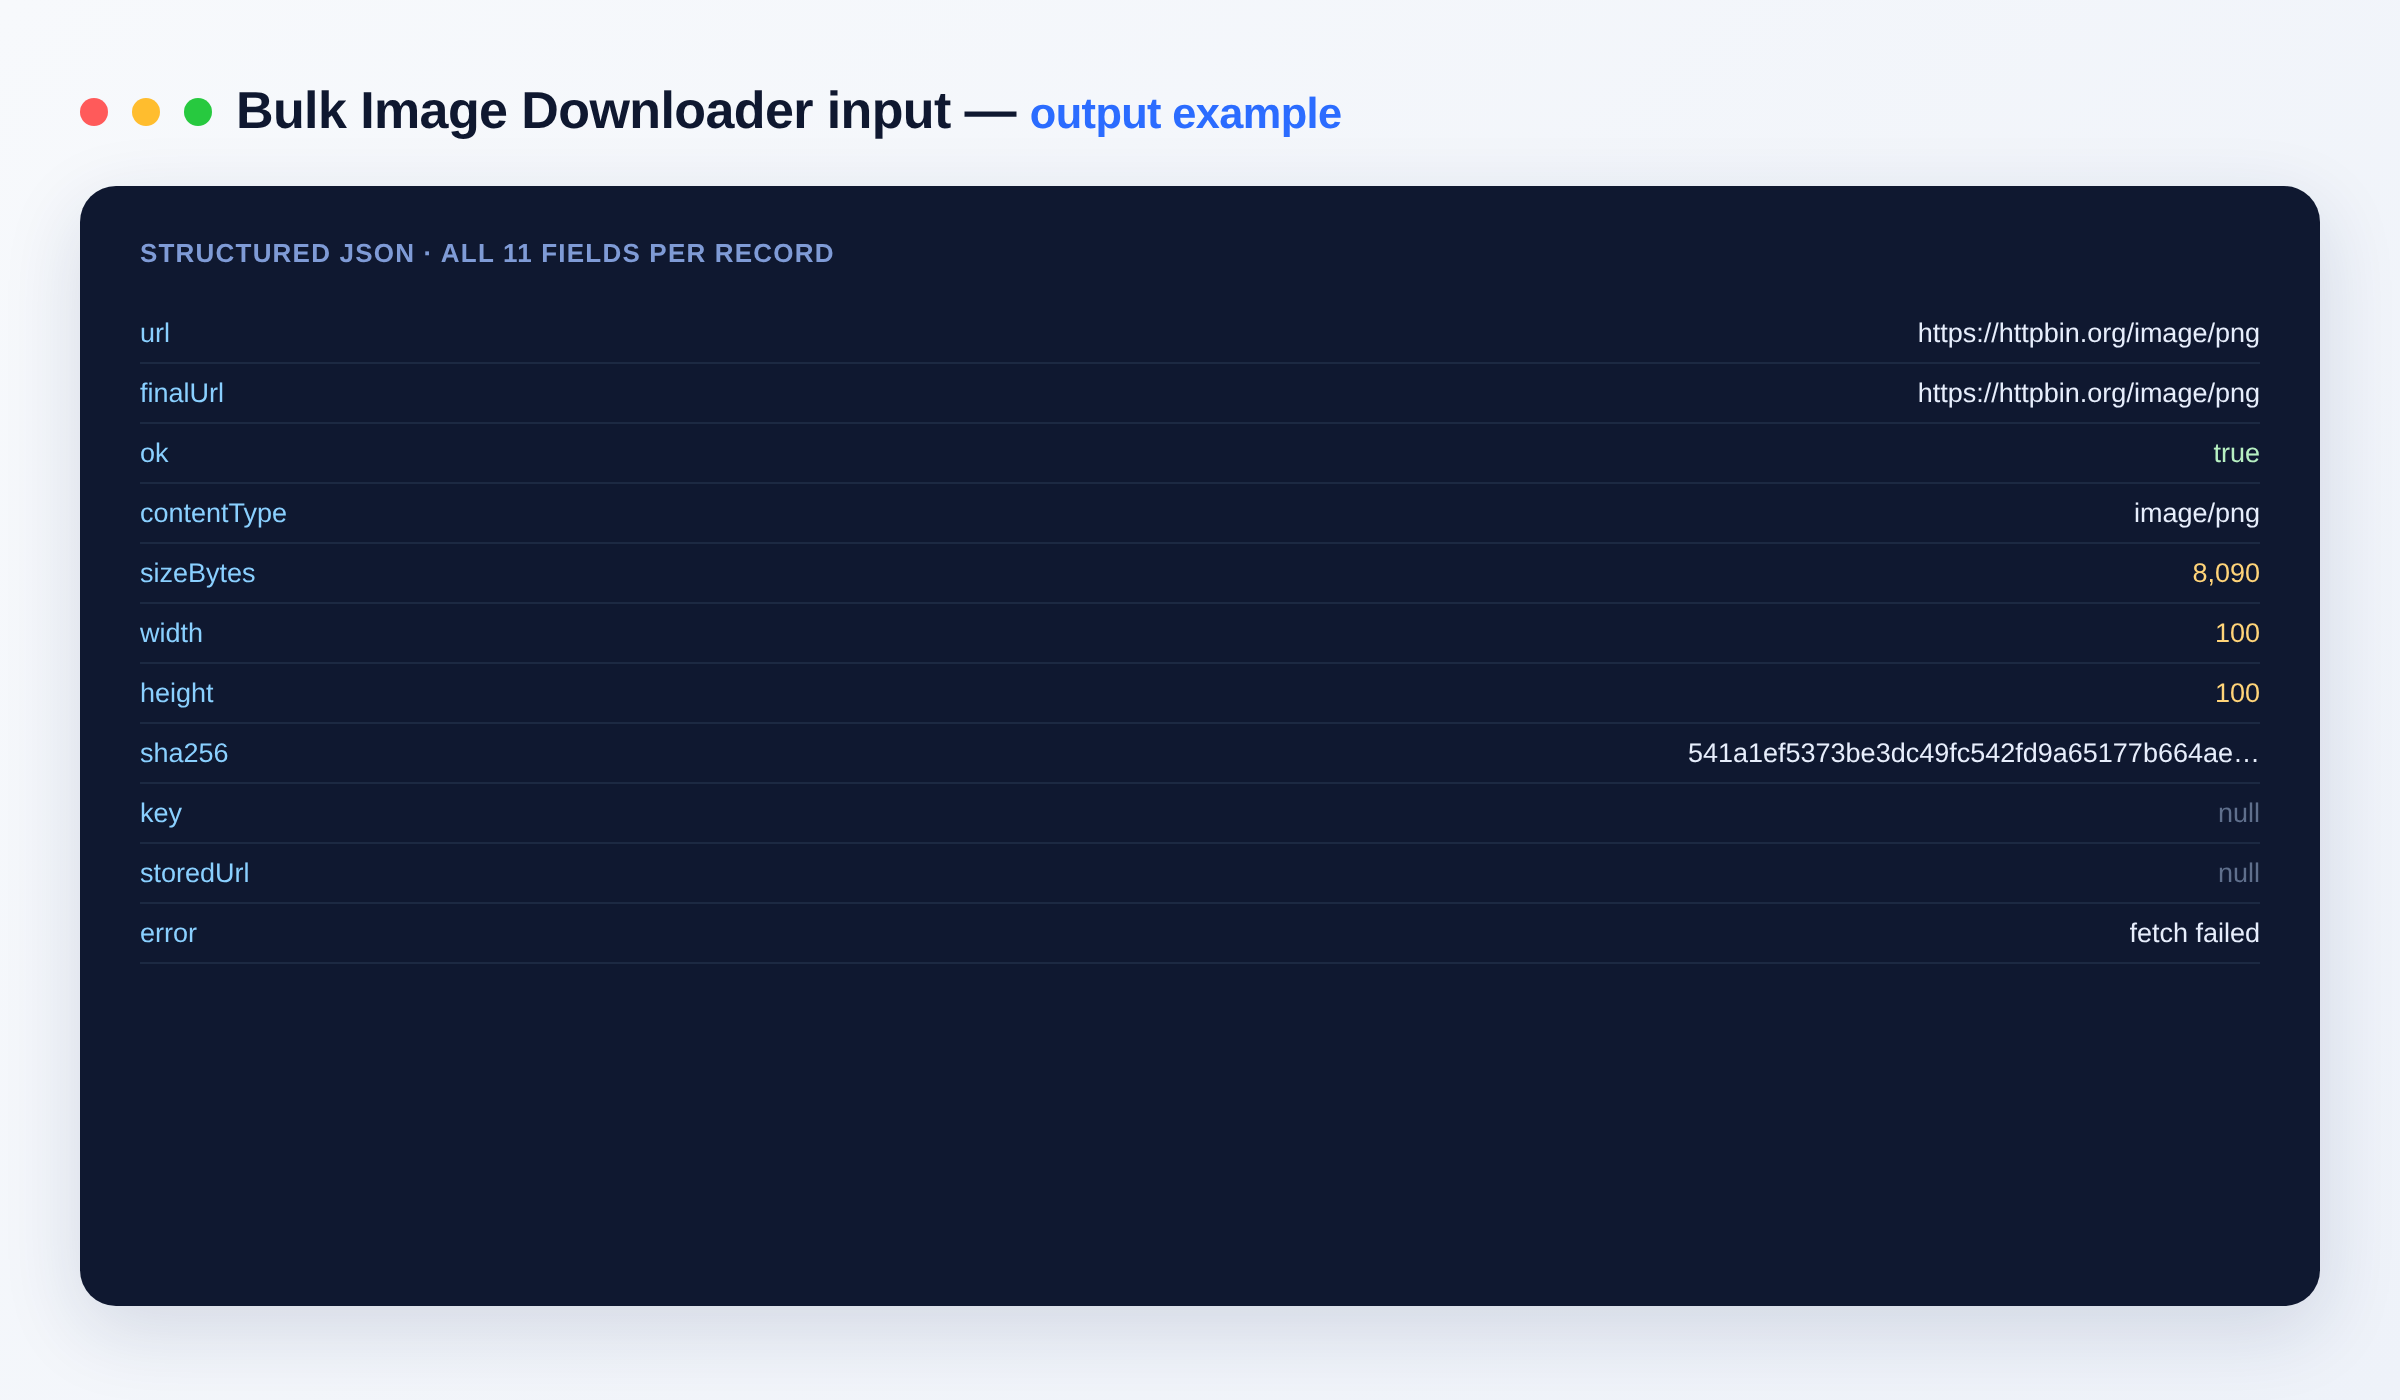
{
  "url": "https://example.com/a.jpg",
  "finalUrl": "https://example.com/a.jpg",
  "ok": true,
  "contentType": "image/jpeg",
  "sizeBytes": 84213,
  "width": 1200,
  "height": 800,
  "sha256": "9f86d081884c7d659a2feaa0c55ad015a3bf4f1b2b0b822cd15d6c15b0f00a08",
  "key": "image-000000-9f86d0817640.jpg",
  "storedUrl": "https://api.apify.com/v2/key-value-stores/<id>/records/image-000000-9f86d0817640.jpg",
  "error": null
}
Output schema
| Field | Type | Description |
|---|---|---|
url |
string (URL) | The image URL you supplied. |
finalUrl |
string (URL) | The URL after any redirects were followed. |
ok |
boolean | Whether the download succeeded. |
contentType |
string | MIME type of the file (e.g. image/jpeg, image/png, image/webp). |
sizeBytes |
integer | File size in bytes. |
width |
integer | Image width in pixels, read from the file header. |
height |
integer | Image height in pixels, read from the file header. |
sha256 |
string | SHA-256 hash of the file contents, useful for deduplication. |
key |
string | The record key of the stored file in the run's key-value store. |
storedUrl |
string | Direct link to the stored file in your run's key-value store. |
error |
string | Failure reason when a download did not succeed; empty otherwise. |
Use cases
- Build labelled image datasets for machine learning or research.
- Mirror and back up image assets from a list of URLs.
- Deduplicate creative libraries using the SHA-256 content hash.
- Feed a media processing or thumbnailing pipeline.
- Validate that a set of image links are live and return the expected files.
How to download images in bulk
- Add the Bulk Image Downloader to your Apify account and open its input.
- Paste your image URLs under
imageUrls, one per line. - Set
store,maxBytes,maxConcurrencyandmaxItemsto suit your run. - Click Run and let it fetch and store every image.
- Export the metadata dataset as JSON, CSV, Excel or XML, and download the stored files as a zip from the run's Storage tab.
Input
{
  "imageUrls": ["https://example.com/a.jpg", "https://example.com/b.png"],
  "store": true,
  "maxConcurrency": 10
}
| Field | Description |
|---|---|
imageUrls |
Direct image URLs, one per line. |
store |
Save the bytes and return a link (default on). Off = metadata only. |
maxBytes |
Skip images larger than this size. |
maxConcurrency |
Number of parallel downloads (default 10). |
maxItems |
Global cap on the number of images processed. |
proxyConfiguration |
Optional proxy settings for the run. |
Related tools
- Bulk URL Status Checker — check thousands of links for broken status, redirects and SSL.
- Website Contact Scraper — pull emails, phones and social links from any site.
- Website Content Crawler — crawl a site into clean text and discover asset URLs.
- Wayback Machine Scraper — list archived snapshots of a URL or domain.
FAQ
Do I need an account or API key? No API key is needed to run it. Downloaded files are saved to your run's key-value store, which you open in the Apify Console or fetch with your own API token.
How many images can I download per run?
As many as you supply. maxItems sets a global cap, maxConcurrency controls parallel downloads (default 10), and maxBytes skips files larger than a chosen size.
What export formats are supported? A JSON/CSV/Excel/XML dataset with one metadata row per image, plus the stored files themselves. Bulk-download the whole store as a zip from the run's Storage tab.
Can I filter or limit results?
Yes. Use maxItems, maxBytes and maxConcurrency, and set store to false to return metadata only without saving the bytes.
How does billing work? You pay per item you get, so cost scales with the number of images you actually process. See the Pricing tab for current rates.
Can I connect this to other tools? The Bulk Image Downloader can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Is bulk image downloading legal? Only download images you have the right to use. You are responsible for the copyright and terms of the sources.
Notes
Original clean-room implementation. Files are saved to your run's key-value store and are private to your account, as with all Apify runs. Only download images you have the right to use.
Input
| Field | Type | Description |
|---|---|---|
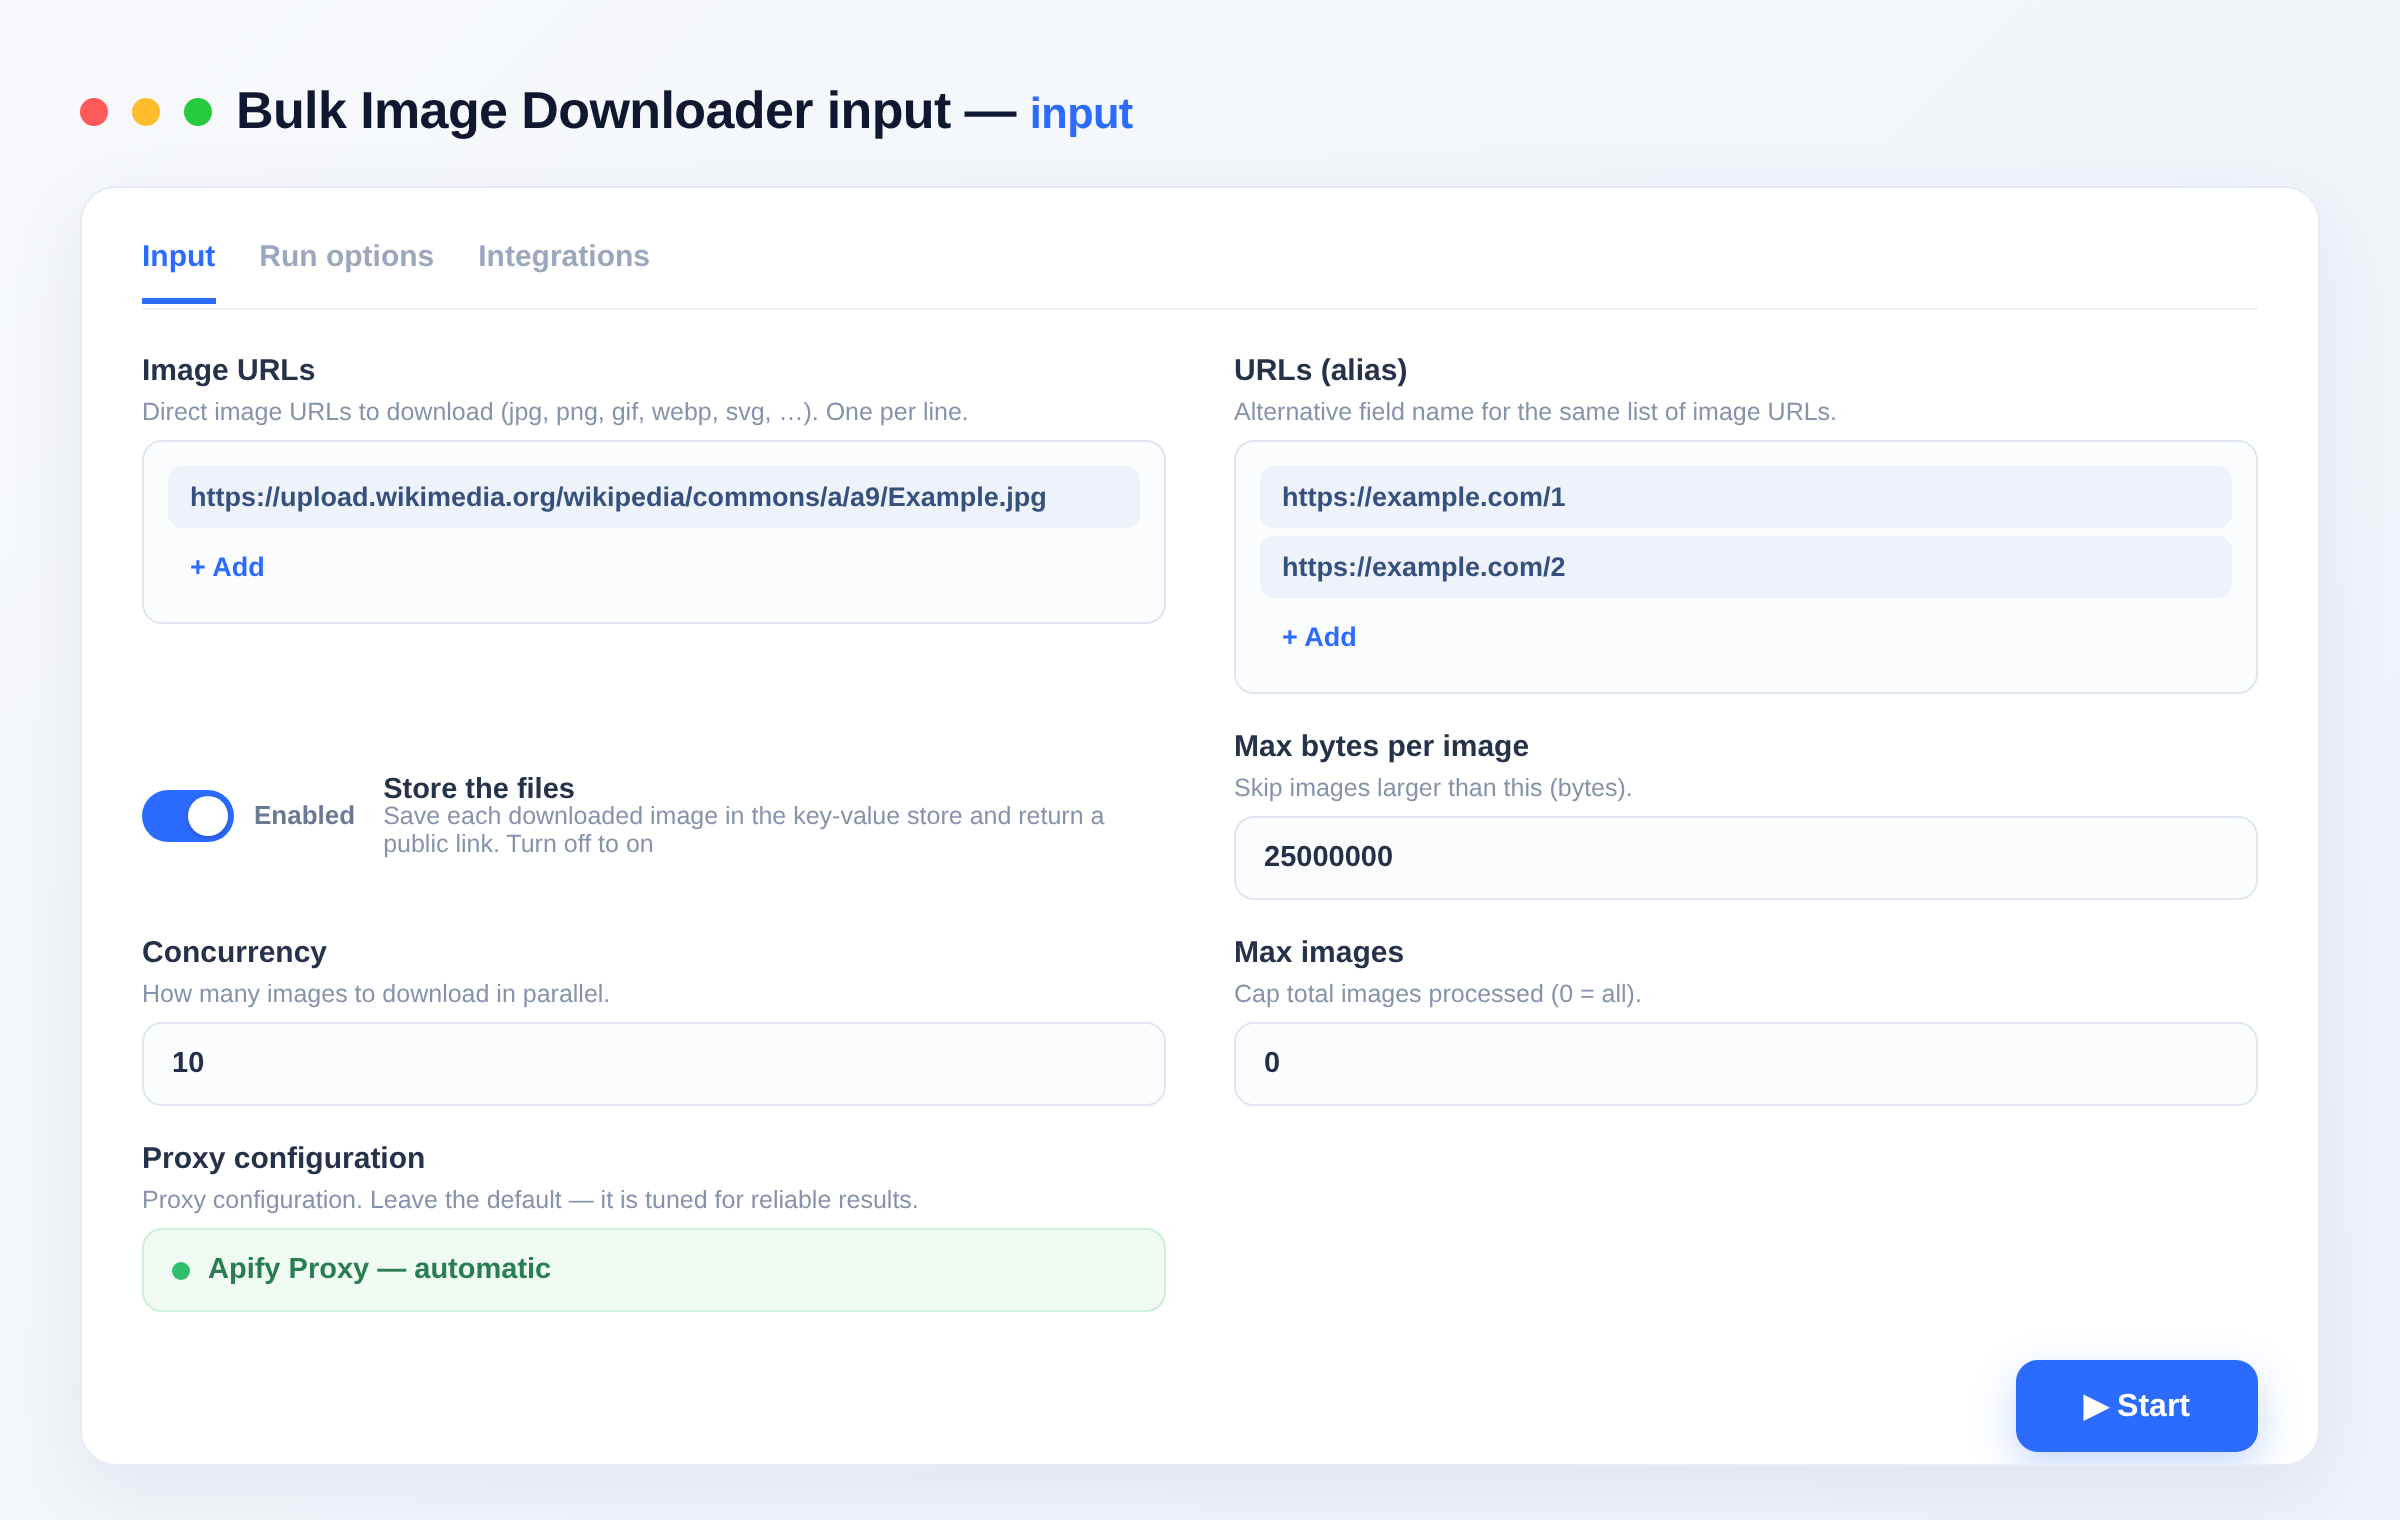
imageUrlsImage URLs | array | Direct image URLs to download (jpg, png, gif, webp, svg, …). One per line. |
urlsURLs (alias) | array | Alternative field name for the same list of image URLs. |
storeStore the files | boolean | Save each downloaded image in the key-value store and return a public link. Turn off to only collect metadata (type/size/dimensions/hash) without storing bytes. Default: true |
maxBytesMax bytes per image | integer | Skip images larger than this (bytes). Default: 25000000 |
maxConcurrencyConcurrency | integer | How many images to download in parallel. Default: 10 |
maxItemsMax images | integer | Cap total images processed (0 = all). Default: 0 |
proxyConfigurationProxy configuration | object | Proxy configuration. Leave the default — it is tuned for reliable results. Default: {"useApifyProxy": false} |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~bulk-image-downloader/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "imageUrls": [
    "https://upload.wikimedia.org/wikipedia/commons/a/a9/Example.jpg"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/bulk-image-downloader").call(run_input={
"imageUrls": [
"https://upload.wikimedia.org/wikipedia/commons/a/a9/Example.jpg"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/bulk-image-downloader').call({
"imageUrls": [
"https://upload.wikimedia.org/wikipedia/commons/a/a9/Example.jpg"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| URL processed One image URL fetched, stored and measured (type, size, dimensions, SHA-256) | $0.056 | $0.028 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Text to Speech
Convert any text to natural-sounding speech as an MP3 download. 300+ premium neural voices across 70+ languages, adjustable rate, pitch and volume. Great for voiceovers, videos, accessibility and audio content. No setup.
278 runs · 22 users · $0.01 / audio generated
Google Maps Email Extractor
Search Google Maps for businesses, then crawl each business website to extract emails, social profiles and extra phone numbers. Turns any Maps search into a ready lead list. No setup.
159 runs · 8 users · $0.006 / business lead scraped
Website Screenshot
Capture full-page or viewport screenshots of any URL as PNG or JPEG, at any device size. For monitoring, previews, thumbnails and automation workflows.
156 runs · 3 users · $0.004 / screenshot captured
Bulk URL Status Checker
Check thousands of URLs over plain HTTP: status codes, broken links (404/410/5xx), full redirect chains, response time, content type, page title and SSL certificate expiry.
154 runs · 13 users · $0.002 / url checked
Google Search Scraper
Scrape Google Search results (organic listings) for any query: title, URL, displayed URL, snippet and position. Multi-query, per-country/language, pagination. Uses Google SERP proxy — reliable, no captcha, no setup.
121 runs · 8 users · $0.001 / result scraped
crates.io Scraper
Search crates.io or look up exact Rust crates and get description, downloads, versions, license, keywords, categories, repository and documentation links.
118 runs · 1 users · $0.004 / crate scrapedSend the site and the fields. We build it and you get it first.