PyPI Package Scraper
hipersoft/pypi-scraper
Look up Python packages on PyPI: version, summary, author, license, Python requirement, dependencies, project links, release history and download counts. Ideal for dependency, license and security auditing. Clean, no setup.
Total users
1Monthly users
1Total runs
119Per package scraped
$0.0037Last rebuilt
Oct 26, 2026Overview
Look up Python packages on PyPI by exact name and get back clean, structured JSON: version, summary, author, license, Python requirement, dependencies, project links, release history and day/week/month download counts. It pulls from the official PyPI JSON API plus pypistats.org — no account, no API key. Ideal for dependency, license and security auditing straight from a requirements.txt or poetry.lock.
Features
- 🎯 Exact lookups — paste package names (
requests,fastapi,numpy) straight from your lockfile. - 🧾 License intelligence — derives a clean
licensefrom the manifest field, license expression or classifiers. - 🔗 Dependencies — normalized
dependencieslist plus rawdependenciesRawrequirement specifiers and a count. - 🐍 Python support —
requiresPythonand the fullpythonVersionslist parsed from classifiers. - 📈 Download counts — optional last day/week/month figures from pypistats.org.
- 🗓️ Release history — optional
recentReleaseswith the 10 most recent versions and upload dates. - 🔗 Project links —
homepage,repository,documentationand the fullprojectUrlsmap.
What you get
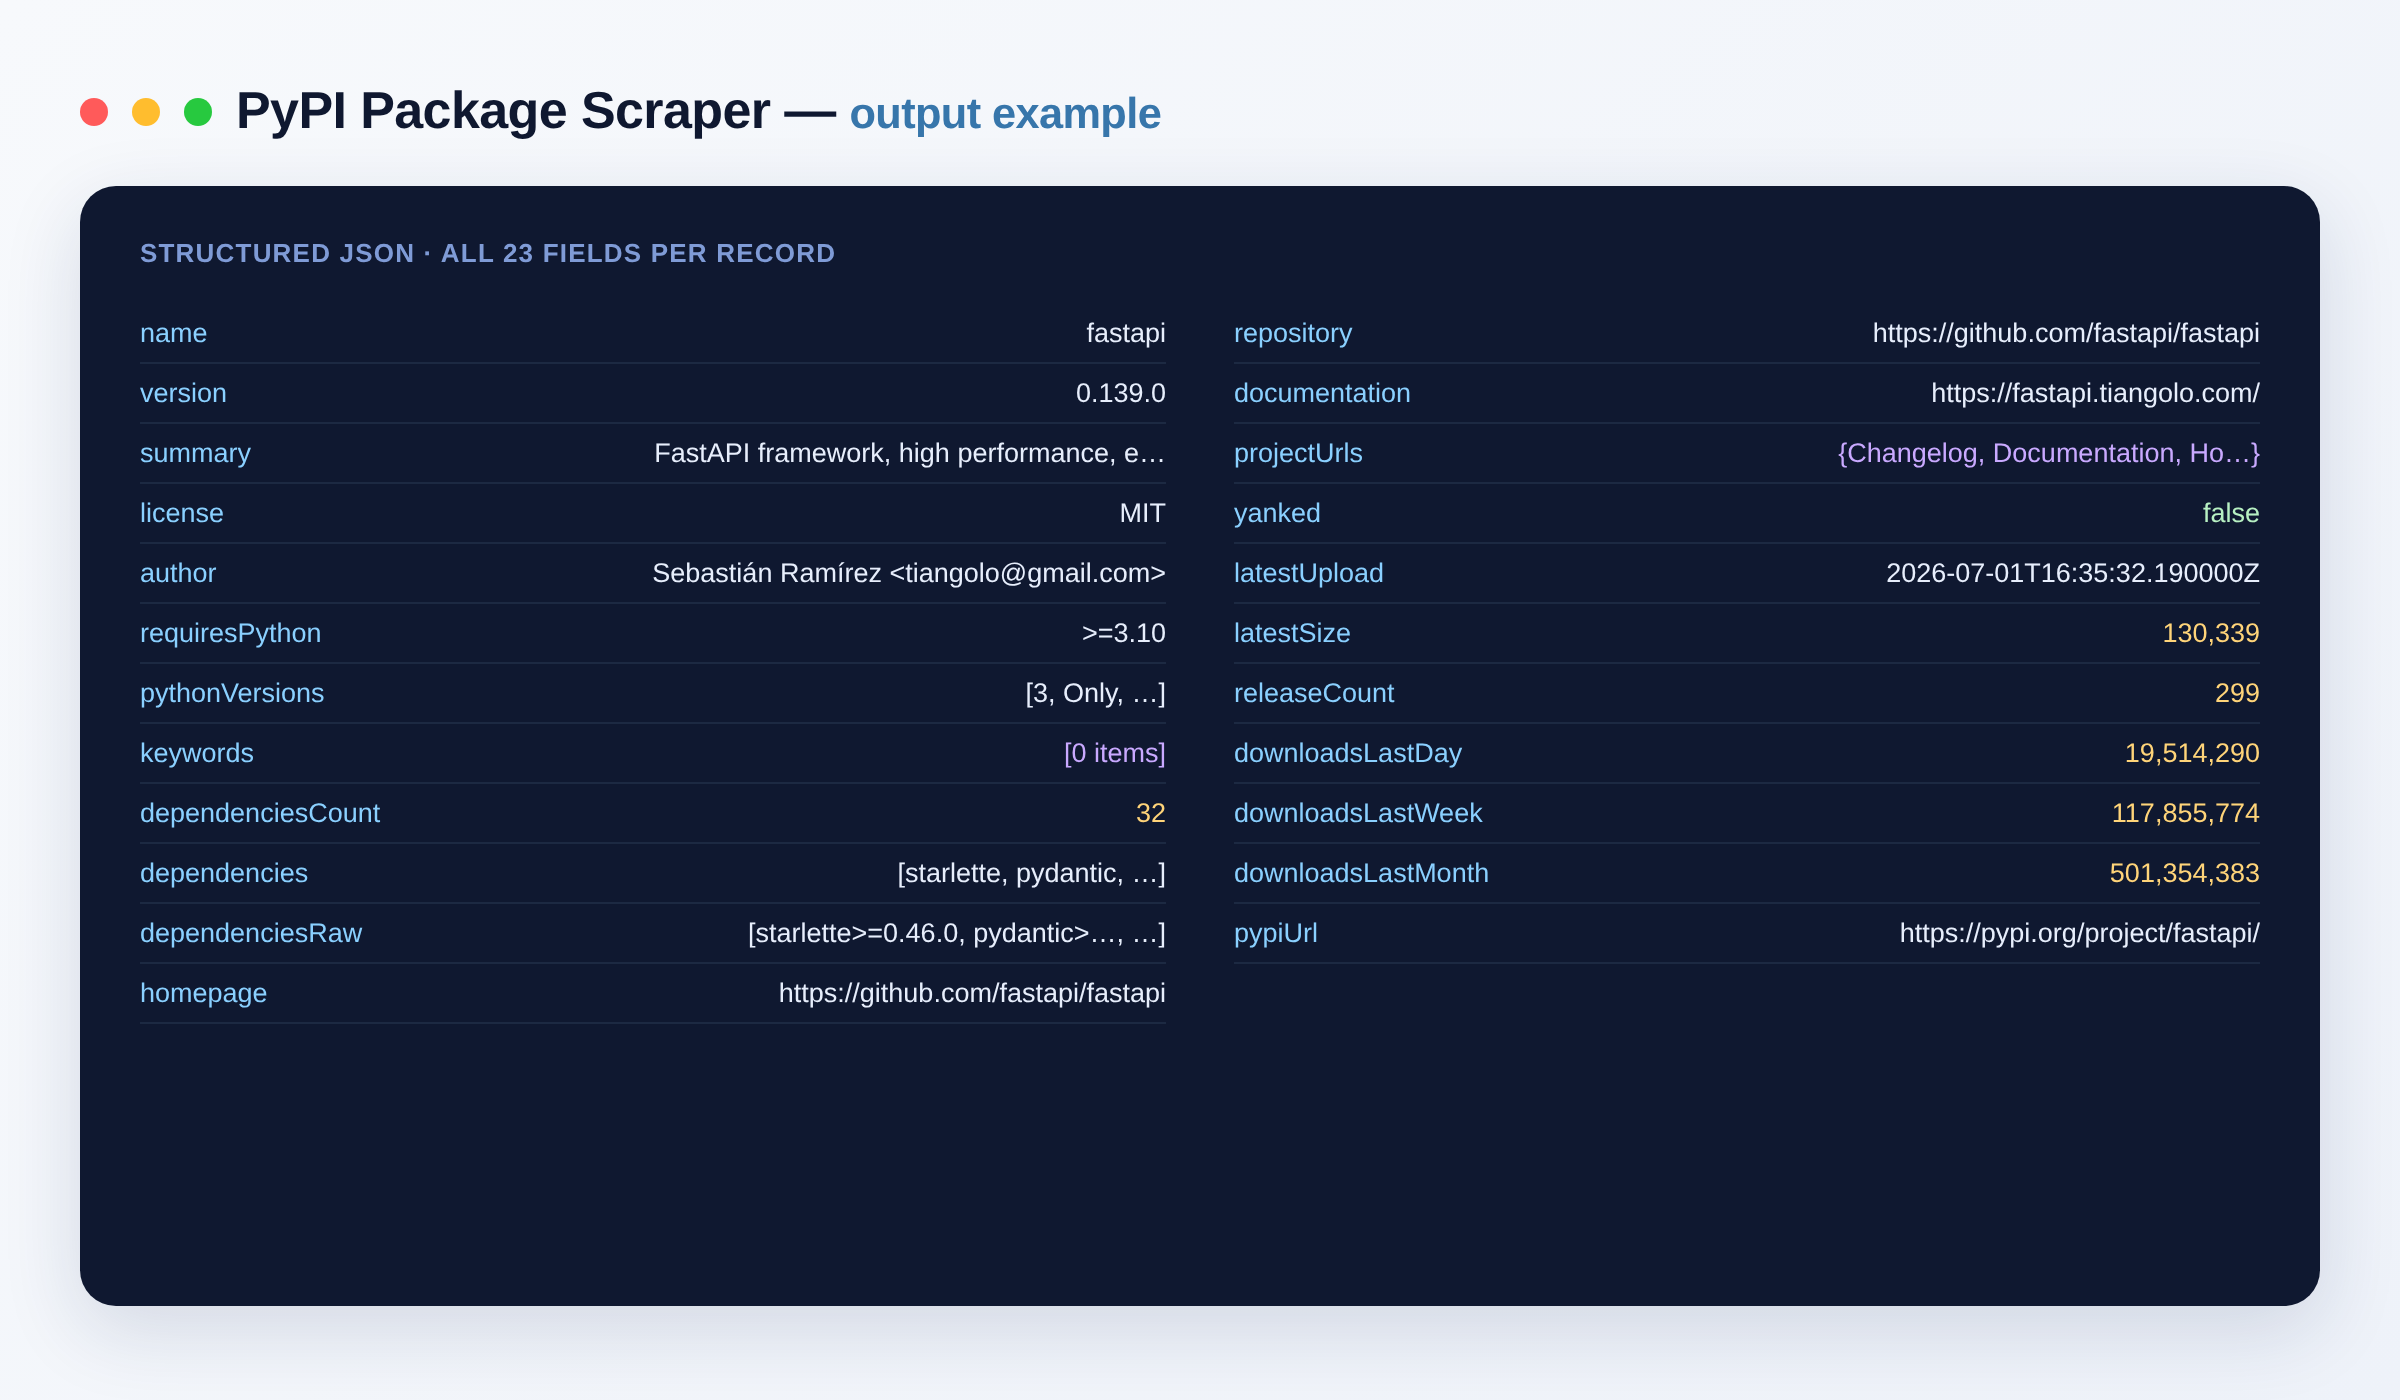
Each package becomes one clean JSON record:
{
  "name": "requests",
  "version": "2.32.3",
  "summary": "Python HTTP for Humans.",
  "license": "Apache-2.0",
  "author": "Kenneth Reitz",
  "requiresPython": ">=3.8",
  "pythonVersions": ["3", "3.8", "3.9", "3.10", "3.11", "3.12"],
  "keywords": [],
  "dependenciesCount": 5,
  "dependencies": ["charset-normalizer", "idna", "urllib3", "certifi", "PySocks"],
  "dependenciesRaw": ["charset-normalizer (<4,>=2)", "idna (<4,>=2.5)", "urllib3 (<3,>=1.21.1)", "certifi (>=2017.4.17)", "PySocks (!=1.5.7,>=1.5.6) ; extra == 'socks'"],
  "homepage": "https://requests.readthedocs.io",
  "repository": "https://github.com/psf/requests",
  "documentation": "https://requests.readthedocs.io",
  "projectUrls": { "Homepage": "https://requests.readthedocs.io", "Source": "https://github.com/psf/requests" },
  "yanked": false,
  "latestUpload": "2024-05-29T15:37:49.000000Z",
  "latestSize": 64928,
  "releaseCount": 156,
  "downloadsLastDay": 2712345,
  "downloadsLastWeek": 18934512,
  "downloadsLastMonth": 81234567,
  "pypiUrl": "https://pypi.org/project/requests/"
}
Output schema
| Field | Type | Description |
|---|---|---|
name |
string | Package name on PyPI. |
version |
string | Latest published version. |
summary |
string | Short package description. |
license |
string | Resolved license from manifest, expression or classifiers. |
author |
string | Package author name. |
requiresPython |
string | Python version requirement specifier. |
pythonVersions |
array | Supported Python versions parsed from classifiers. |
keywords |
array | Keywords declared by the package. |
dependenciesCount |
integer | Number of runtime dependencies. |
dependencies |
array | Normalized dependency package names. |
dependenciesRaw |
array | Raw dependency requirement specifiers. |
homepage |
string | Package homepage URL. |
repository |
string (URL) | Source code repository link. |
documentation |
string (URL) | Documentation link. |
projectUrls |
object | Map of all declared project links. |
yanked |
boolean | Whether the latest release was yanked. |
latestUpload |
string (ISO date) | Upload timestamp of the latest release. |
latestSize |
integer | Size in bytes of the latest release file. |
releaseCount |
integer | Total number of released versions. |
downloadsLastDay |
integer | Downloads in the last day. |
downloadsLastWeek |
integer | Downloads in the last week. |
downloadsLastMonth |
integer | Downloads in the last month. |
pypiUrl |
string (URL) | Link to the package page on PyPI. |
Input
{
  "packages": ["requests", "fastapi", "numpy"],
  "includeDownloads": true,
  "includeReleases": false
}
| Field | Description |
|---|---|
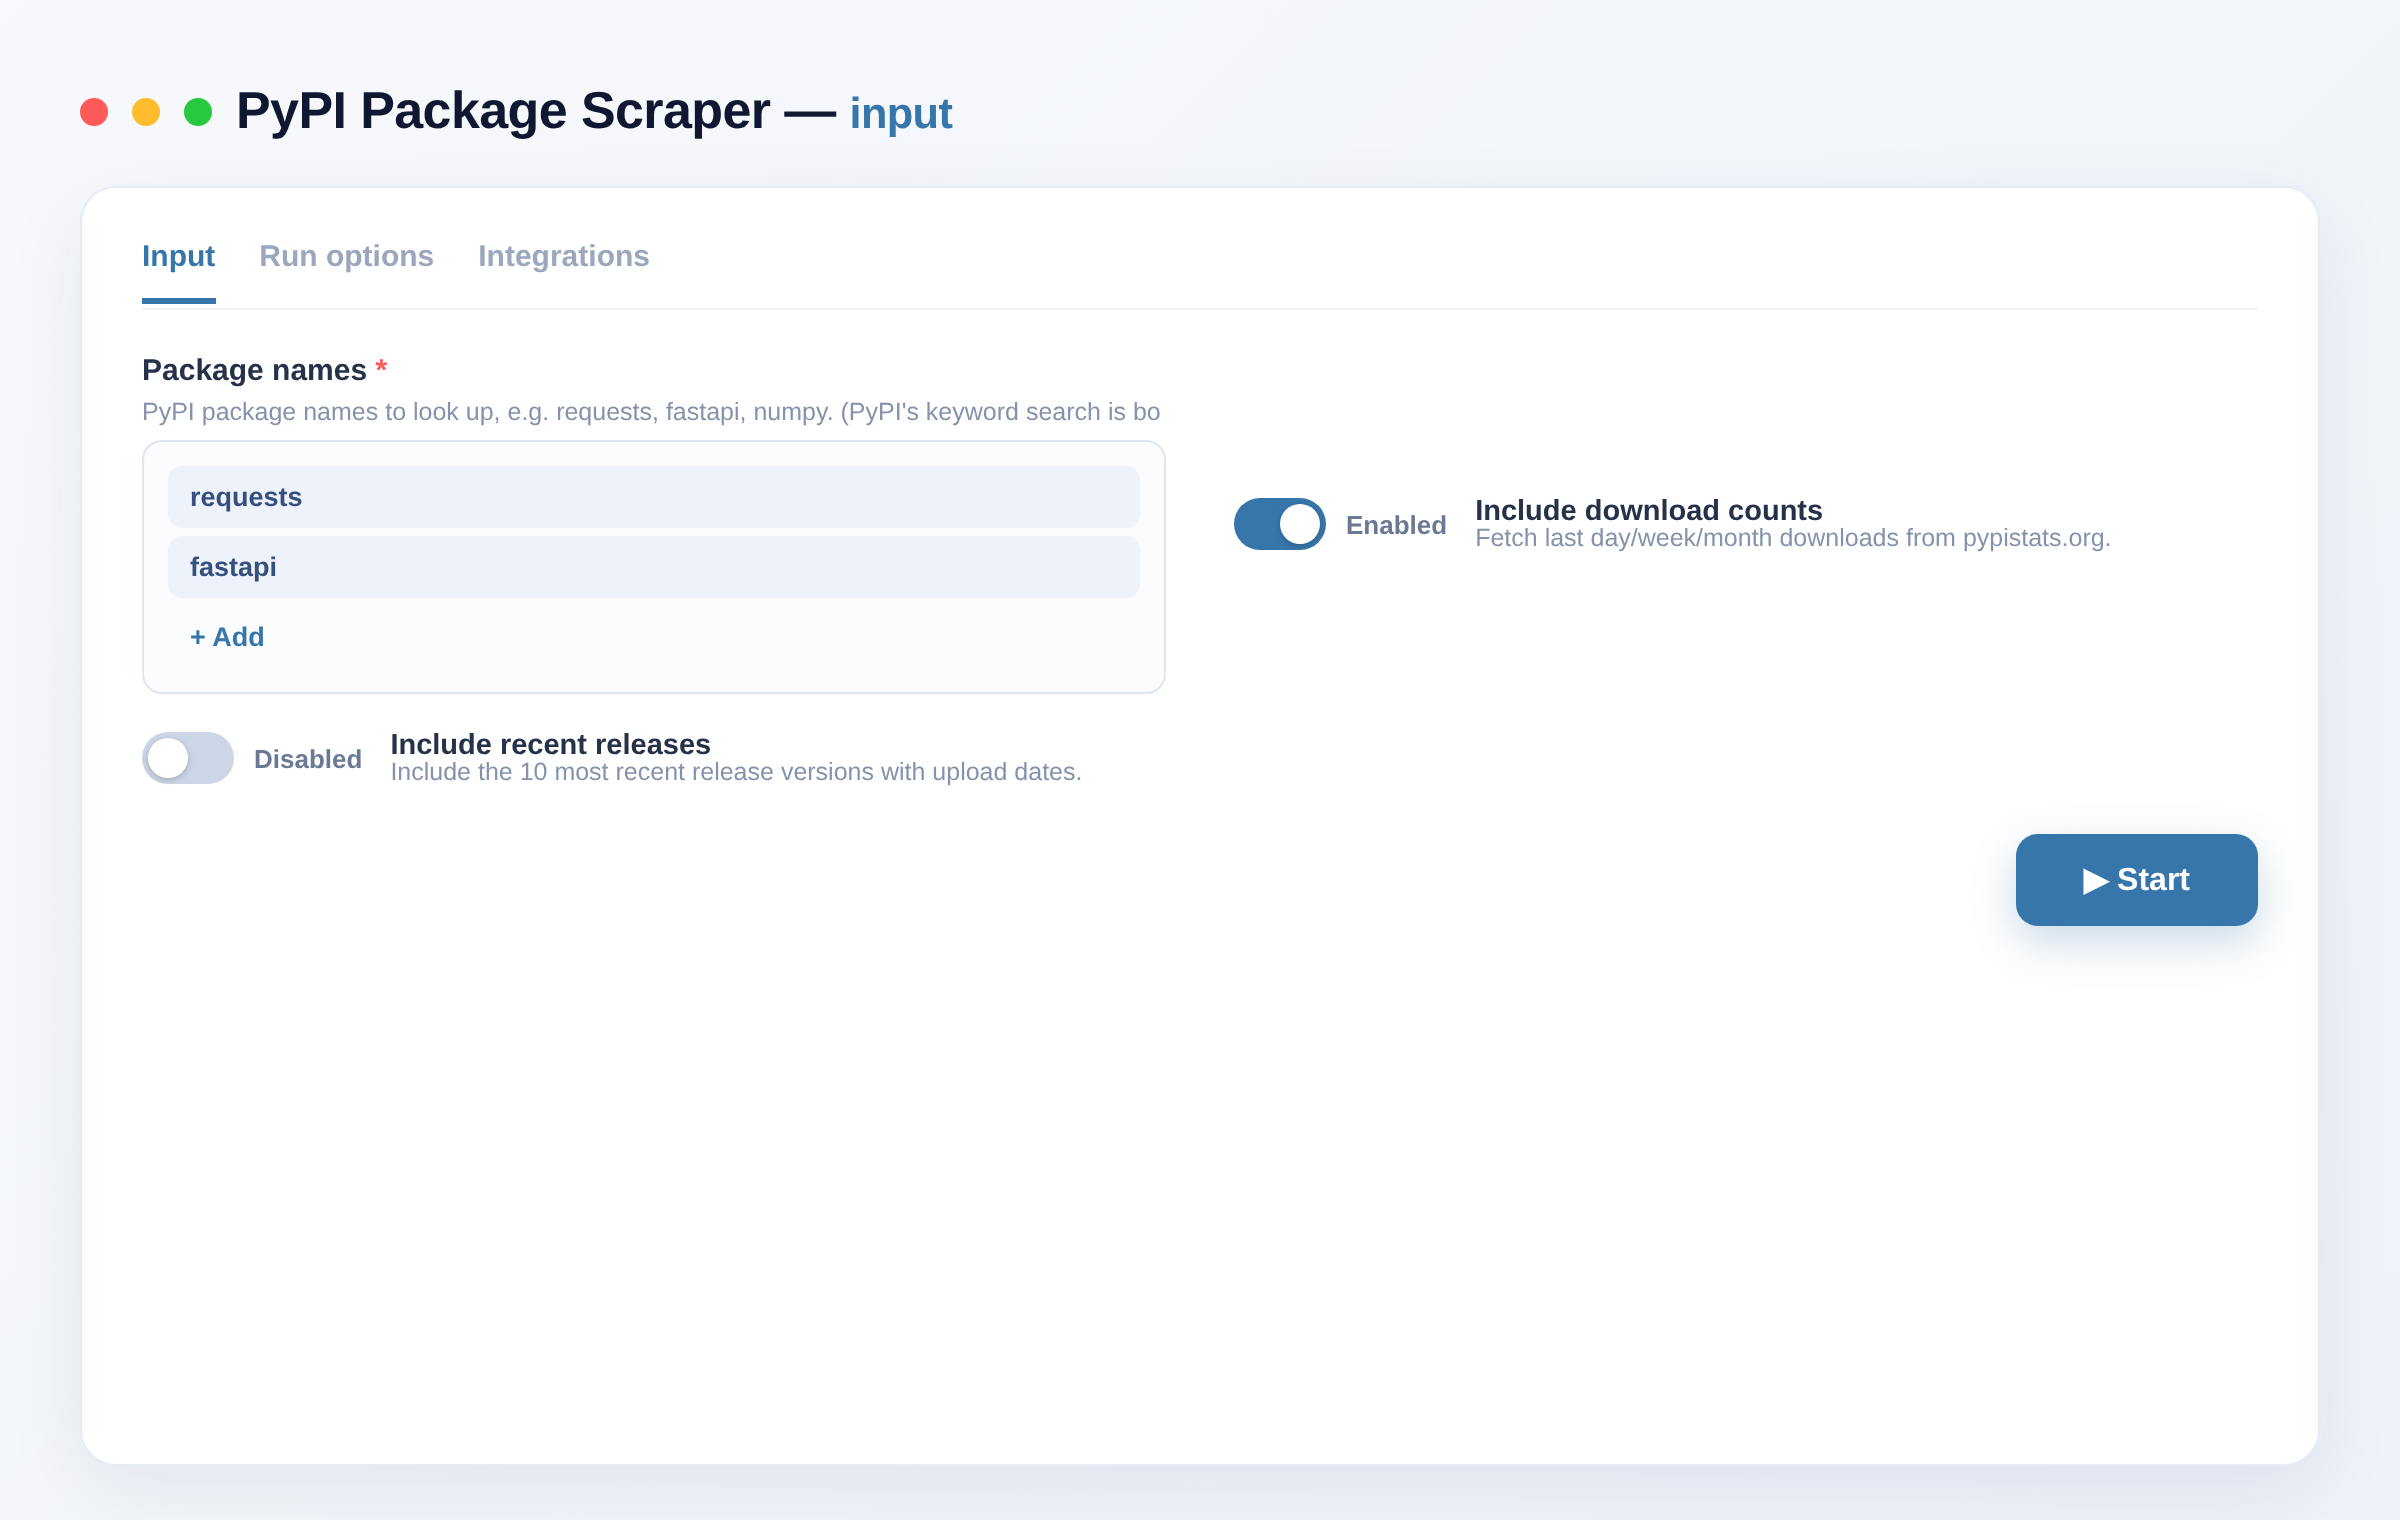
packages |
PyPI package names to look up (exact names from your requirements.txt / poetry.lock). |
includeDownloads |
Fetch last day/week/month downloads from pypistats.org. |
includeReleases |
Include recentReleases: the 10 most recent versions with upload dates. |
Use cases
- Audit licenses and Python-version requirements across every dependency in a project.
- Flag
yankedreleases and outdated packages before an upgrade. - Map a project's full transitive dependency names for security review.
- Track download momentum to compare competing Python libraries.
Pricing
Pay-per-event: you're billed a small amount per run and per item scraped — you only pay for what you get. See the Pricing tab for current rates.
FAQ
Do I need a PyPI account or API key? No. The actor reads from the official PyPI JSON API and pypistats.org, so no account, login or API key is required.
Can I search PyPI by keyword?
Not by keyword. PyPI's keyword search is bot-protected, so this actor works from exact package names — paste them straight from your requirements.txt or poetry.lock into the packages field.
Is scraping PyPI allowed? This actor only reads publicly available package data through PyPI's own public JSON API and the pypistats.org download API. Review the PSF's terms before large-scale or commercial reuse.
What's the output format?
Structured JSON — one record per package with fields such as version, license, requiresPython, dependencies, yanked, release history and download counts. Export as JSON, CSV, Excel or via the API.
Can I get download counts and release history?
Yes. Set includeDownloads for last day/week/month figures from pypistats.org, and includeReleases to attach recentReleases — the 10 most recent versions with upload dates.
Can I connect this to other apps? The PyPI Package Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Auditing Python dependencies alongside other stacks? Combine this with our other developer-data scrapers:
- npm Package Scraper — search and look up npm packages with metadata, dependencies and downloads.
- crates.io Scraper — Rust crate metadata, versions, licenses and download trends.
- GitHub Scraper — repositories and user profiles with stars, topics, licenses and leads.
- Stack Overflow & Stack Exchange Scraper — questions by tag or search across Stack Exchange sites.
Notes
This actor uses the public PyPI JSON API and pypistats.org and reads only publicly available package data. PyPI's keyword search is bot-protected, so this actor works from exact package names. It is an independent tool and is not affiliated with, endorsed by, or sponsored by the Python Software Foundation; "PyPI" and "Python" are trademarks of the PSF.
Input
| Field | Type | Description |
|---|---|---|
packages requiredPackage names | array | PyPI package names to look up, e.g. requests, fastapi, numpy. (PyPI's keyword search is bot-protected, so this actor works from exact names — paste them from a requirements.txt / poetry.lock.) |
includeDownloadsInclude download counts | boolean | Fetch last day/week/month downloads from pypistats.org. Default: true |
includeReleasesInclude recent releases | boolean | Include the 10 most recent release versions with upload dates. Default: false |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~pypi-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "packages": [
    "requests",
    "fastapi",
    "numpy"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/pypi-scraper").call(run_input={
"packages": [
"requests",
"fastapi",
"numpy"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/pypi-scraper').call({
"packages": [
"requests",
"fastapi",
"numpy"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Package scraped One PyPI package with version, license, Python requirement, dependencies, releases and download counts | $0.0037 | $0.0019 |
| API request One PyPI metadata or pypistats download fetch | $0.0003 | $0.0003 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Carousell Scraper
Scrape Carousell search listings: title, price, condition, location, seller, photo and URL. Requires your own Carousell app token.
242 runs · 2 users · $0.003 / listing scraped
Google Flights Scraper
Scrape flight options from Google Flights by route and date: airline, flight number, departure and arrival times, duration, stops, layovers and price. One-way or round-trip, any cabin and currency. For travel and price monitoring.
216 runs · 4 users · $0.004 / flight scraped
Pinterest Scraper
Search Pinterest and scrape pins (title, description, destination link, image, pinner, board, saves), boards and users. Fast. For visual research, e-commerce, trend and marketing analysis.
151 runs · 2 users · $0.0034 / item scraped
Google Trends Scraper
Scrape Google Trends for any keyword: interest over time, related and rising queries, and interest by region. Per country and timeframe. For SEO, market and trend research. No setup.
139 runs · 6 users · $0.001 / keyword scraped
AliExpress Product Search Scraper
Search AliExpress by keyword and export one clean row per product — title, sale price, original price, image and product URL. Export to JSON, CSV or Excel.
135 runs · 3 users · $0.003 / product scraped
Google Maps Scraper
Search Google Maps and scrape places: name, category, full address, city, coordinates, rating, phone, website, Place ID and map link. Fast browser-free via Google's internal endpoint, no setup. For local lead generation and market research.
130 runs · 2 users · $0.005 / place scrapedSend the site and the fields. We build it and you get it first.