Scrapers / Developer & File Tools
Bulk URL Status Checker
hipersoft/bulk-url-checker
Check thousands of URLs over plain HTTP: status codes, broken links (404/410/5xx), full redirect chains, response time, content type, page title and SSL certificate expiry.
Total users
13Monthly users
2Total runs
154Per url checked
$0.002Last rebuilt
Oct 26, 2026Overview
Audit thousands of URLs in one run. Feed the Actor any list of links and it reports each one's HTTP status, whether it's broken, the full redirect chain, response time, content type, page title, and SSL certificate expiry — over plain HTTP, no browser and no login.
Great for broken-link audits, redirect/migration QA, uptime spot-checks, sitemap validation, and SSL-expiry monitoring. Export results to JSON, CSV or Excel.
What you get per URL
| Field | Notes |
|---|---|
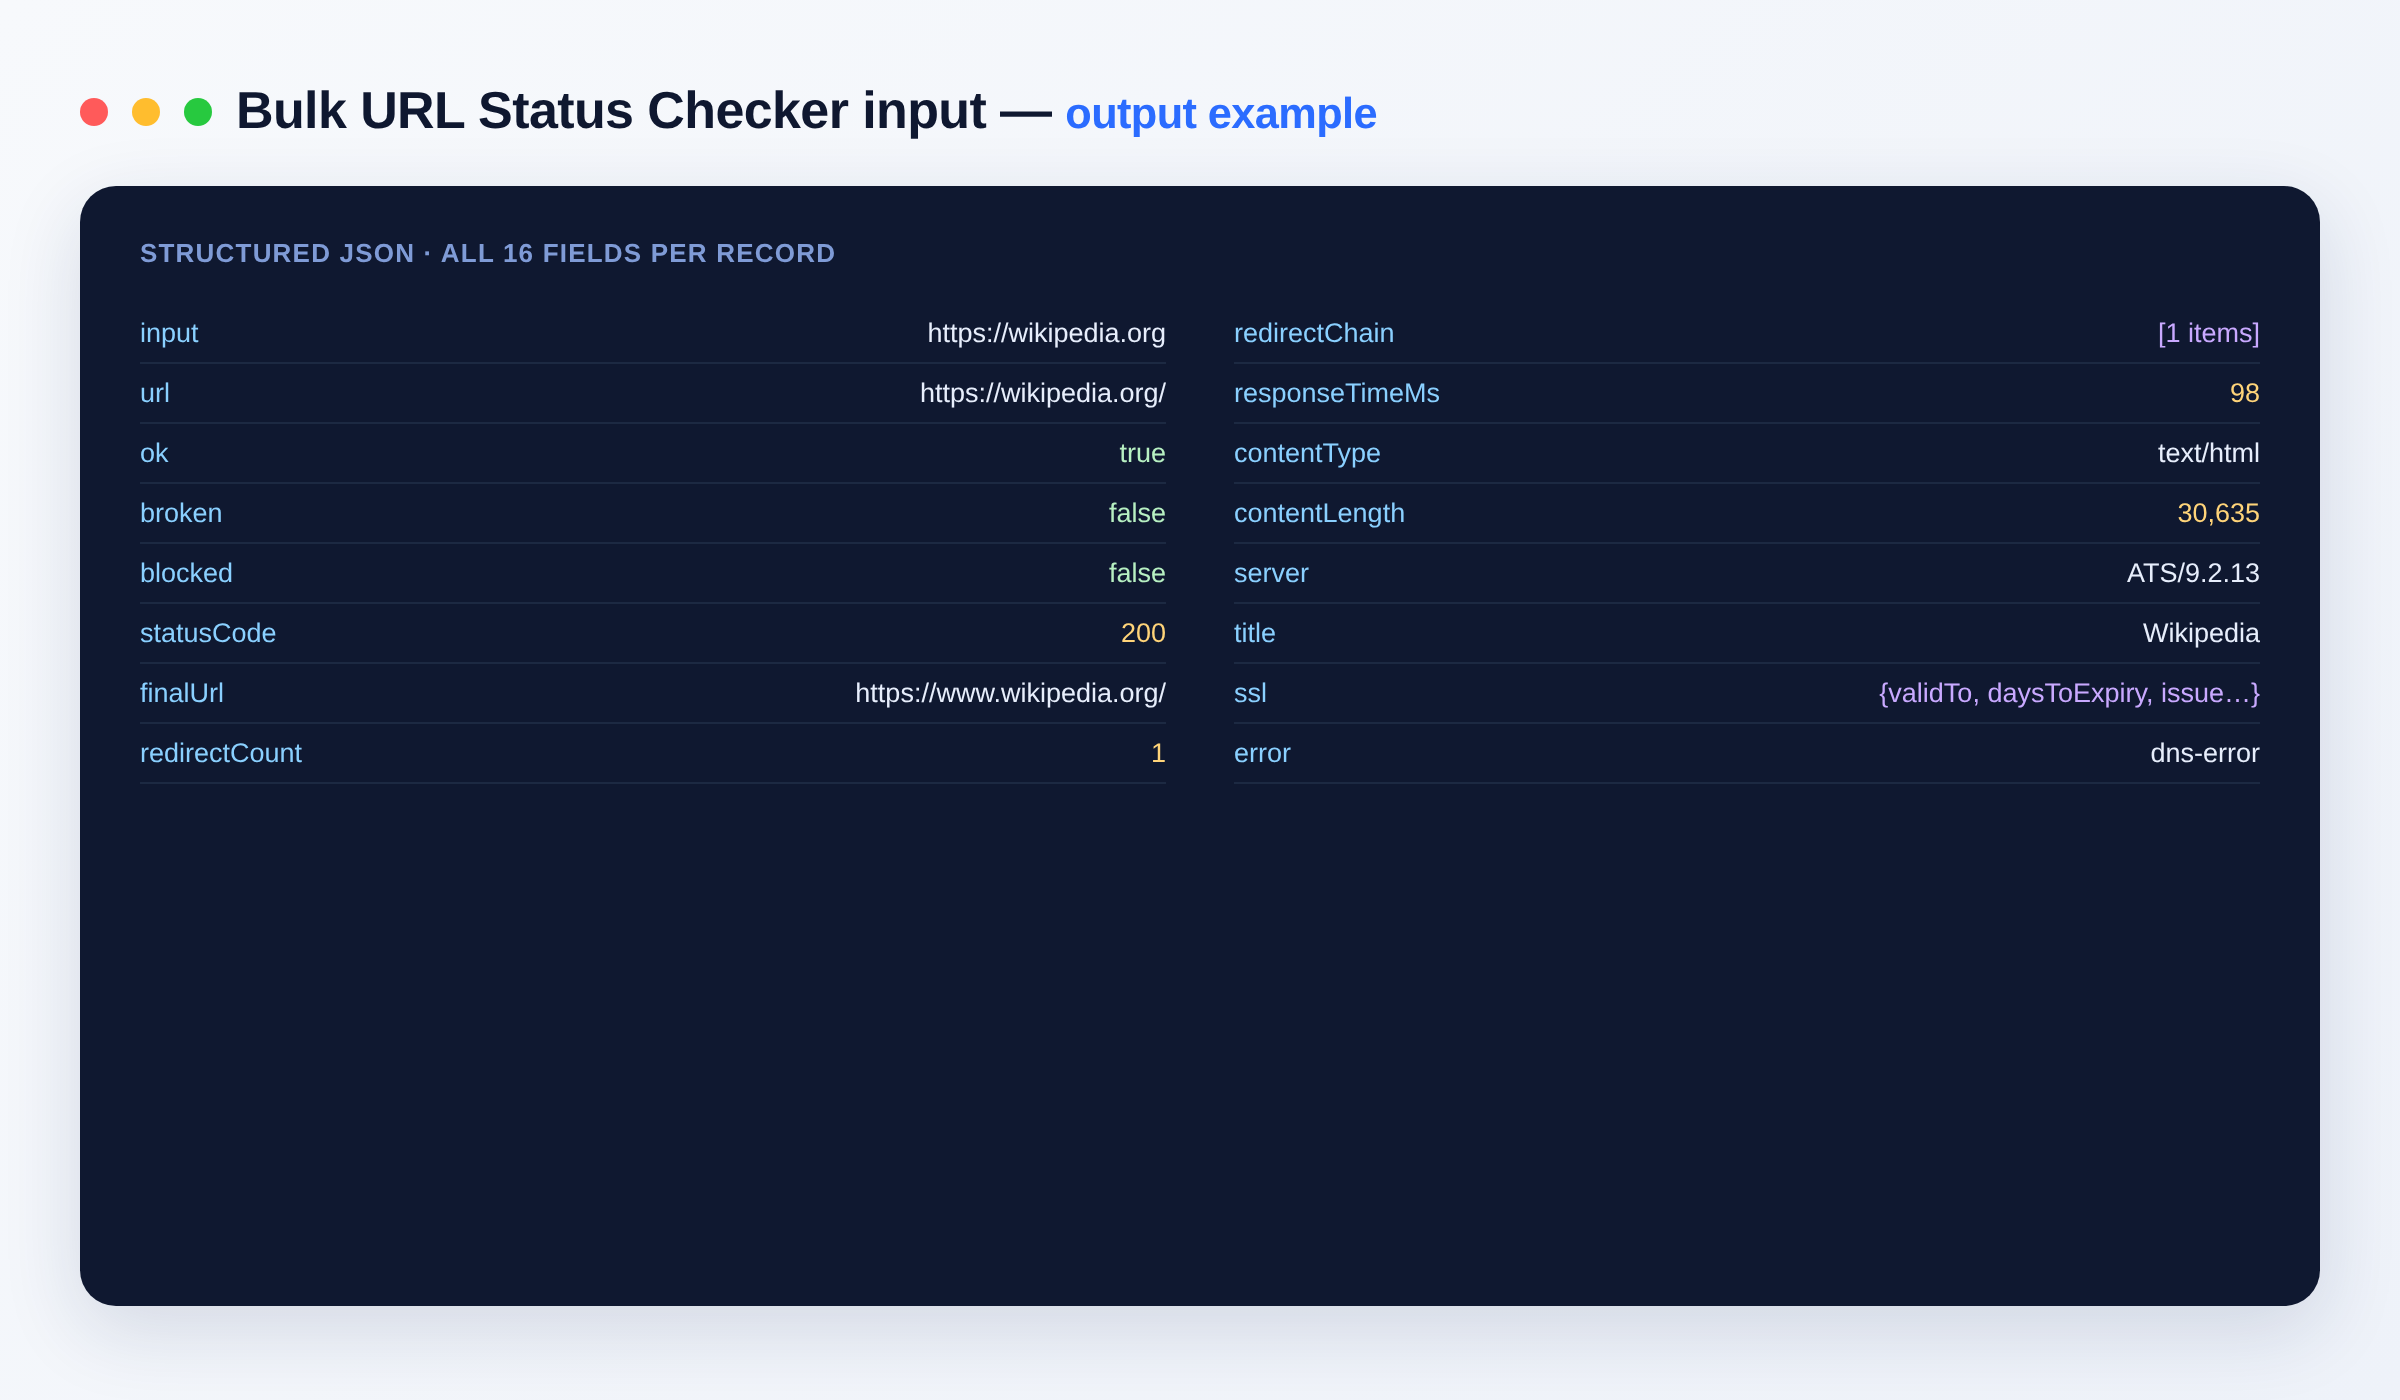
statusCode |
Final HTTP status (200, 301, 404, 410, 500, …). |
ok / broken / blocked |
ok = 2xx/3xx; broken = genuinely dead (404/410/5xx); blocked = access-restricted (401/403/429, usually bot-protection — try a proxy). Keeps blocks from being mistaken for dead links. |
redirectChain |
Every hop: {url, status, location} — see exactly where a link lands. |
redirectCount |
Number of redirects followed. |
finalUrl |
Where the URL ended up after all redirects. |
responseTimeMs |
End-to-end time for the whole chain. |
contentType, contentLength, server |
From the final response headers. |
title |
<title> of successful HTML pages (toggle off for pure speed). |
ssl |
For https: { issuer, validTo, daysToExpiry, authorized } — catch expiring certs. |
error |
Classified failure: dns-error, timeout, connection-refused, ssl-error, too-many-redirects, … |
Why it's more than a status checker
Besides the status code it traces the complete redirect path (not just the final landing), measures latency, grabs the page title so a report is human-readable, and checks the TLS certificate expiry — so one run doubles as a broken-link audit and an SSL-expiry watch.
Input
{
  "urls": ["https://apify.com", "https://apify.com/this-page-does-not-exist"],
  "checkSsl": true,
  "fetchTitle": true,
  "maxConcurrency": 20
}
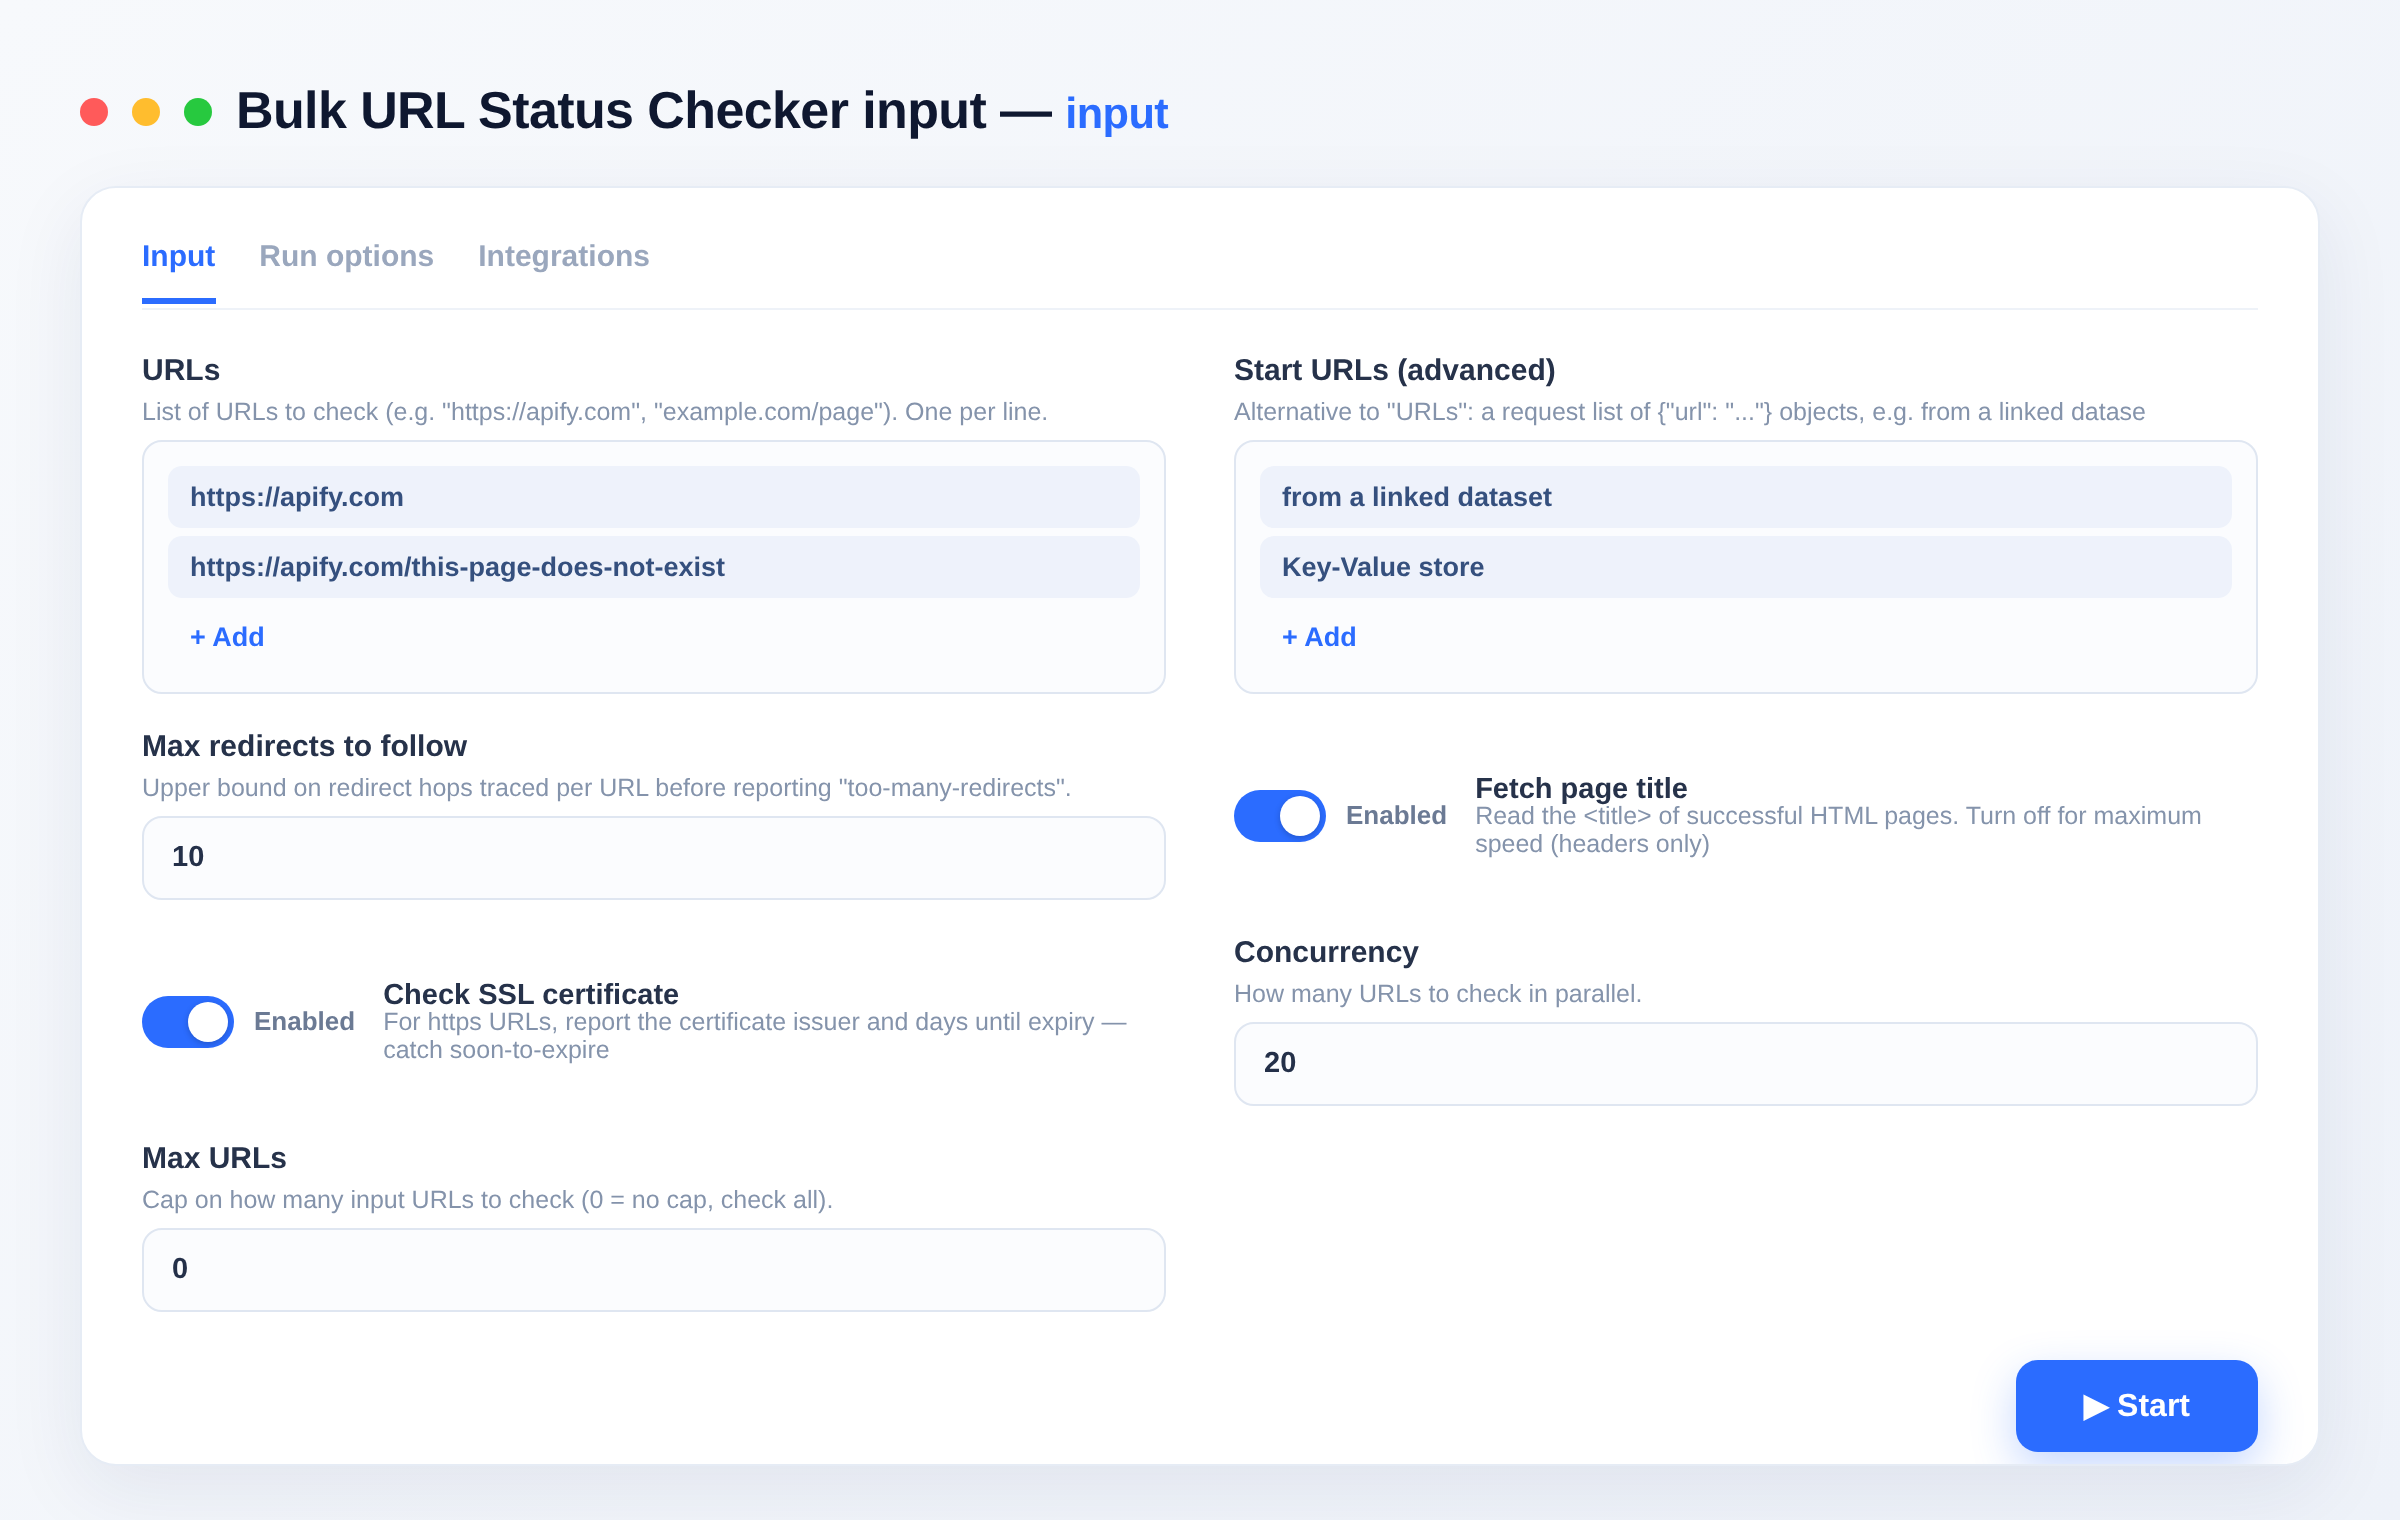
- urls — links to check, one per line. (Or use startUrls for a request list.)
- maxRedirects — hops to trace before giving up (default 10).
- fetchTitle — read
<title>of HTML pages (default on; turn off for max speed). - checkSsl — report certificate expiry for https URLs (default on).
- maxConcurrency — URLs checked in parallel (default 20).
- maxItems — cap total URLs (0 = all).
- proxyConfiguration — optional; enable for reliable access at scale.
Output (one row per URL)
{
  "input": "https://apify.com/this-page-does-not-exist",
  "url": "https://apify.com/this-page-does-not-exist",
  "statusCode": 404,
  "ok": false,
  "broken": true,
  "redirectCount": 0,
  "finalUrl": "https://apify.com/this-page-does-not-exist",
  "responseTimeMs": 220,
  "contentType": "text/html; charset=utf-8",
  "title": "Page not found",
  "ssl": { "issuer": "Google Trust Services", "daysToExpiry": 61, "authorized": true },
  "error": null
}
Output schema
| Field | Type | Description |
|---|---|---|
input |
string (URL) | The original URL you supplied. |
url |
string (URL) | The URL that was checked. |
ok |
boolean | True when the URL responded with a 2xx/3xx status. |
broken |
boolean | True when the URL is genuinely dead (404/410/5xx). |
blocked |
boolean | True when access was restricted (401/403/429). |
statusCode |
string | Final HTTP status code after redirects. |
finalUrl |
string (URL) | The URL the request landed on after all redirects. |
redirectCount |
integer | Number of redirects followed. |
redirectChain |
array | Each redirect hop with its URL, status and location. |
responseTimeMs |
integer | End-to-end response time in milliseconds. |
contentType |
string | Content-Type header of the final response. |
contentLength |
string | Content-Length header of the final response. |
server |
string | Server header of the final response. |
title |
string | <title> text of successful HTML pages. |
ssl |
string | SSL certificate details: issuer, expiry date, days to expiry and whether it is trusted. |
error |
string | Classified failure reason, or null when the check succeeded. |
Pricing
Pay per URL checked. No monthly fee — you only pay for what you run.
FAQ
Do I need an account or API key? No. The Actor works over plain HTTP with no login or API key — just supply your list of URLs.
How many URLs can I check per run?
Thousands in a single run. maxItems caps the total (0 = all) and maxConcurrency controls how many URLs are checked in parallel (default 20).
Is bulk URL checking legal? The Actor only reads the HTTP response of the URLs you supply. You are responsible for having the right to audit those targets and for respecting each site's terms and rate limits.
What's the output format? A JSON dataset with one row per URL (status, broken/blocked flags, redirect chain, response time, title, SSL details). Export as JSON, CSV, or Excel from the Apify Console or API.
Can I filter or limit results?
Yes. Use maxItems, maxConcurrency, and maxRedirects, and toggle checkSsl and fetchTitle on or off to trade detail for speed.
Can I connect this Actor to other apps? The Bulk URL Status Checker can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Combine this with other web-diagnostics and archival tools:
- Domain Inspector — WHOIS/RDAP, DNS, and SSL details for any domain.
- Wayback Machine Scraper — list archived snapshots of a URL or domain.
- Bulk Image Downloader — fetch and store images at scale from a URL list.
- Website Content Crawler — crawl a site into clean text for analysis or RAG.
Notes
Checks only the HTTP response of URLs you supply. You are responsible for having the right to audit the target URLs.
Input
| Field | Type | Description |
|---|---|---|
urlsURLs | array | List of URLs to check (e.g. "https://apify.com", "example.com/page"). One per line. |
startUrlsStart URLs (advanced) | array | Alternative to "URLs": a request list of {"url": "..."} objects, e.g. from a linked dataset or Key-Value store. |
maxRedirectsMax redirects to follow | integer | Upper bound on redirect hops traced per URL before reporting "too-many-redirects". Default: 10 |
fetchTitleFetch page title | boolean | Read the of successful HTML pages. Turn off for maximum speed (headers only). Default: true |
checkSslCheck SSL certificate | boolean | For https URLs, report the certificate issuer and days until expiry — catch soon-to-expire certs. Default: true |
maxConcurrencyConcurrency | integer | How many URLs to check in parallel. Default: 20 |
maxItemsMax URLs | integer | Cap on how many input URLs to check (0 = no cap, check all). Default: 0 |
proxyConfigurationProxy configuration | object | Proxy configuration. Leave the default — it is tuned for reliable results. Default: {"useApifyProxy": false} |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~bulk-url-checker/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "urls": [
    "https://apify.com",
    "https://apify.com/this-page-does-not-exist"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/bulk-url-checker").call(run_input={
"urls": [
"https://apify.com",
"https://apify.com/this-page-does-not-exist"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/bulk-url-checker').call({
"urls": [
"https://apify.com",
"https://apify.com/this-page-does-not-exist"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| URL checked One URL checked — HTTP status, redirect chain, latency, content type and SSL certificate | $0.002 | $0.001 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Bulk Image Downloader
Download thousands of images from a list of URLs and store each in the key-value store with a public link. Returns content type, size, dimensions and SHA-256 per image. Bulk-ready. Great for datasets, backups and media pipelines.
8,102 runs · 103 users · $0.056 / url processed
Text to Speech
Convert any text to natural-sounding speech as an MP3 download. 300+ premium neural voices across 70+ languages, adjustable rate, pitch and volume. Great for voiceovers, videos, accessibility and audio content. No setup.
278 runs · 22 users · $0.01 / audio generated
Google Maps Email Extractor
Search Google Maps for businesses, then crawl each business website to extract emails, social profiles and extra phone numbers. Turns any Maps search into a ready lead list. No setup.
159 runs · 8 users · $0.006 / business lead scraped
Website Screenshot
Capture full-page or viewport screenshots of any URL as PNG or JPEG, at any device size. For monitoring, previews, thumbnails and automation workflows.
156 runs · 3 users · $0.004 / screenshot captured
Google Search Scraper
Scrape Google Search results (organic listings) for any query: title, URL, displayed URL, snippet and position. Multi-query, per-country/language, pagination. Uses Google SERP proxy — reliable, no captcha, no setup.
121 runs · 8 users · $0.001 / result scraped
crates.io Scraper
Search crates.io or look up exact Rust crates and get description, downloads, versions, license, keywords, categories, repository and documentation links.
118 runs · 1 users · $0.004 / crate scrapedSend the site and the fields. We build it and you get it first.