Wayback Machine Scraper
hipersoft/wayback-machine-scraper
List every Internet Archive (Wayback Machine) snapshot of a URL or whole domain: timestamp, snapshot URL, status code, MIME type and content digest. Filter by date, status and dedupe. For SEO, OSINT and historical research. No setup.
Total users
15Monthly users
3Total runs
135Per snapshot scraped
$0.002Last rebuilt
Oct 28, 2026Overview
List every Internet Archive (Wayback Machine) snapshot of a URL or an entire domain as clean, structured JSON. Give it a URL or hostname and this Actor returns each capture's timestamp, direct snapshot URL, HTTP status code, MIME type, content digest and byte length — filterable by date and status, with optional de-duplication. It reads the Archive's public CDX index, so there's no account and no API key. Built for SEO audits, OSINT and historical research where you need the full capture history, fast.
Features
- 🗂️ Full capture history — every archived snapshot of a URL, or a whole domain, from the Wayback CDX index.
- 🎯 Flexible match types —
exact,prefix,hostordomain(all subdomains) to scope exactly what you list. - 📅 Date filtering — bound results with
fromDate/toDate(YYYY or YYYYMMDD) to focus on a period. - ✅ Status filter — set
onlyStatus200to exclude redirects and errors and keep only successful captures. - 🧹 De-duplication modes —
collapseby unique URL, one-per-day, or unique content (digest), plus automatic removal of exact duplicate captures. - 🔗 Ready-to-open links — each record includes a
snapshotUrlthat opens the archived page directly. - 📈 Scales to domains — cap output with
maxSnapshotsPerUrl(up to 100,000 per input).
What you get
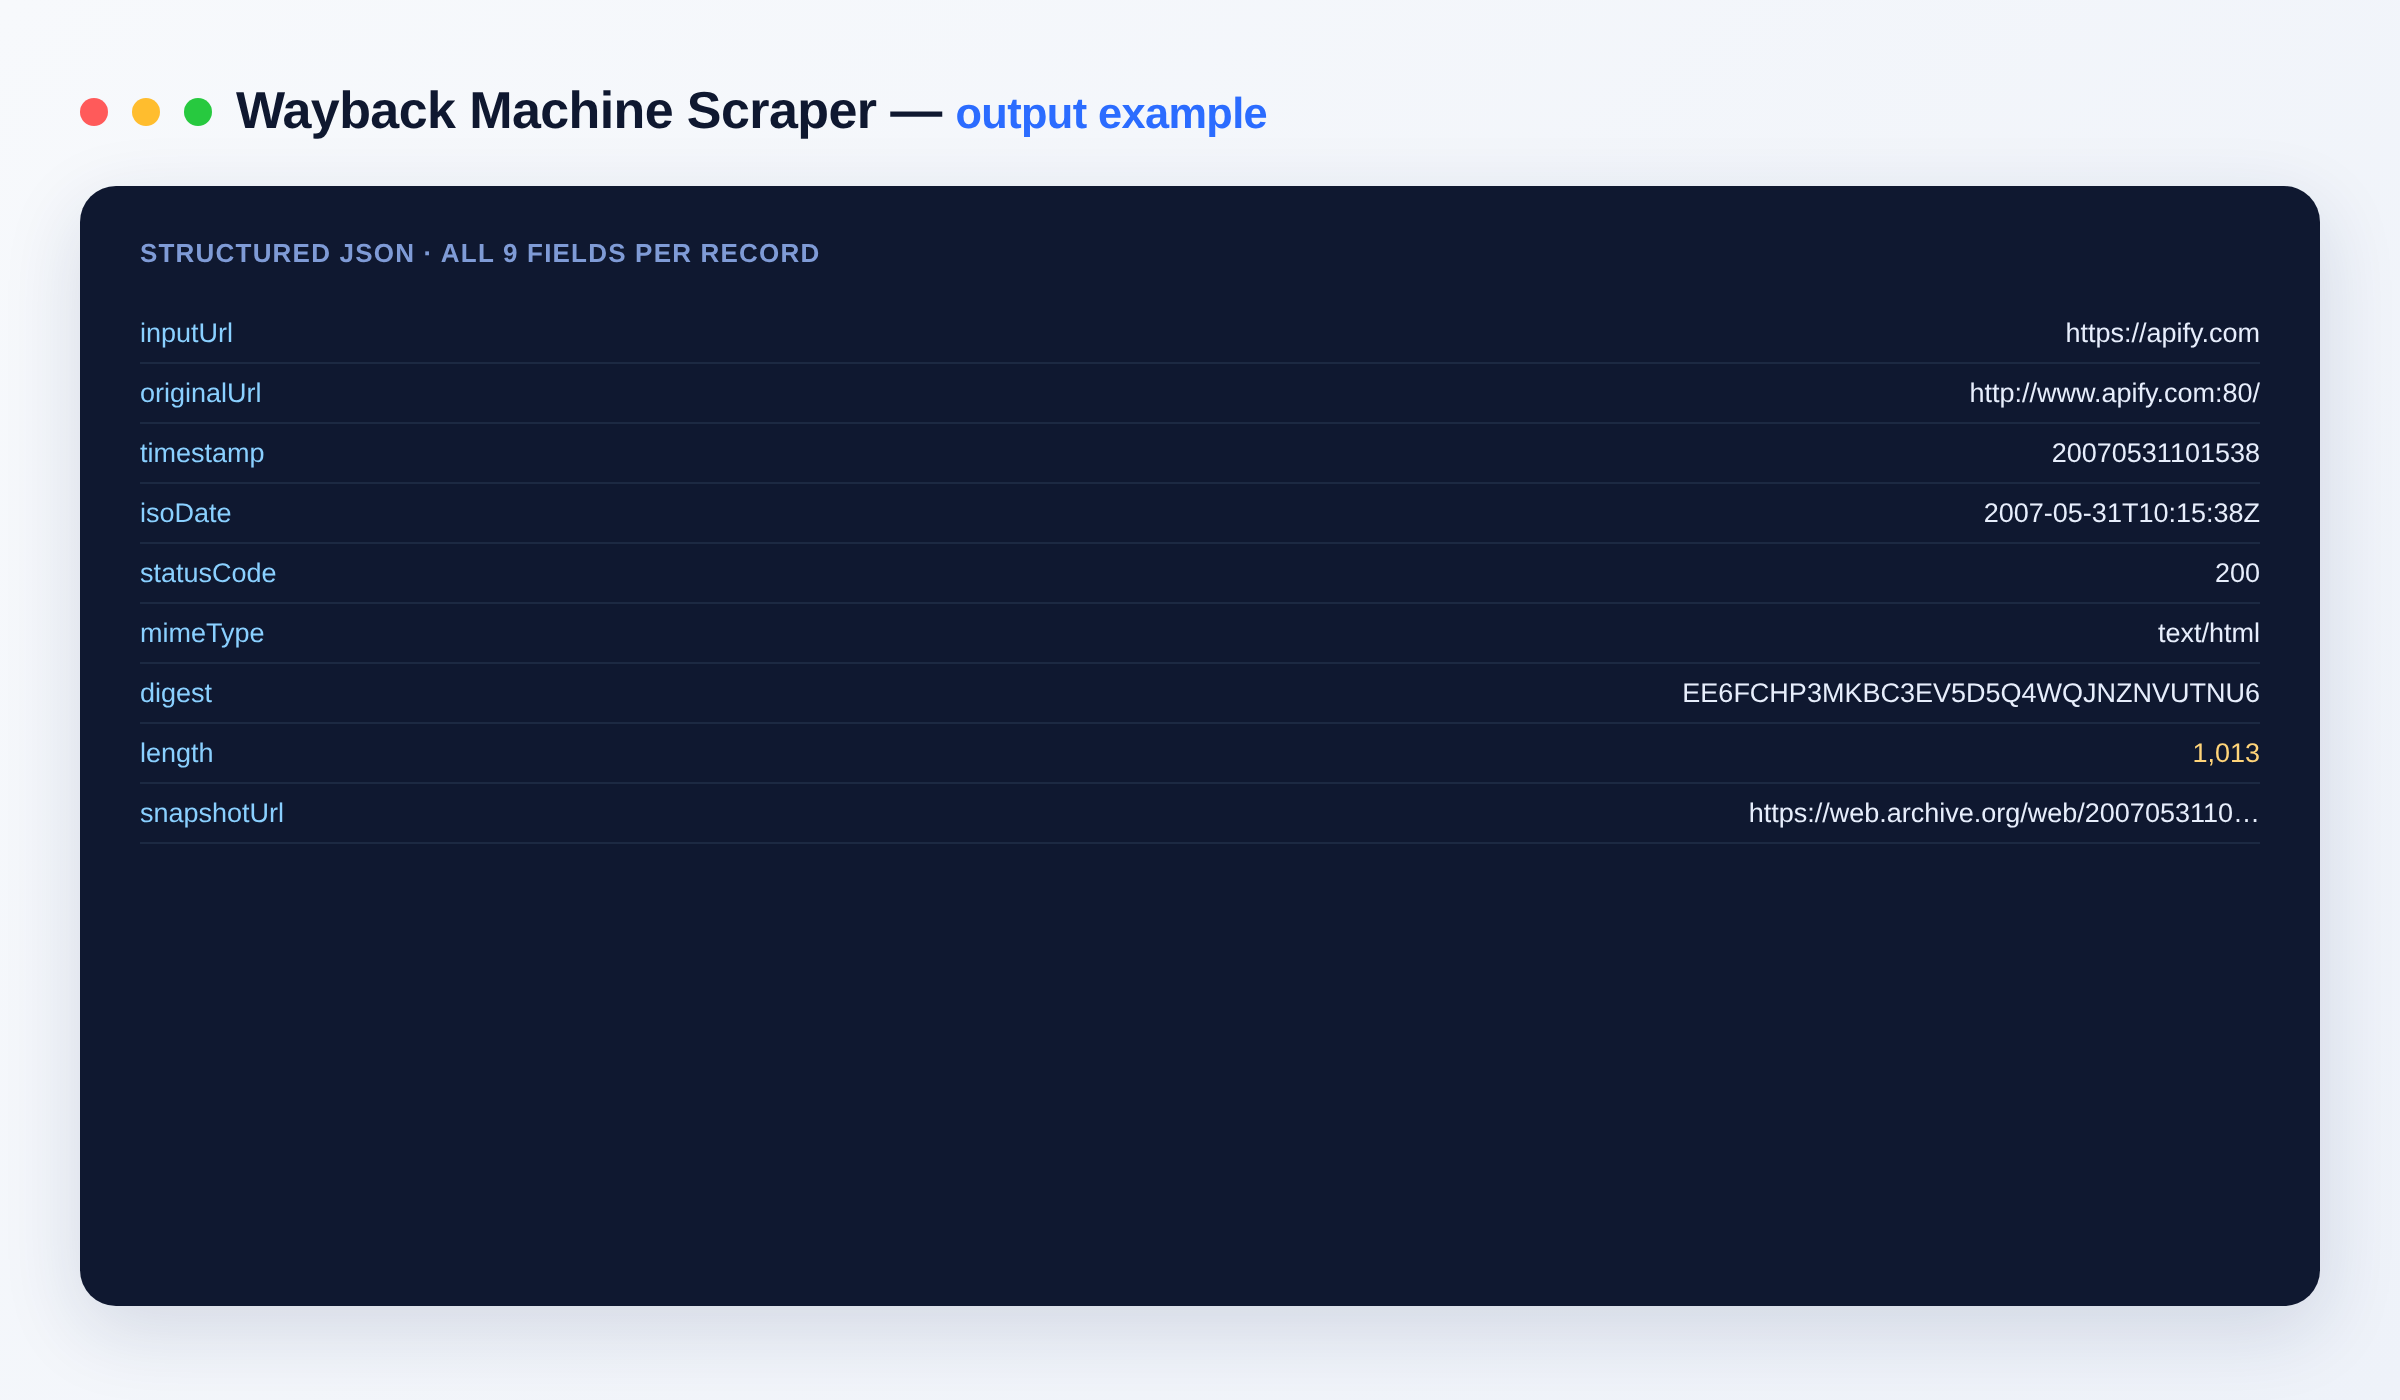
One record per snapshot, for example:
{
  "inputUrl": "apify.com",
  "originalUrl": "https://apify.com/",
  "timestamp": "20230115094512",
  "isoDate": "2023-01-15T09:45:12Z",
  "statusCode": "200",
  "mimeType": "text/html",
  "digest": "GKQ3XY7ABC5D6EF7GH8IJ9KLMN0OPQRS",
  "length": 48213,
  "snapshotUrl": "https://web.archive.org/web/20230115094512/https://apify.com/"
}
Output schema
| Field | Type | Description |
|---|---|---|
inputUrl |
string (URL) | The URL or domain you supplied as input for this snapshot. |
originalUrl |
string (URL) | The original captured URL as recorded in the archive. |
timestamp |
string | Capture time in Wayback's YYYYMMDDhhmmss format. |
isoDate |
string (ISO date) | Capture time as an ISO 8601 date-time. |
statusCode |
string | HTTP status code returned when the page was archived. |
mimeType |
string | MIME/content type of the archived capture. |
digest |
string | Content digest (hash) identifying the captured content. |
length |
integer | Size of the archived capture, in bytes. |
snapshotUrl |
string (URL) | Direct link to open the archived snapshot on the Wayback Machine. |
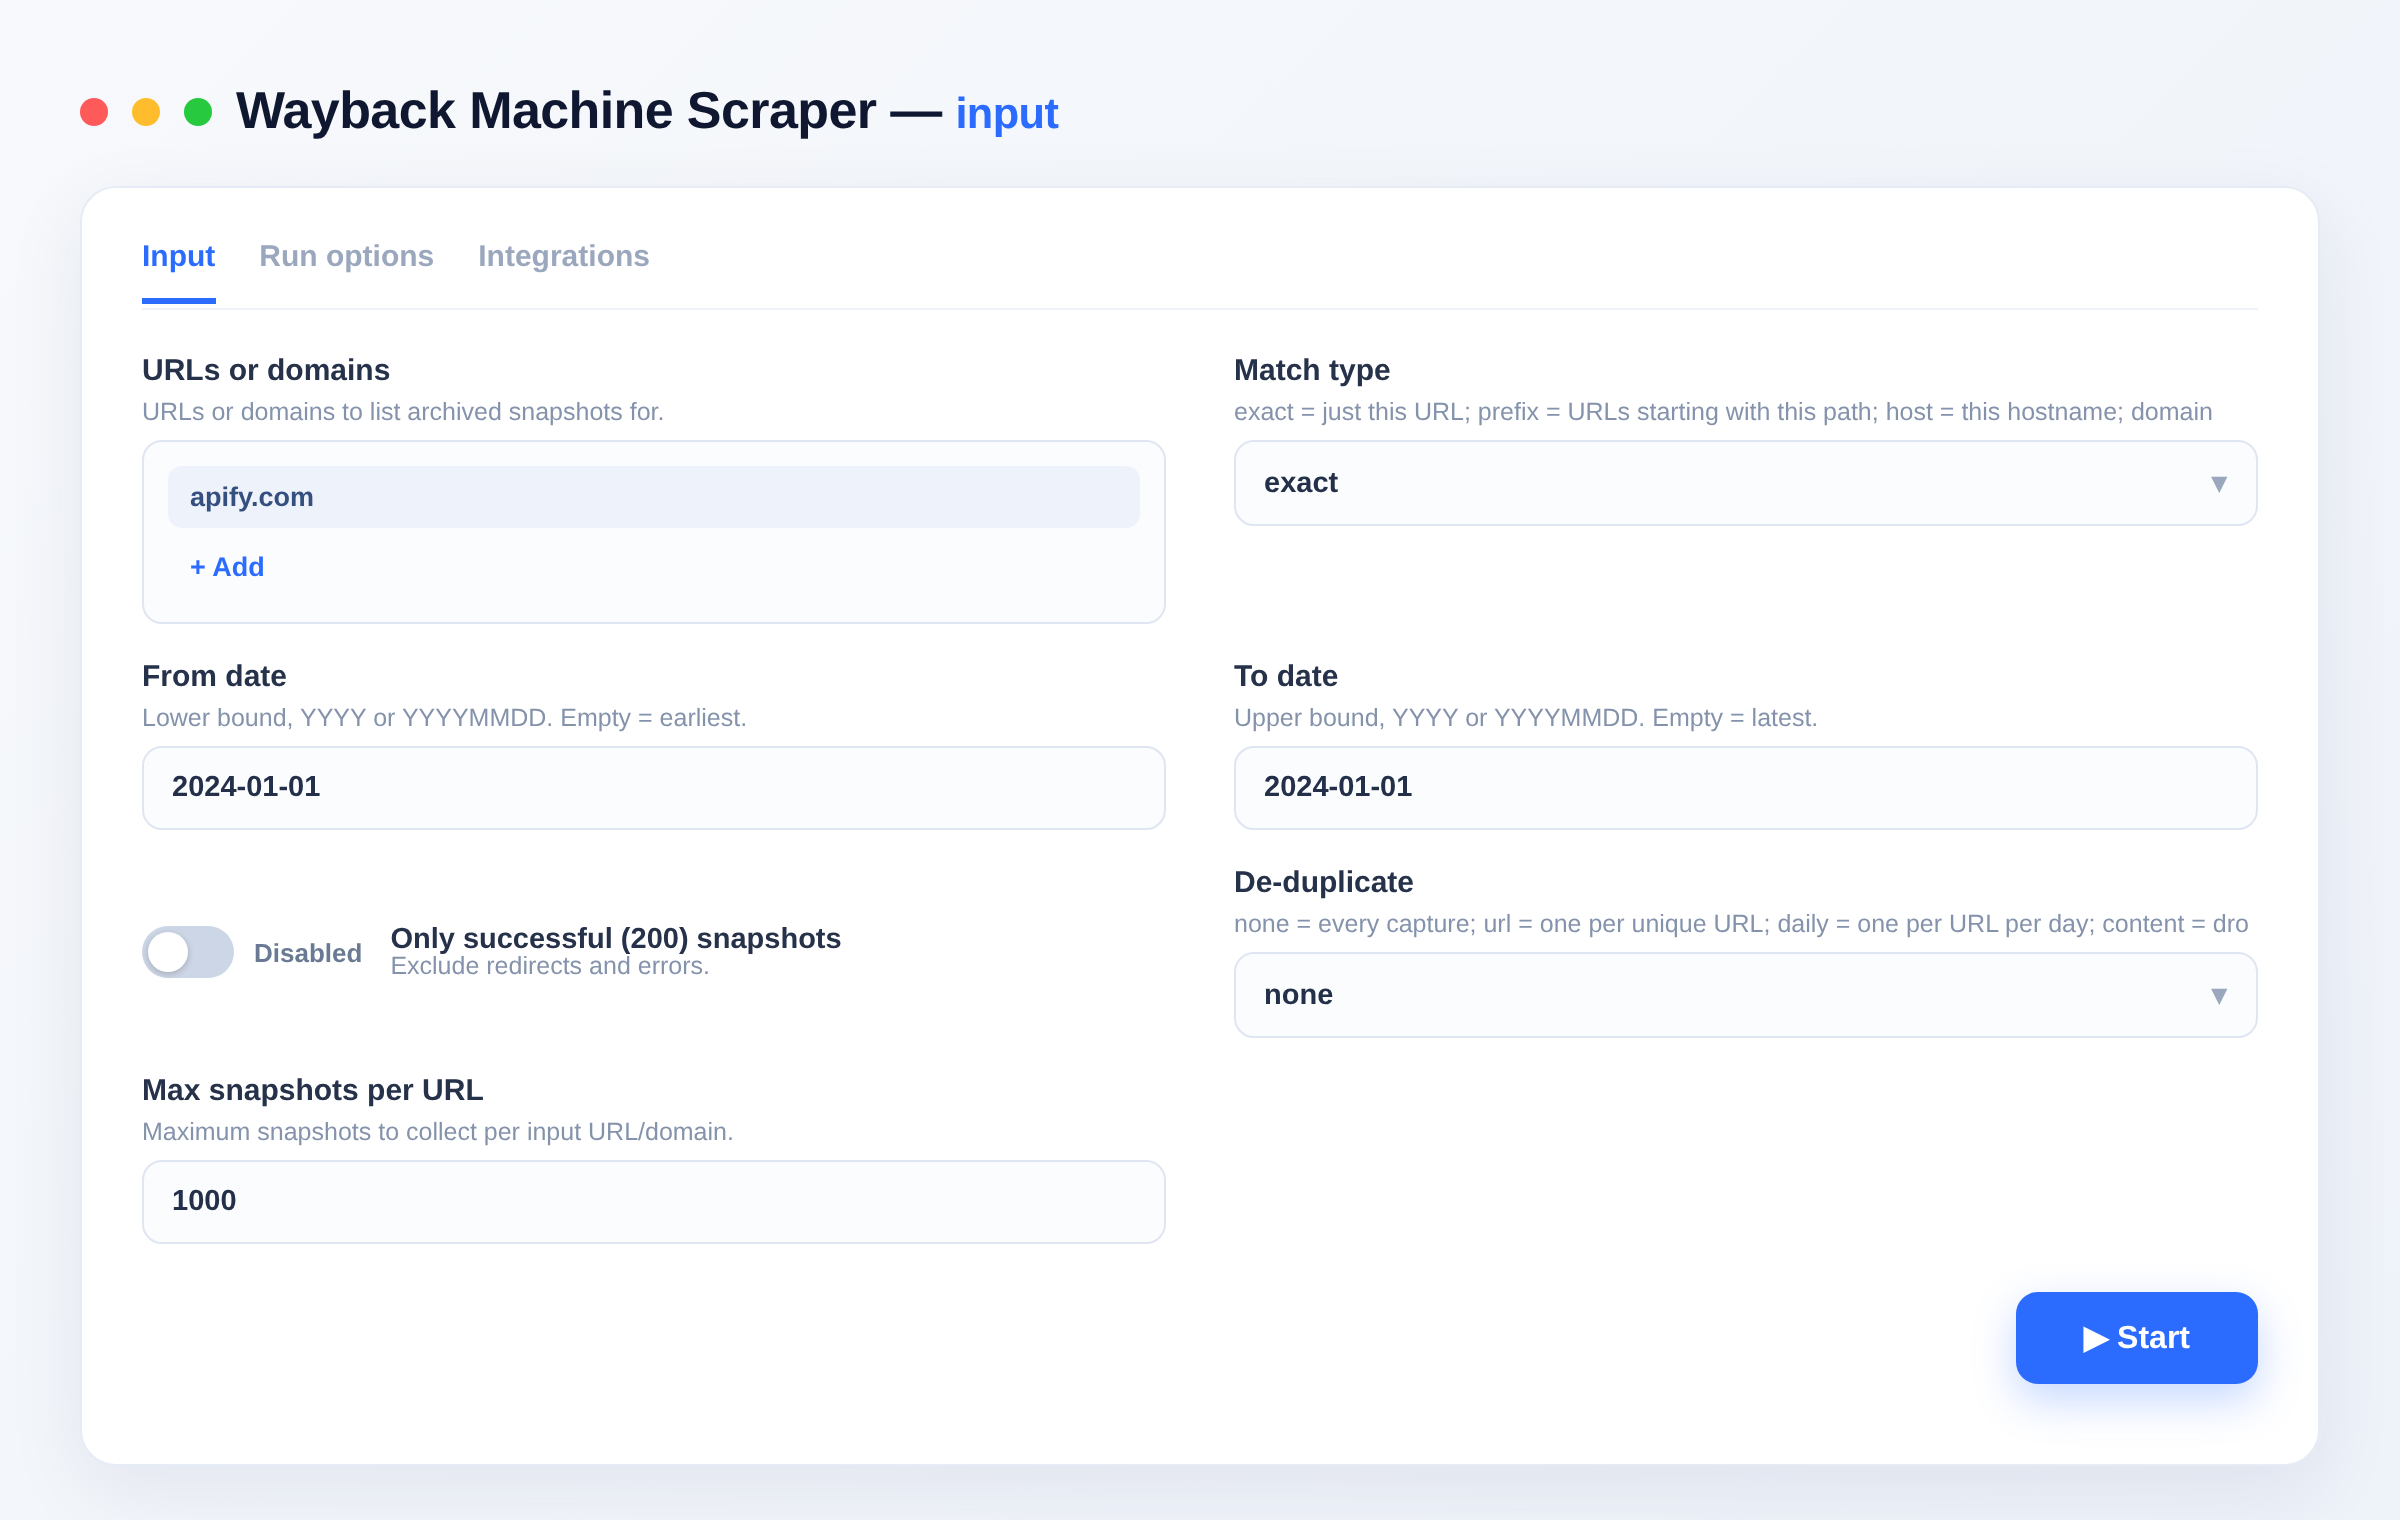
Input
{
  "urls": ["apify.com", "https://example.com/pricing"],
  "matchType": "exact",
  "fromDate": "2020",
  "toDate": "2023",
  "onlyStatus200": false,
  "collapse": "none",
  "maxSnapshotsPerUrl": 1000
}
| Field | Description |
|---|---|
urls |
URLs or domains to list archived snapshots for. One per line. |
matchType |
exact, prefix (path), host, or domain (domain + all subdomains). |
fromDate / toDate |
Date bounds, YYYY or YYYYMMDD. Empty = earliest / latest. |
onlyStatus200 |
Exclude redirects and errors, keeping only successful captures. |
collapse |
De-duplicate: none, url, daily, or content. |
maxSnapshotsPerUrl |
Maximum snapshots to collect per input URL/domain (1–100,000). |
Use cases
- Audit a site's historical page changes and URL structure for SEO.
- Recover lost content by locating the exact archived snapshot to restore.
- OSINT and due diligence: trace how a page or brand presented itself over time.
- Detect when pages appeared, changed (by content digest) or went offline.
Pricing
Pay-per-event: you're billed a small amount per run and per item scraped — you only pay for what you get. See the Pricing tab for current rates.
FAQ
Do I need an account or API key? No. The Actor reads the public CDX index of the Internet Archive Wayback Machine, so there's no account, login, or API key required.
How many snapshots can I list per run?
Up to 100,000 per input URL or domain, controlled by maxSnapshotsPerUrl. Use host or domain match types to enumerate captures across an entire site.
Is scraping the Wayback Machine legal? The Actor collects only publicly available capture metadata from the Internet Archive's CDX API. It is an independent tool, not affiliated with the Internet Archive — please respect their terms and use it responsibly.
What's the output format?
A JSON dataset with one record per snapshot (timestamp, original URL, status code, MIME type, content digest, byte length, and a ready-to-open snapshotUrl). Export as JSON, CSV, or Excel.
Can I filter or limit results?
Yes. Use matchType, fromDate/toDate, onlyStatus200, the collapse de-duplication modes (url/daily/content), and maxSnapshotsPerUrl.
Can I connect the Wayback Machine Scraper to other tools? The Wayback Machine Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Pair archival history with live web-diagnostics tools:
- Bulk URL Status Checker — check which of those historical URLs are still live today.
- Domain Inspector — WHOIS/RDAP, DNS, and SSL details for any domain.
- Website Content Crawler — crawl a live site into clean text for analysis or RAG.
- Bulk Image Downloader — fetch and store images at scale from a URL list.
Notes
This Actor reads publicly available capture metadata from the Internet Archive's Wayback Machine CDX API. It is an independent tool and is not affiliated with, endorsed by, or sponsored by the Internet Archive. It targets public data only — please respect the Internet Archive's terms and use it responsibly.
Input
| Field | Type | Description |
|---|---|---|
urlsURLs or domains | array | URLs or domains to list archived snapshots for. |
matchTypeMatch type | string · exact, prefix, host, domain | exact = just this URL; prefix = URLs starting with this path; host = this hostname; domain = the domain and all subdomains. Default: "exact" |
fromDateFrom date | string | Lower bound, YYYY or YYYYMMDD. Empty = earliest. |
toDateTo date | string | Upper bound, YYYY or YYYYMMDD. Empty = latest. |
onlyStatus200Only successful (200) snapshots | boolean | Exclude redirects and errors. Default: false |
collapseDe-duplicate | string · none, url, daily, content | none = every capture; url = one per unique URL; daily = one per URL per day; content = drop identical content. Default: "none" |
maxSnapshotsPerUrlMax snapshots per URL | integer | Maximum snapshots to collect per input URL/domain. Default: 1000 |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~wayback-machine-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "urls": [
    "apify.com"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/wayback-machine-scraper").call(run_input={
"urls": [
"apify.com"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/wayback-machine-scraper').call({
"urls": [
"apify.com"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Snapshot scraped One archived snapshot with timestamp, snapshot URL, status code and MIME type | $0.002 | $0.001 |
| CDX request One Wayback CDX query for a URL or domain | $0.001 | $0.001 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
North Data Scraper
Look up European companies on North Data: legal name, former names, register number, address, founding date, LEI, business purpose, managing directors and officers, and recent register publications. Germany, UK, France, Austria and 20+ countries. Bulk lookups.
2,467 runs · 5 users · $0.004 / company
Website Content Crawler
Extract clean, readable content from any list of websites: page title, meta description, headings, main body text, word count and link/image counts. Optional same-domain crawl. Bulk-ready. Great for LLM/RAG ingestion, content audits and research.
206 runs · 20 users · $0.0024 / page scraped
SpyFu Domain Scraper
Bulk SEO and PPC reports for any domain from SpyFu: organic keywords, monthly SEO clicks and value, Google Ads budget, paid keywords, top keywords, competitors, top countries and monthly history. Competitor research for agencies. Export CSV/JSON.
185 runs · 7 users · $0.008 / domain report
Trustpilot Reviews Scraper
Scrape Trustpilot reviews and company ratings by company domain or Trustpilot URL: star rating, title, text, reviewer name & country, verification, date, company reply, plus company TrustScore and total reviews.
146 runs · 4 users · $0.0006 / review scraped
ACRA Singapore Company Registry Scraper
Search and export Singapore's full ACRA corporate registry: UEN, entity name, status, incorporation date, address, SSIC industry codes, officers, former names and audit firms. Filter by name, status, entity type or industry. Public open data, no setup.
138 runs · 10 users · $0.01 / company scraped
Clutch.co Agency Scraper
Scrape B2B agency and service-provider profiles from Clutch.co directories: company name, rating, review count, location, min project size, hourly rate, employees, services and profile link. Great for lead generation and competitor research.
129 runs · 3 users · $0.008 / agency scrapedSend the site and the fields. We build it and you get it first.