Scrapers / Developer & File Tools
PDF Split
hipersoft/pdf-split
Split one PDF into multiple files by page ranges, every N pages, or one file per page. Break big scans, statements and reports into per-record documents in one run.
Total users
2Monthly users
1Total runs
97Per pdf part created
$0.005Last rebuilt
Oct 26, 2026Overview
Split one PDF into multiple files — by page ranges, every N pages, or one file per page. Break big scans, statements and reports into per-record documents in a single run.
What it does
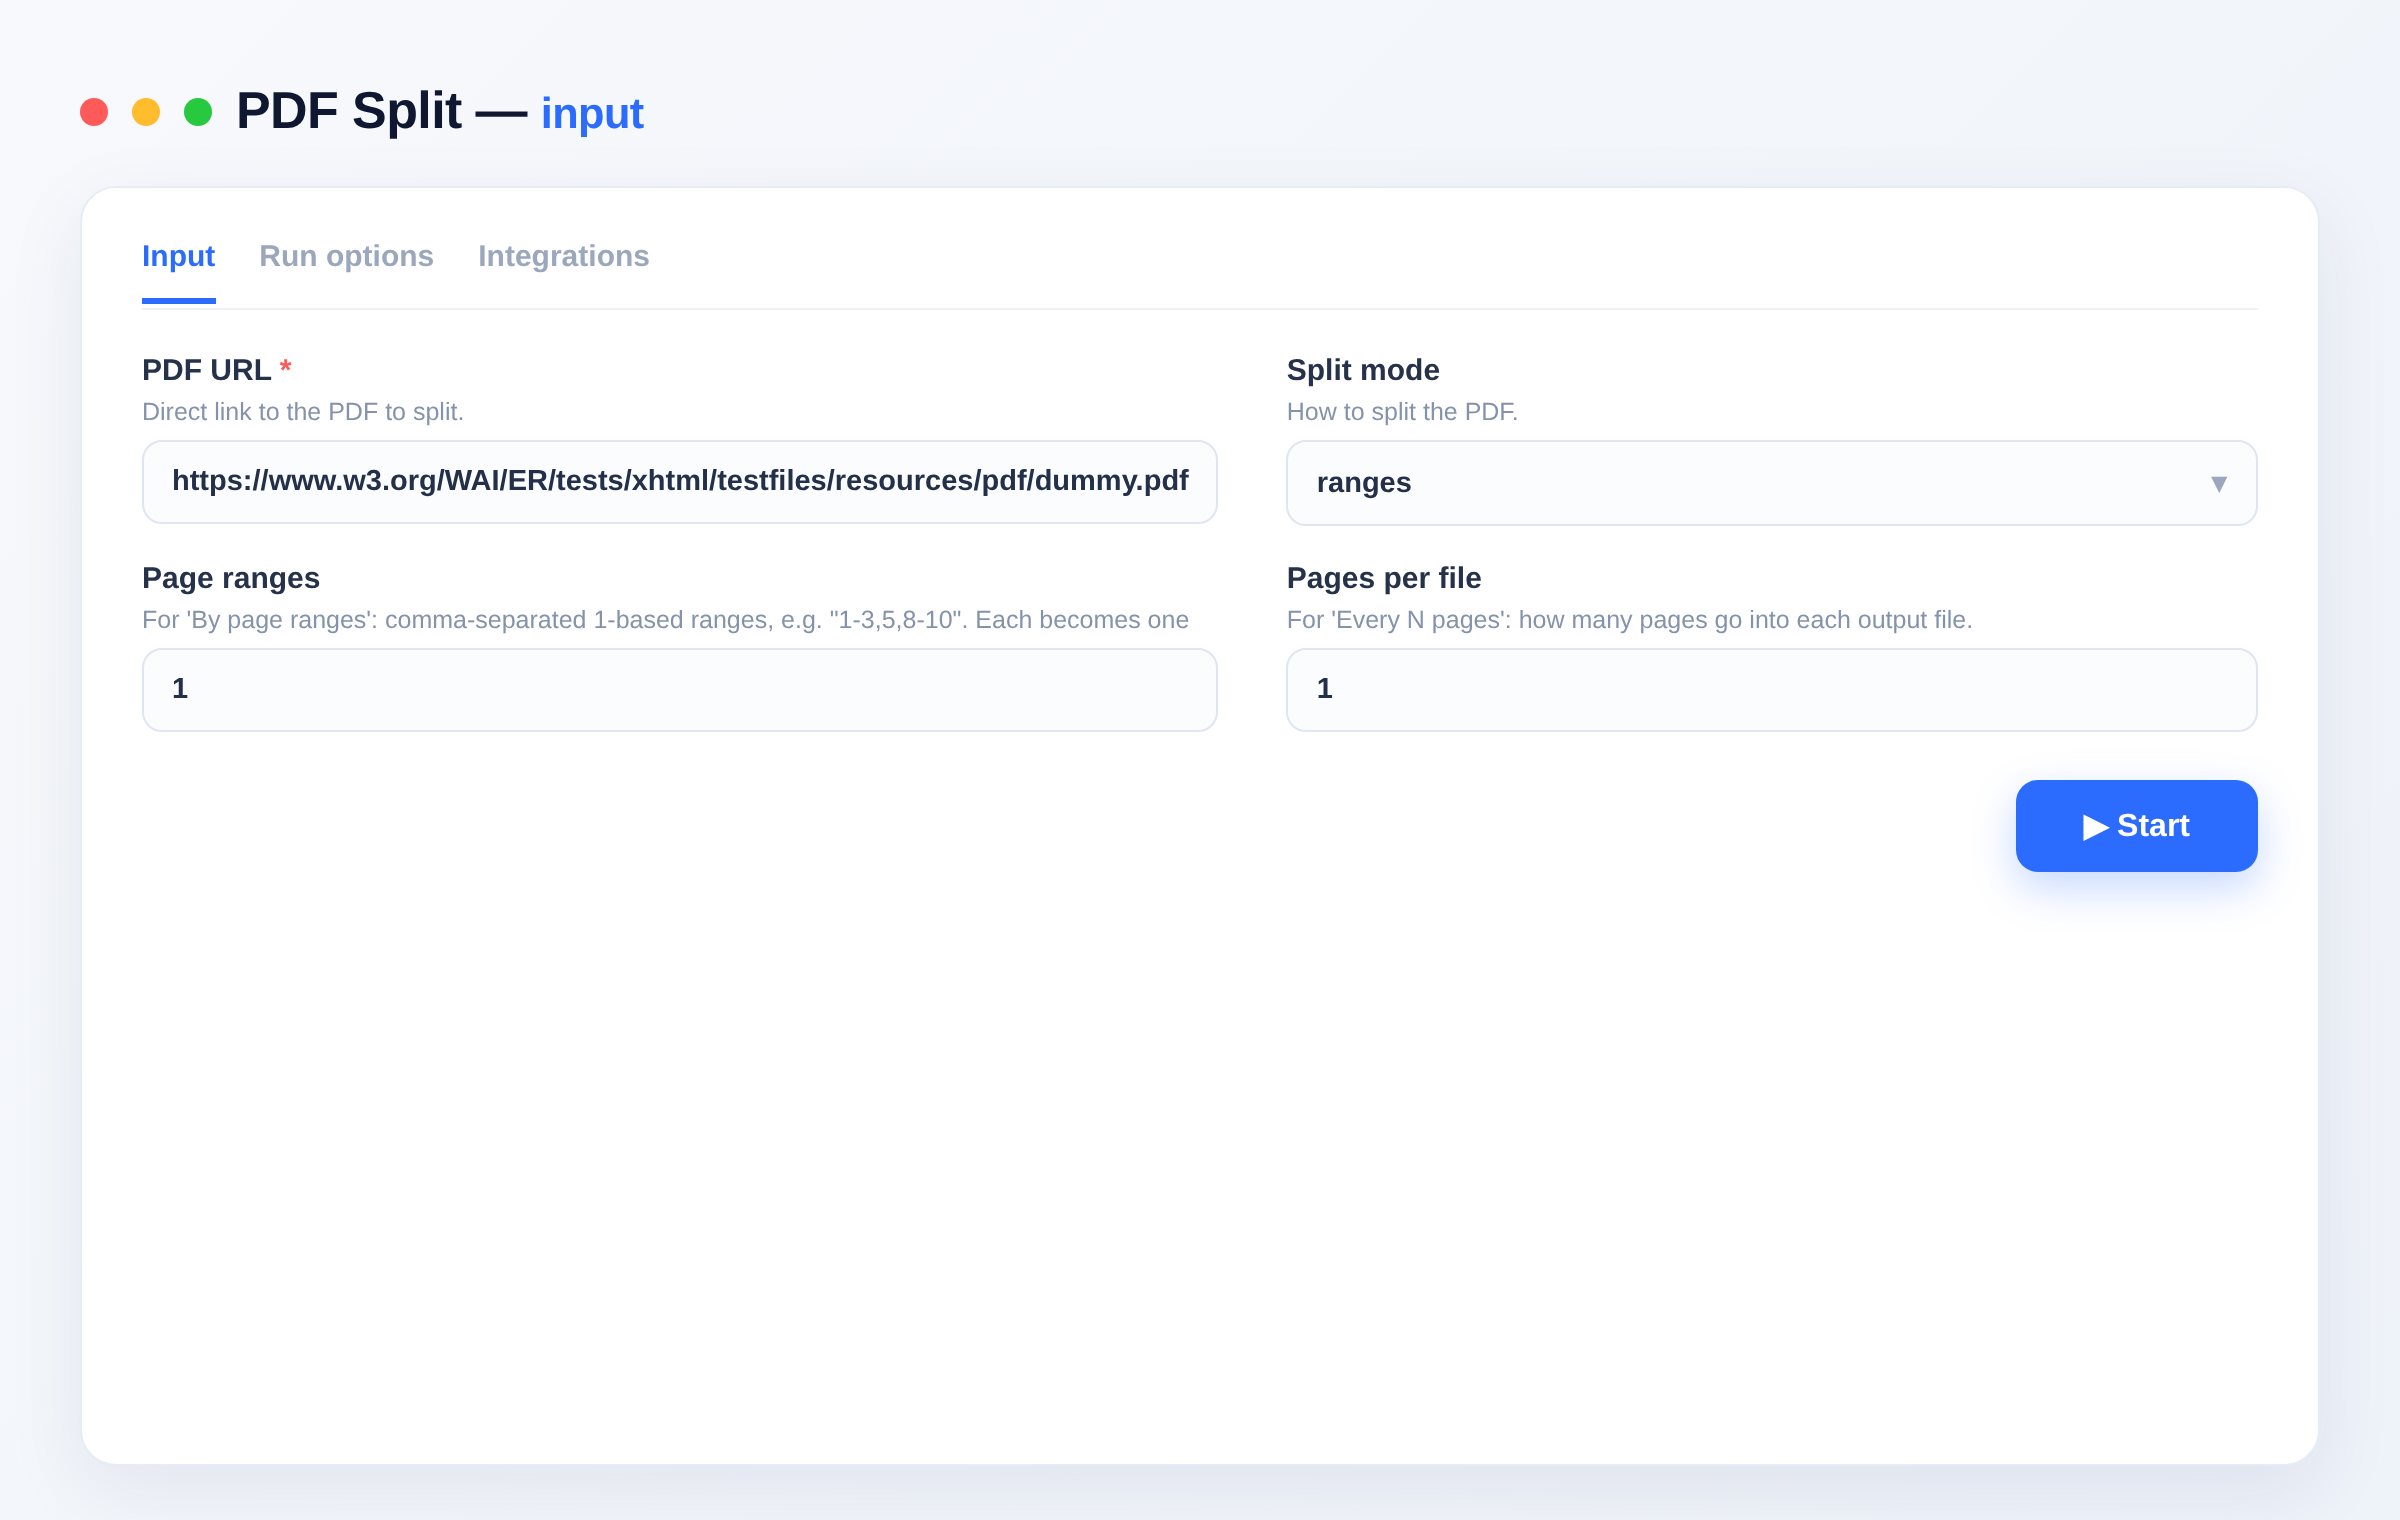
- By ranges —
1-3,5,8-10produces one file per range. - Every N pages — chunk a long PDF into equal parts.
- One file per page — explode a PDF into single pages.
Use cases
- Office — split a merged scan back into individual documents.
- Statements/invoices — break a combined PDF into per-customer files.
- Prep — extract just the pages you need.
Input
{ "pdfUrl": "https://example.com/doc.pdf", "mode": "ranges", "ranges": "1-3,5,8-10" }
| Field | Type | Description |
|---|---|---|
pdfUrl |
string | PDF to split. |
mode |
string | ranges, everyN or each. |
ranges |
string | 1-based ranges like 1-3,5,8-10 (ranges mode). |
everyN |
integer | Pages per output file (everyN mode). |
Output
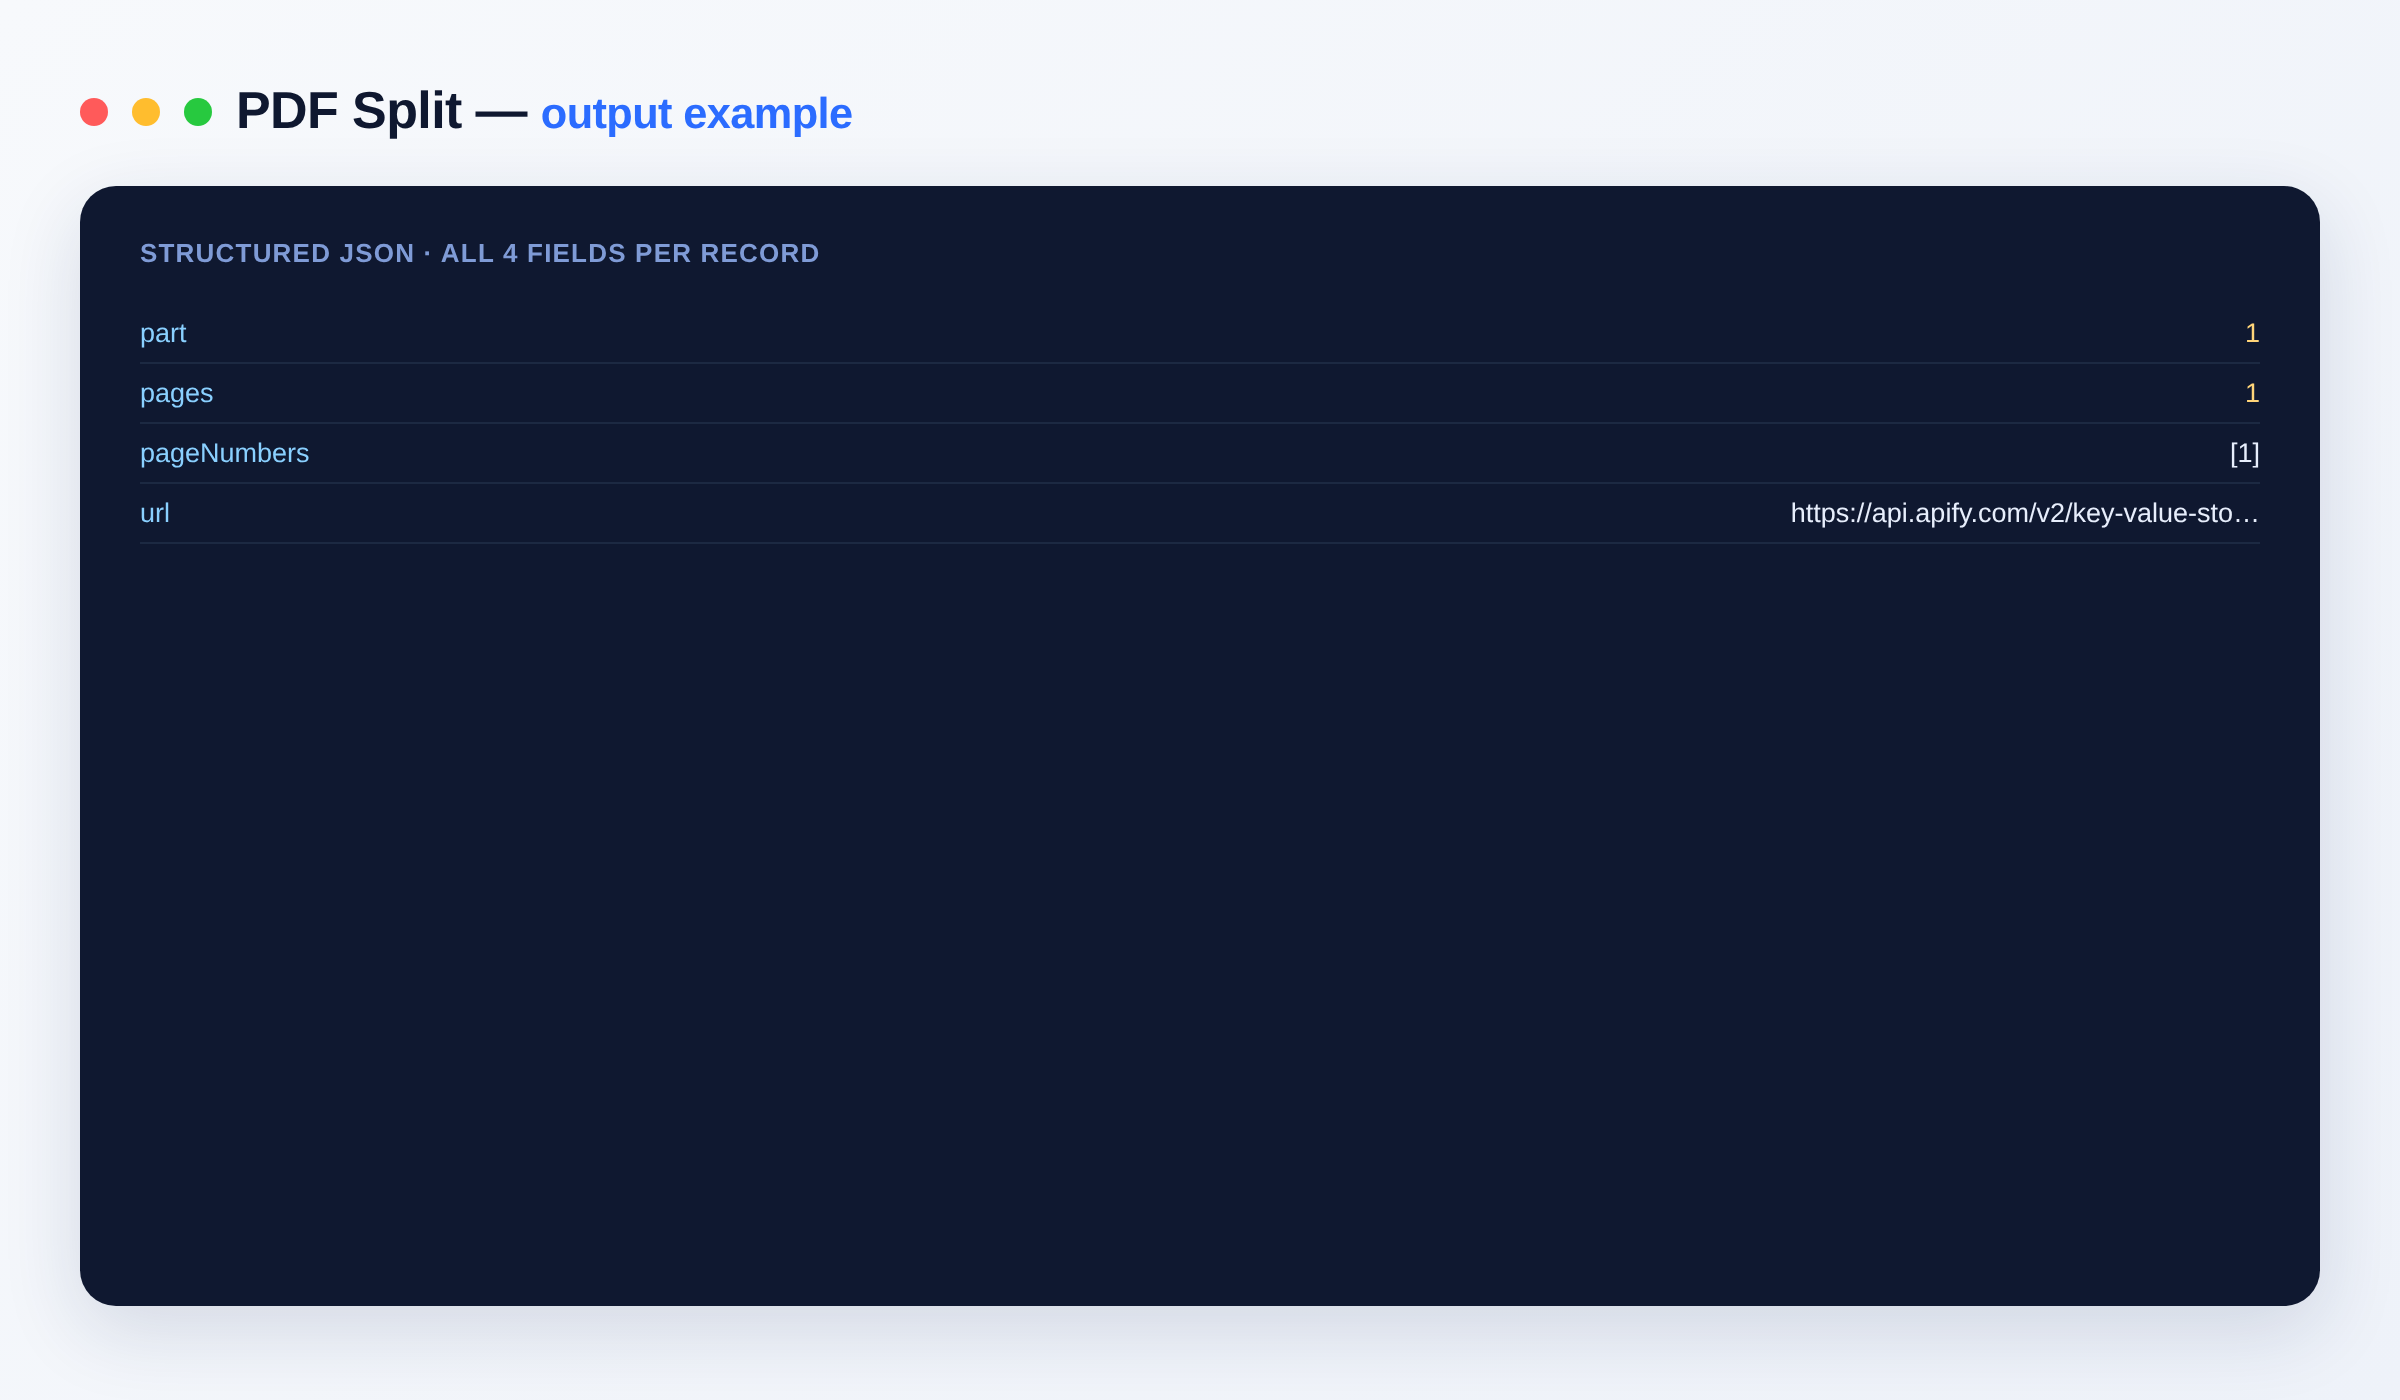
Each output file is one dataset row, saved to your key-value store.
{ "part": 1, "pages": 3, "pageNumbers": [1,2,3], "url": "https://api.apify.com/v2/key-value-stores/.../records/part-0001.pdf" }
Output schema
| Field | Type | Description |
|---|---|---|
part |
integer | Output file number. |
pages |
integer | Pages in this file. |
url |
string (URL) | Link to the split PDF. |
FAQ
Can I automate it? Yes — via integrations on the Apify platform and the Apify API.
Notes
Original clean-room implementation. Pairs with PDF Merge.
Input
| Field | Type | Description |
|---|---|---|
pdfUrl requiredPDF URL | string | Direct link to the PDF to split. |
modeSplit mode | string · ranges, everyN, each | How to split the PDF. Default: "ranges" |
rangesPage ranges | string | For 'By page ranges': comma-separated 1-based ranges, e.g. "1-3,5,8-10". Each becomes one file. |
everyNPages per file | integer | For 'Every N pages': how many pages go into each output file. Default: 1 |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~pdf-split/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "pdfUrl": "https://raw.githubusercontent.com/mozilla/pdf.js/master/web/compressed.tracemonkey-pldi-09.pdf",
  "ranges": "1-2,3"
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/pdf-split").call(run_input={
"pdfUrl": "https://raw.githubusercontent.com/mozilla/pdf.js/master/web/compressed.tracemonkey-pldi-09.pdf",
"ranges": "1-2,3"
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/pdf-split').call({
"pdfUrl": "https://raw.githubusercontent.com/mozilla/pdf.js/master/web/compressed.tracemonkey-pldi-09.pdf",
"ranges": "1-2,3"
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| PDF part created One output PDF file produced from the split | $0.005 | $0.0025 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Bulk Image Downloader
Download thousands of images from a list of URLs and store each in the key-value store with a public link. Returns content type, size, dimensions and SHA-256 per image. Bulk-ready. Great for datasets, backups and media pipelines.
8,102 runs · 103 users · $0.056 / url processed
Text to Speech
Convert any text to natural-sounding speech as an MP3 download. 300+ premium neural voices across 70+ languages, adjustable rate, pitch and volume. Great for voiceovers, videos, accessibility and audio content. No setup.
278 runs · 22 users · $0.01 / audio generated
Google Maps Email Extractor
Search Google Maps for businesses, then crawl each business website to extract emails, social profiles and extra phone numbers. Turns any Maps search into a ready lead list. No setup.
159 runs · 8 users · $0.006 / business lead scraped
Website Screenshot
Capture full-page or viewport screenshots of any URL as PNG or JPEG, at any device size. For monitoring, previews, thumbnails and automation workflows.
156 runs · 3 users · $0.004 / screenshot captured
Bulk URL Status Checker
Check thousands of URLs over plain HTTP: status codes, broken links (404/410/5xx), full redirect chains, response time, content type, page title and SSL certificate expiry.
154 runs · 13 users · $0.002 / url checked
Google Search Scraper
Scrape Google Search results (organic listings) for any query: title, URL, displayed URL, snippet and position. Multi-query, per-country/language, pagination. Uses Google SERP proxy — reliable, no captcha, no setup.
121 runs · 8 users · $0.001 / result scrapedSend the site and the fields. We build it and you get it first.