Scrapers / Developer & File Tools
Guokr Scraper
hipersoft/guokr-scraper
Scrape Guokr (果壳) popular-science articles: title, summary, preface, author, image and publish date.
Total users
2Monthly users
1Total runs
84Per article scraped
$0.001Last rebuilt
Oct 26, 2026Overview
Scrape Guokr (果壳), one of China's leading popular-science and knowledge communities, into clean JSON, CSV, Excel or XML. This Guokr scraper extracts article titles, summaries, prefaces, authors, images, editor picks and publish dates from the article feed — structured, ready for research, analytics or LLM pipelines. A fast, reliable, no-code way to build a China science-content dataset.
Instead of copy-pasting articles by hand, point the Actor at the feed, set how many items you want, and get every article as a clean row. It's one of the cheapest ways to collect Chinese popular-science content at scale.
What does the Guokr Scraper do?
The Guokr Scraper crawls and extracts public Guokr (果壳) content from the article feed and returns it as structured data points — title, summary, preface, author, author profile URL, cover image, editor-pick flag, publish and last-modified dates, and the article URL. Set a single limit and export the results as JSON, CSV, Excel or XML, or pull them straight from the API for datasets, media monitoring, content aggregation or machine-learning corpora.
What data can you scrape from Guokr?
| Group | Fields |
|---|---|
| 📰 Article | id, title, summary, preface, cover image, article URL |
| ✍️ Author | author name, author key, author profile URL |
| 🗓️ Dates | published timestamp, last-modified timestamp, collected timestamp |
| ⭐ Editorial | editor-recommended flag |
Use cases
- Build a China science-content dataset — thousands of popular-science articles with titles, summaries and metadata for analysis or training data.
- Feed articles to an LLM — summaries, prefaces and titles make ready input for RAG knowledge bases, translation and content repurposing.
- Media & topic monitoring — track what a major Chinese science community is publishing, and when.
- Content aggregation — surface and republish (within terms) the latest science stories for a newsletter or portal.
- Trend & topic discovery — spot emerging themes across science, technology and research coverage.
- Author & editorial research — see which authors publish what, and which pieces get the editor-pick flag.
- Academic & market research — study publishing cadence, topics and editorial signals from public data.
How to scrape Guokr data
- Click Try for free / Start to open the Guokr Scraper.
- Set
maxItems— how many articles you want from the feed. - Click Run.
- Watch the dataset fill with articles in real time.
- Download the results as JSON, CSV, Excel or XML, or pull them from the API.
Input
The Guokr Scraper takes a single, simple input: how many articles to collect.
{
  "maxItems": 200
}
| Field | Type | Description |
|---|---|---|
maxItems |
integer | Maximum number of articles to scrape from the Guokr feed (default 100). |
Output
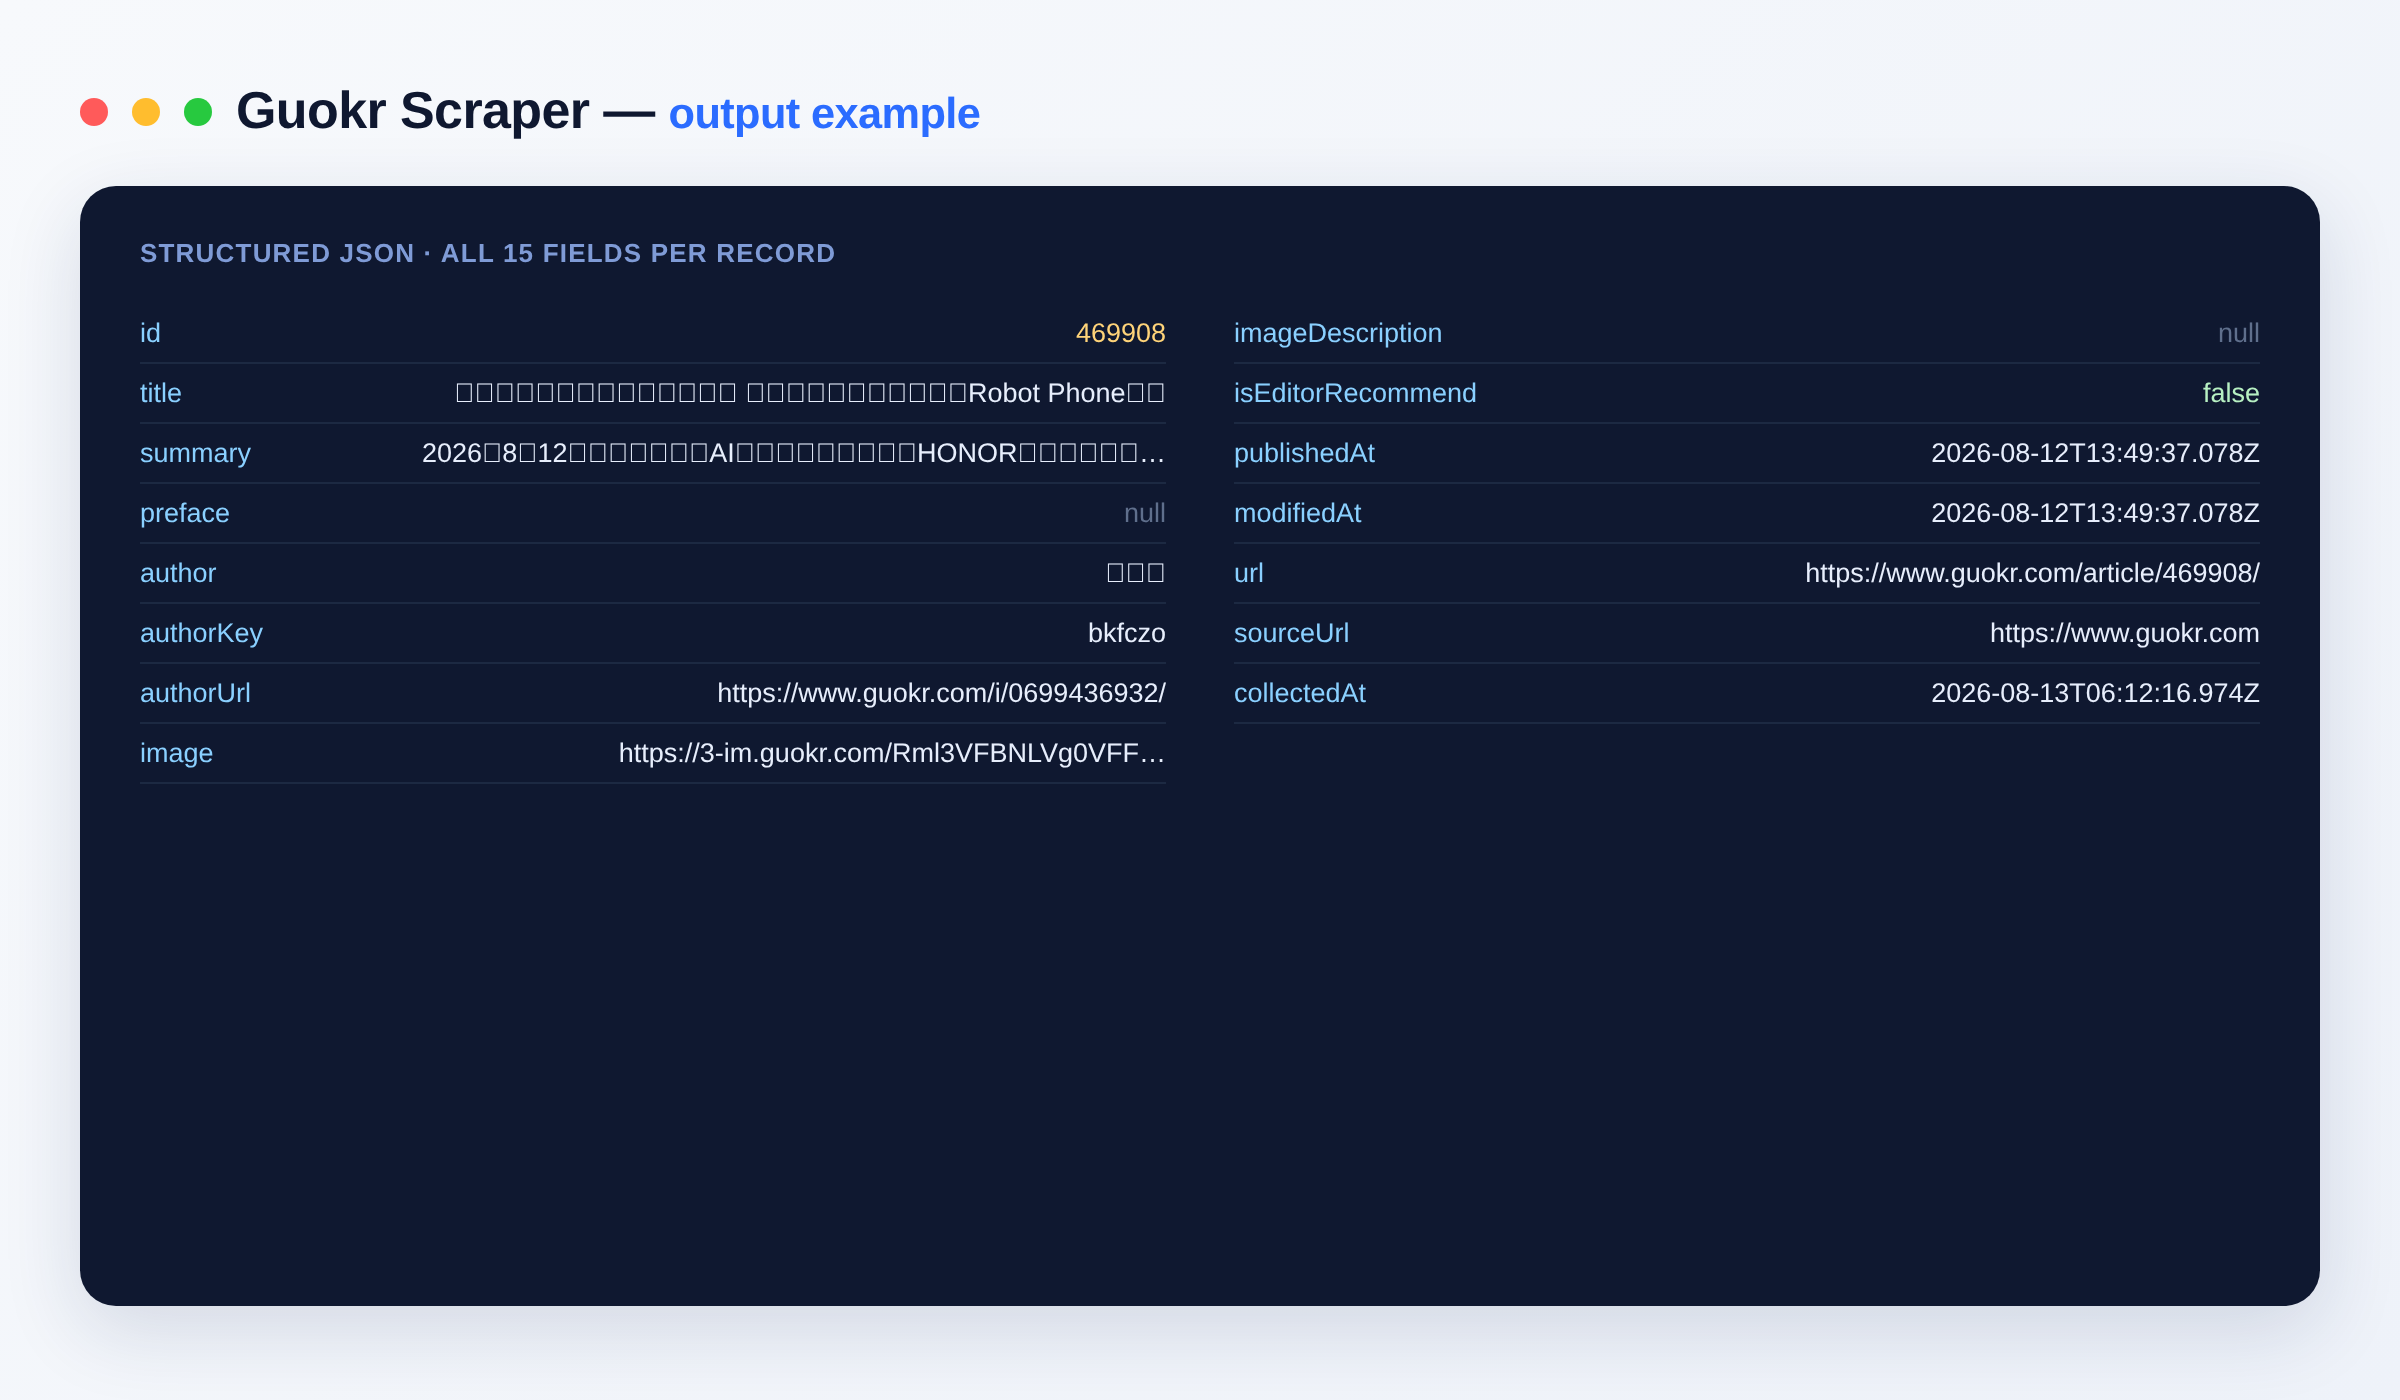
Each article is one dataset item:
{
  "id": 469796,
  "title": "谷歌 DeepMind 解散 AlphaFold 团队;字节跳动重组人工智能业务线……",
  "summary": "……",
  "preface": "……",
  "author": "果壳",
  "authorKey": "sbhkv5",
  "authorUrl": "https://www.guokr.com/i/1712348897/",
  "image": "https://1-im.guokr.com/....jpg",
  "isEditorRecommend": false,
  "publishedAt": "2026-07-30T12:15:02.974Z",
  "modifiedAt": "2026-07-30T12:20:00.000Z",
  "url": "https://www.guokr.com/article/469796/",
  "collectedAt": "2026-07-30T12:00:00.000Z"
}
Output schema
| Field | Type | Description |
|---|---|---|
id |
integer | Guokr article ID. |
title |
string | Article title (Chinese). |
summary |
string | Short article summary. |
preface |
string | Article preface / lead text. |
author |
string | Author display name. |
authorKey |
string | Author identifier key. |
authorUrl |
string (URL) | Link to the author's Guokr profile. |
image |
string (URL) | Cover image URL for the article. |
isEditorRecommend |
boolean | Whether the article is flagged as an editor pick. |
publishedAt |
string (ISO date) | When the article was published. |
modifiedAt |
string (ISO date) | When the article was last modified. |
url |
string (URL) | Canonical URL of the article on Guokr. |
collectedAt |
string (ISO date) | When the item was collected by the run. |
Need more Chinese content data?
Building a wider China content dataset? Pair the Guokr Scraper with our other scrapers for Chinese tech, science and media platforms:
- SSPAI Scraper — Chinese tech and productivity articles.
- Juejin Scraper — developer and programming posts from 掘金.
- IThome Scraper — Chinese tech news and headlines.
- Bilibili Scraper — videos, creators and stats from Bilibili.
FAQ
Do I need any setup or a login to scrape Guokr?
No. There's no setup and no login — just set maxItems and run. It's a no-code tool: everything happens in the Apify Console.
How many articles can I scrape per run?
As many as the feed provides — set maxItems to control the cap (up to 100,000). Start small to preview, then raise the limit for a full dataset.
How much does it cost? You pay only per article you get, which makes this one of the cheapest ways to collect Chinese science content — no monthly minimum and no per-tool licensing.
What export formats are supported? JSON, CSV, Excel and XML, plus webhooks and the Apify API.
What about likes, comments or view counts? The feed does not expose engagement metrics, so this Actor focuses on article content and metadata — titles, summaries, prefaces, authors, images and dates.
How fresh is the data?
Each run reads the current feed, so you get the latest articles at the time of the run. The collectedAt timestamp records exactly when each item was captured.
Can I automate or integrate the Guokr Scraper? Yes. The Guokr Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes — get a notification, or kick off another process such as loading your data downstream.
Is scraping Guokr legal? The Actor collects only public data. You are responsible for how you use it and for complying with Guokr's terms and applicable laws.
Notes
Original clean-room implementation. Returns only public Guokr data; you are responsible for how you use the data and for complying with Guokr's terms. This is an independent tool and is not affiliated with or endorsed by Guokr (果壳).
Input
| Field | Type | Description |
|---|---|---|
maxItemsMax articles | integer | Maximum articles to scrape from the Guokr feed. Default: 100 |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~guokr-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/guokr-scraper").call(run_input={})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/guokr-scraper').call({});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Article scraped One Guokr article scraped. | $0.001 | $0.001 |
| API request One Guokr feed API request. | $0.0008 | $0.0008 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Bulk Image Downloader
Download thousands of images from a list of URLs and store each in the key-value store with a public link. Returns content type, size, dimensions and SHA-256 per image. Bulk-ready. Great for datasets, backups and media pipelines.
8,102 runs · 103 users · $0.056 / url processed
Text to Speech
Convert any text to natural-sounding speech as an MP3 download. 300+ premium neural voices across 70+ languages, adjustable rate, pitch and volume. Great for voiceovers, videos, accessibility and audio content. No setup.
278 runs · 22 users · $0.01 / audio generated
Google Maps Email Extractor
Search Google Maps for businesses, then crawl each business website to extract emails, social profiles and extra phone numbers. Turns any Maps search into a ready lead list. No setup.
159 runs · 8 users · $0.006 / business lead scraped
Website Screenshot
Capture full-page or viewport screenshots of any URL as PNG or JPEG, at any device size. For monitoring, previews, thumbnails and automation workflows.
156 runs · 3 users · $0.004 / screenshot captured
Bulk URL Status Checker
Check thousands of URLs over plain HTTP: status codes, broken links (404/410/5xx), full redirect chains, response time, content type, page title and SSL certificate expiry.
154 runs · 13 users · $0.002 / url checked
Google Search Scraper
Scrape Google Search results (organic listings) for any query: title, URL, displayed URL, snippet and position. Multi-query, per-country/language, pagination. Uses Google SERP proxy — reliable, no captcha, no setup.
121 runs · 8 users · $0.001 / result scrapedSend the site and the fields. We build it and you get it first.