Google Images Scraper
hipersoft/google-images-scraper
Scrape Google Images by keyword: full-size image URL, width and height, thumbnail, title, source page and domain. Filter by size, type, color and usage rights. Bulk searches, any country and language, for datasets, research and AI.
Total users
2Monthly users
1Total runs
5Per image scraped
$0.003Last rebuilt
Nov 4, 2026Overview
Google Images Scraper extracts image results from Google Images in bulk: full-size image URL, width and height, thumbnail, title, source page and domain, file size and dominant color. Filter by size, type, color and usage rights, run many searches at once, and export to JSON, CSV or Excel.
What does Google Images Scraper do?
Give it search terms and it returns one row per image result, with the link to the original image and the page it came from. It returns links and details, not the image files. To save the files, feed imageUrl into Bulk Image Downloader.
What data can you scrape from Google Images?
| Data | Fields |
|---|---|
| Image | imageUrl, imageWidth, imageHeight, fileSize, dominantColor |
| Thumbnail | thumbnailUrl, thumbnailWidth, thumbnailHeight |
| Source | title, sourcePageUrl, sourceDomain, sourceName |
| Context | query, position, googleImageId, collectedAt |
Use cases
- AI and computer vision: build image datasets from many searches.
- Brand monitoring: see which sites show your products or logo.
- Market research: study how a product is shown across shops.
- SEO: see which pages rank for your image searches.
- Content research: find reference images and where they come from.
How to scrape Google Images
- Open Google Images Scraper.
- Add your image searches.
- Pick any filters, and a country and language if you need them.
- Click Start.
- Export the results, or send
imageUrlto a downloader.
How many images do I get per search?
Up to about 200 images per search. A test asking for 600 returned 191 unique images, because Google stops offering new ones after that. To collect more, use more specific searches or combine filters. You pay only for images delivered.
Input
{
  "queries": ["mountain lake", "alpine lake"],
  "size": "large",
  "imageType": "photo",
  "usageRights": "creative_commons",
  "excludeDomains": ["pinterest.com"],
  "maxResultsPerQuery": 100
}
| Field | Description |
|---|---|
queries |
What to search for. |
maxResultsPerQuery |
Images per search (default 100, about 200 at most). |
size |
any, large, medium or icon. |
imageType |
any, photo, clipart, lineart or animated. |
color |
any, color, grayscale, transparent, or a color such as red or blue. |
usageRights |
any, creative_commons or commercial. |
excludeDomains |
Sites to leave out. |
safeSearch |
Filter explicit results. |
country / language |
Two-letter codes (default us, en). |
Output
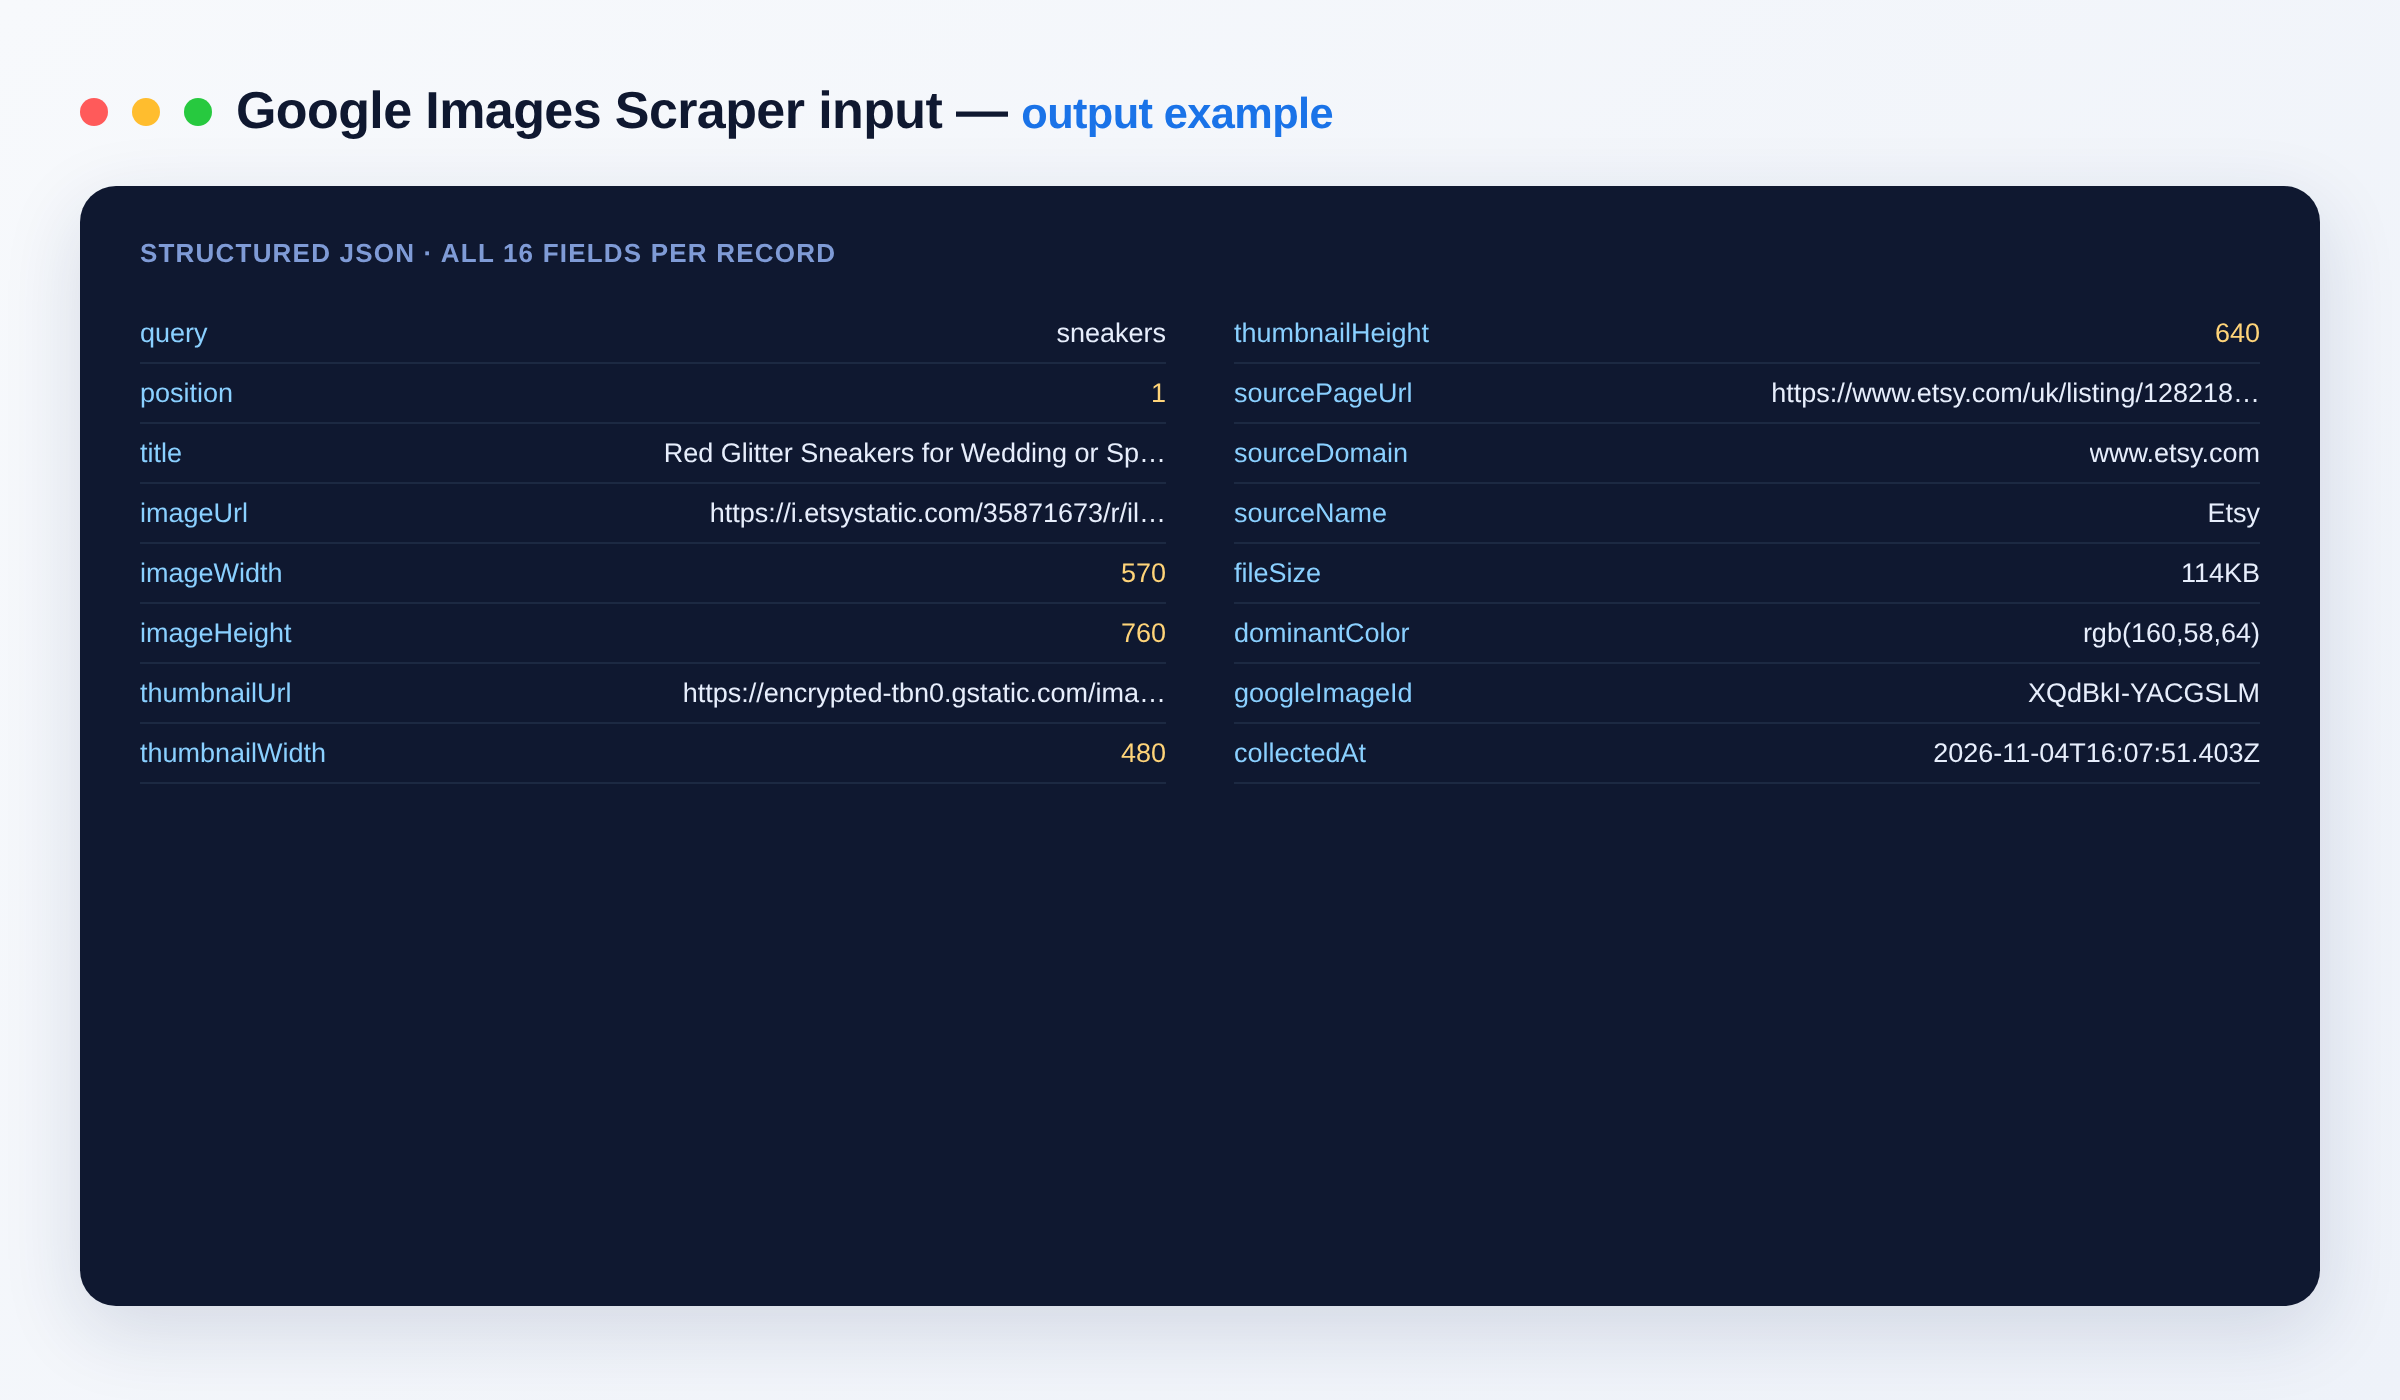
A real row from a test run.
{
  "query": "mountain lake",
  "position": 1,
  "title": "File:Mountain lake in Switzerland.jpg - Wikimedia Commons",
  "imageUrl": "https://upload.wikimedia.org/wikipedia/commons/0/06/Mountain_lake_in_Switzerland.jpg?utm_source=commons.wikimedia.org&utm_campaign=index&utm_content=original",
  "imageWidth": 1200,
  "imageHeight": 1600,
  "thumbnailUrl": "https://encrypted-tbn0.gstatic.com/images?q=tbn:ANd9GcSoBqlbAYLAWxeH_vMX3WZQ_y7zHXvcdeQ00iI6L0GLjw&s=10",
  "thumbnailWidth": 387,
  "thumbnailHeight": 516,
  "sourcePageUrl": "https://commons.wikimedia.org/wiki/File:Mountain_lake_in_Switzerland.jpg",
  "sourceDomain": "commons.wikimedia.org",
  "sourceName": "Wikimedia Commons",
  "fileSize": "541KB",
  "dominantColor": "rgb(60,172,169)",
  "googleImageId": "-3NBJaOn6q_yXM",
  "collectedAt": "2026-11-04T16:07:46.269Z"
}
Output schema
| Field | Type | Description |
|---|---|---|
query |
string | The search. |
position |
integer | Position in the results for this search. |
title |
string | Title of the source page. |
imageUrl |
string (URL) | Link to the original image. |
imageWidth / imageHeight |
integer | Original size in pixels. |
thumbnailUrl |
string (URL) | Small preview image. |
thumbnailWidth / thumbnailHeight |
integer | Preview size in pixels. |
sourcePageUrl |
string (URL) | Page the image appears on. |
sourceDomain |
string | Site of that page. |
sourceName |
string | Site name, when shown. |
fileSize |
string | File size as shown. |
dominantColor |
string | Main color of the image. |
googleImageId |
string | Google's ID for this result. |
collectedAt |
string (ISO date) | When the row was collected. |
Need the image files too?
- Bulk Image Downloader: download image URLs to stored files.
- Website Image Downloader: download every image from a web page or site.
- Google Search Scraper: web results, ads and more.
FAQ
How much does it cost? You pay per image delivered, shown on the Pricing tab. Set a maximum cost per run and it stops cleanly at that limit, storing only what you paid for.
Can I use these images freely? Not automatically. Images belong to their owners. The Usage rights filter uses what the search reports, so always check the license on the source page before reusing an image.
Does it download the images? No, it returns links and details. Use Bulk Image Downloader for the files.
Why did I get fewer images than my maximum? Each search reaches about 200 images at most. Very specific filters can return fewer.
Can I connect this to other tools? Yes, through integrations on the Apify platform: Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API and webhooks.
Is it legal to scrape Google Images? It returns publicly listed results. You are responsible for how you use them, including copyright and each site's terms.
Feedback
How did it go? Good or bad, a review helps other users decide and tells us what to improve. Something broken or missing? Open an issue and we'll look at it.
Notes
Independent tool, not affiliated with Google. Returns only public data; you are responsible for how you use it.
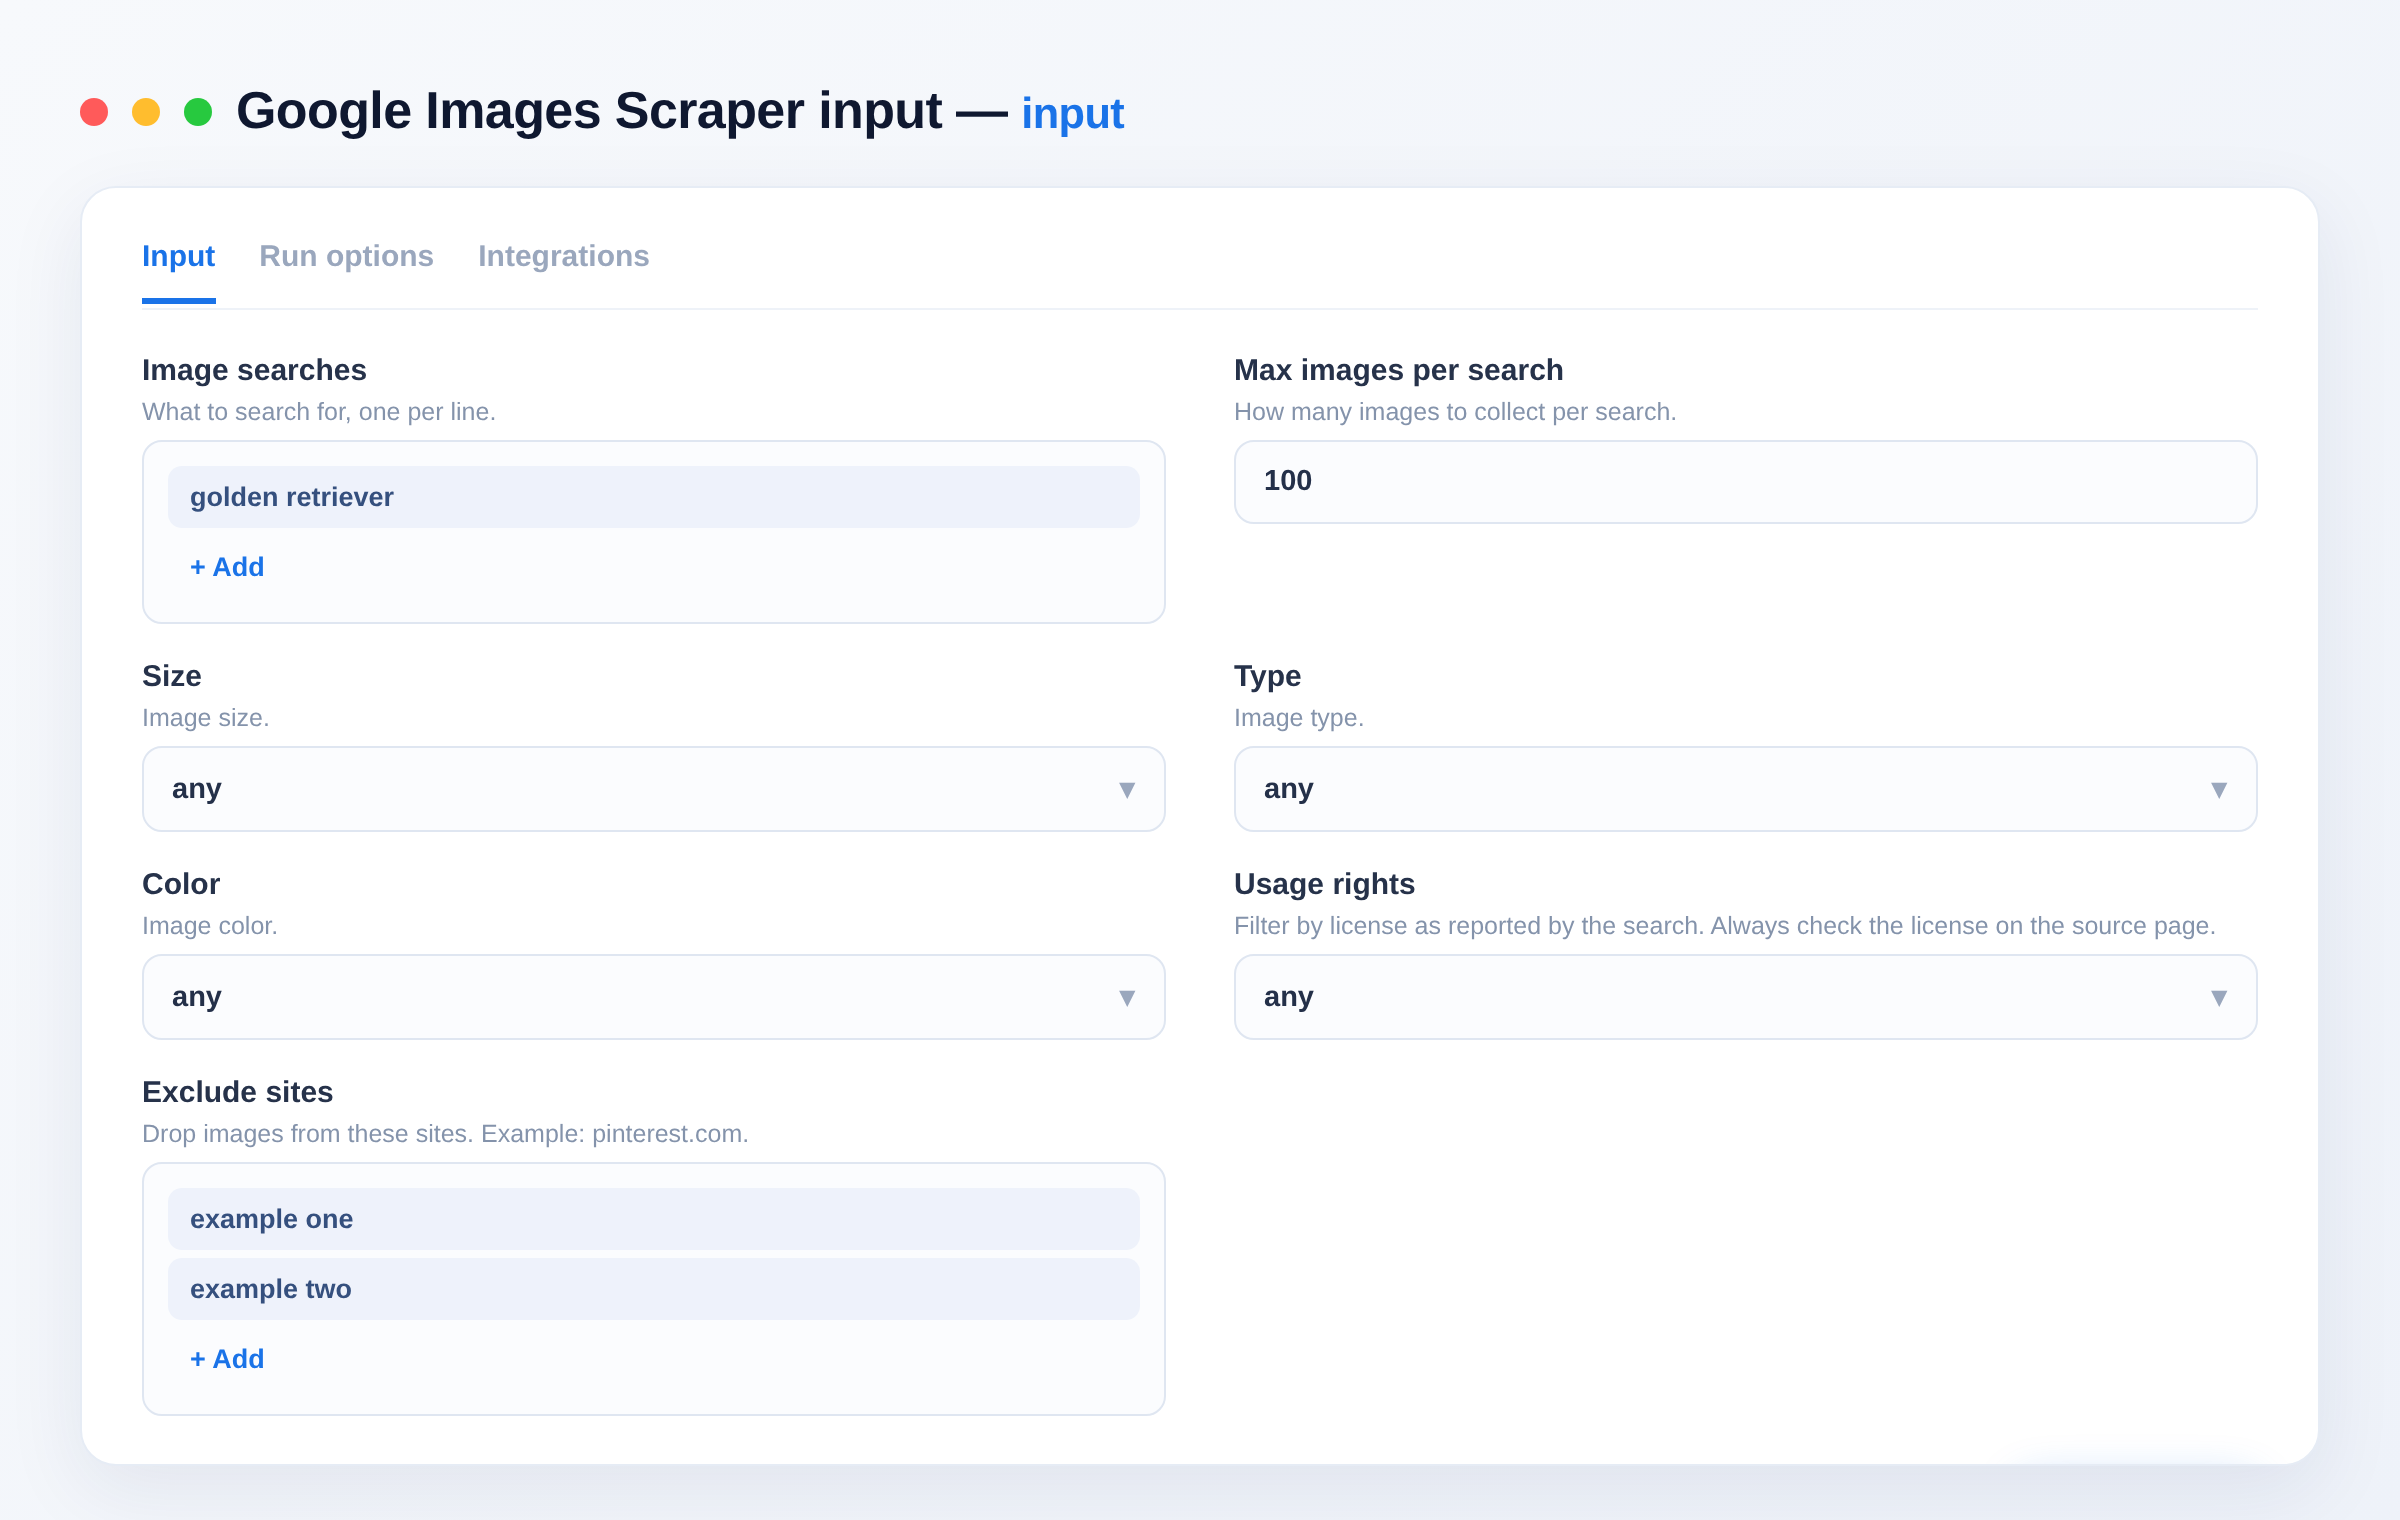
Input
| Field | Type | Description |
|---|---|---|
queriesImage searches | array | What to search for, one per line. |
maxResultsPerQueryMax images per search | integer | How many images to collect per search. Default: 100 |
sizeSize | string · any, large, medium, icon | Image size. Default: "any" |
imageTypeType | string · any, photo, clipart, lineart, animated | Image type. Default: "any" |
colorColor | string · any, color, grayscale, transparent, red, orange… | Image color. Default: "any" |
usageRightsUsage rights | string · any, creative_commons, commercial | Filter by license as reported by the search. Always check the license on the source page. Default: "any" |
excludeDomainsExclude sites | array | Drop images from these sites. Example: pinterest.com. |
safeSearchSafeSearch | boolean | Filter explicit results. Default: false |
countryCountry code | string | Two-letter country to search from. Default: "us" |
languageLanguage | string | Two-letter language code. Default: "en" |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~google-images-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "queries": [
    "golden retriever"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/google-images-scraper").call(run_input={
"queries": [
"golden retriever"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/google-images-scraper').call({
"queries": [
"golden retriever"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Image scraped One image result delivered. | $0.003 | $0.0015 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
North Data Scraper
Look up European companies on North Data: legal name, former names, register number, address, founding date, LEI, business purpose, managing directors and officers, and recent register publications. Germany, UK, France, Austria and 20+ countries. Bulk lookups.
2,468 runs · 5 users · $0.004 / company
Website Content Crawler
Extract clean, readable content from any list of websites: page title, meta description, headings, main body text, word count and link/image counts. Optional same-domain crawl. Bulk-ready. Great for LLM/RAG ingestion, content audits and research.
207 runs · 20 users · $0.0024 / page scraped
SpyFu Domain Scraper
Bulk SEO and PPC reports for any domain from SpyFu: organic keywords, monthly SEO clicks and value, Google Ads budget, paid keywords, top keywords, competitors, top countries and monthly history. Competitor research for agencies. Export CSV/JSON.
204 runs · 7 users · $0.008 / domain report
Trustpilot Reviews Scraper
Scrape Trustpilot reviews and company ratings by company domain or Trustpilot URL: star rating, title, text, reviewer name & country, verification, date, company reply, plus company TrustScore and total reviews.
148 runs · 4 users · $0.0006 / review scraped
ACRA Singapore Company Registry Scraper
Search and export Singapore's full ACRA corporate registry: UEN, entity name, status, incorporation date, address, SSIC industry codes, officers, former names and audit firms. Filter by name, status, entity type or industry. Public open data, no setup.
139 runs · 10 users · $0.01 / company scraped
Wayback Machine Scraper
List every Internet Archive (Wayback Machine) snapshot of a URL or whole domain: timestamp, snapshot URL, status code, MIME type and content digest. Filter by date, status and dedupe. For SEO, OSINT and historical research. No setup.
136 runs · 15 users · $0.002 / snapshot scrapedSend the site and the fields. We build it and you get it first.