Google News Scraper
hipersoft/google-news-scraper
Scrape Google News for any search keyword or topic section (Business, Technology, Sports…). Returns headline, source, publish time, article link and snippet for any language and country. No setup.
Total users
4Monthly users
1Total runs
113Per article scraped
$0.0043Last rebuilt
Oct 28, 2026Overview
Monitor the news at scale. Give the Actor any set of search keywords or topic sections and it returns fresh Google News articles — headline, source, publish time, link and snippet — for any language and country edition. Powered by Google News's public RSS feeds, so no login and no API key.
Great for media monitoring, brand/competitor tracking, PR, research datasets, and news alerting. Export to JSON, CSV or Excel.
Features
- 📰 Keyword & topic feeds — pull articles by search term or by section (Technology, Business, Sports…).
- 🌍 Any edition — set the
language/countrypair to target any Google News edition. - 🧹 Clean headlines — Google's trailing " - Source" is stripped and the publisher is captured separately.
- 🔁 De-duplicated — overlapping queries and topics are merged within a run.
- 🎚️ Volume control —
maxItemsPerFeedandmaxConcurrencytune throughput and size.
What you get per article
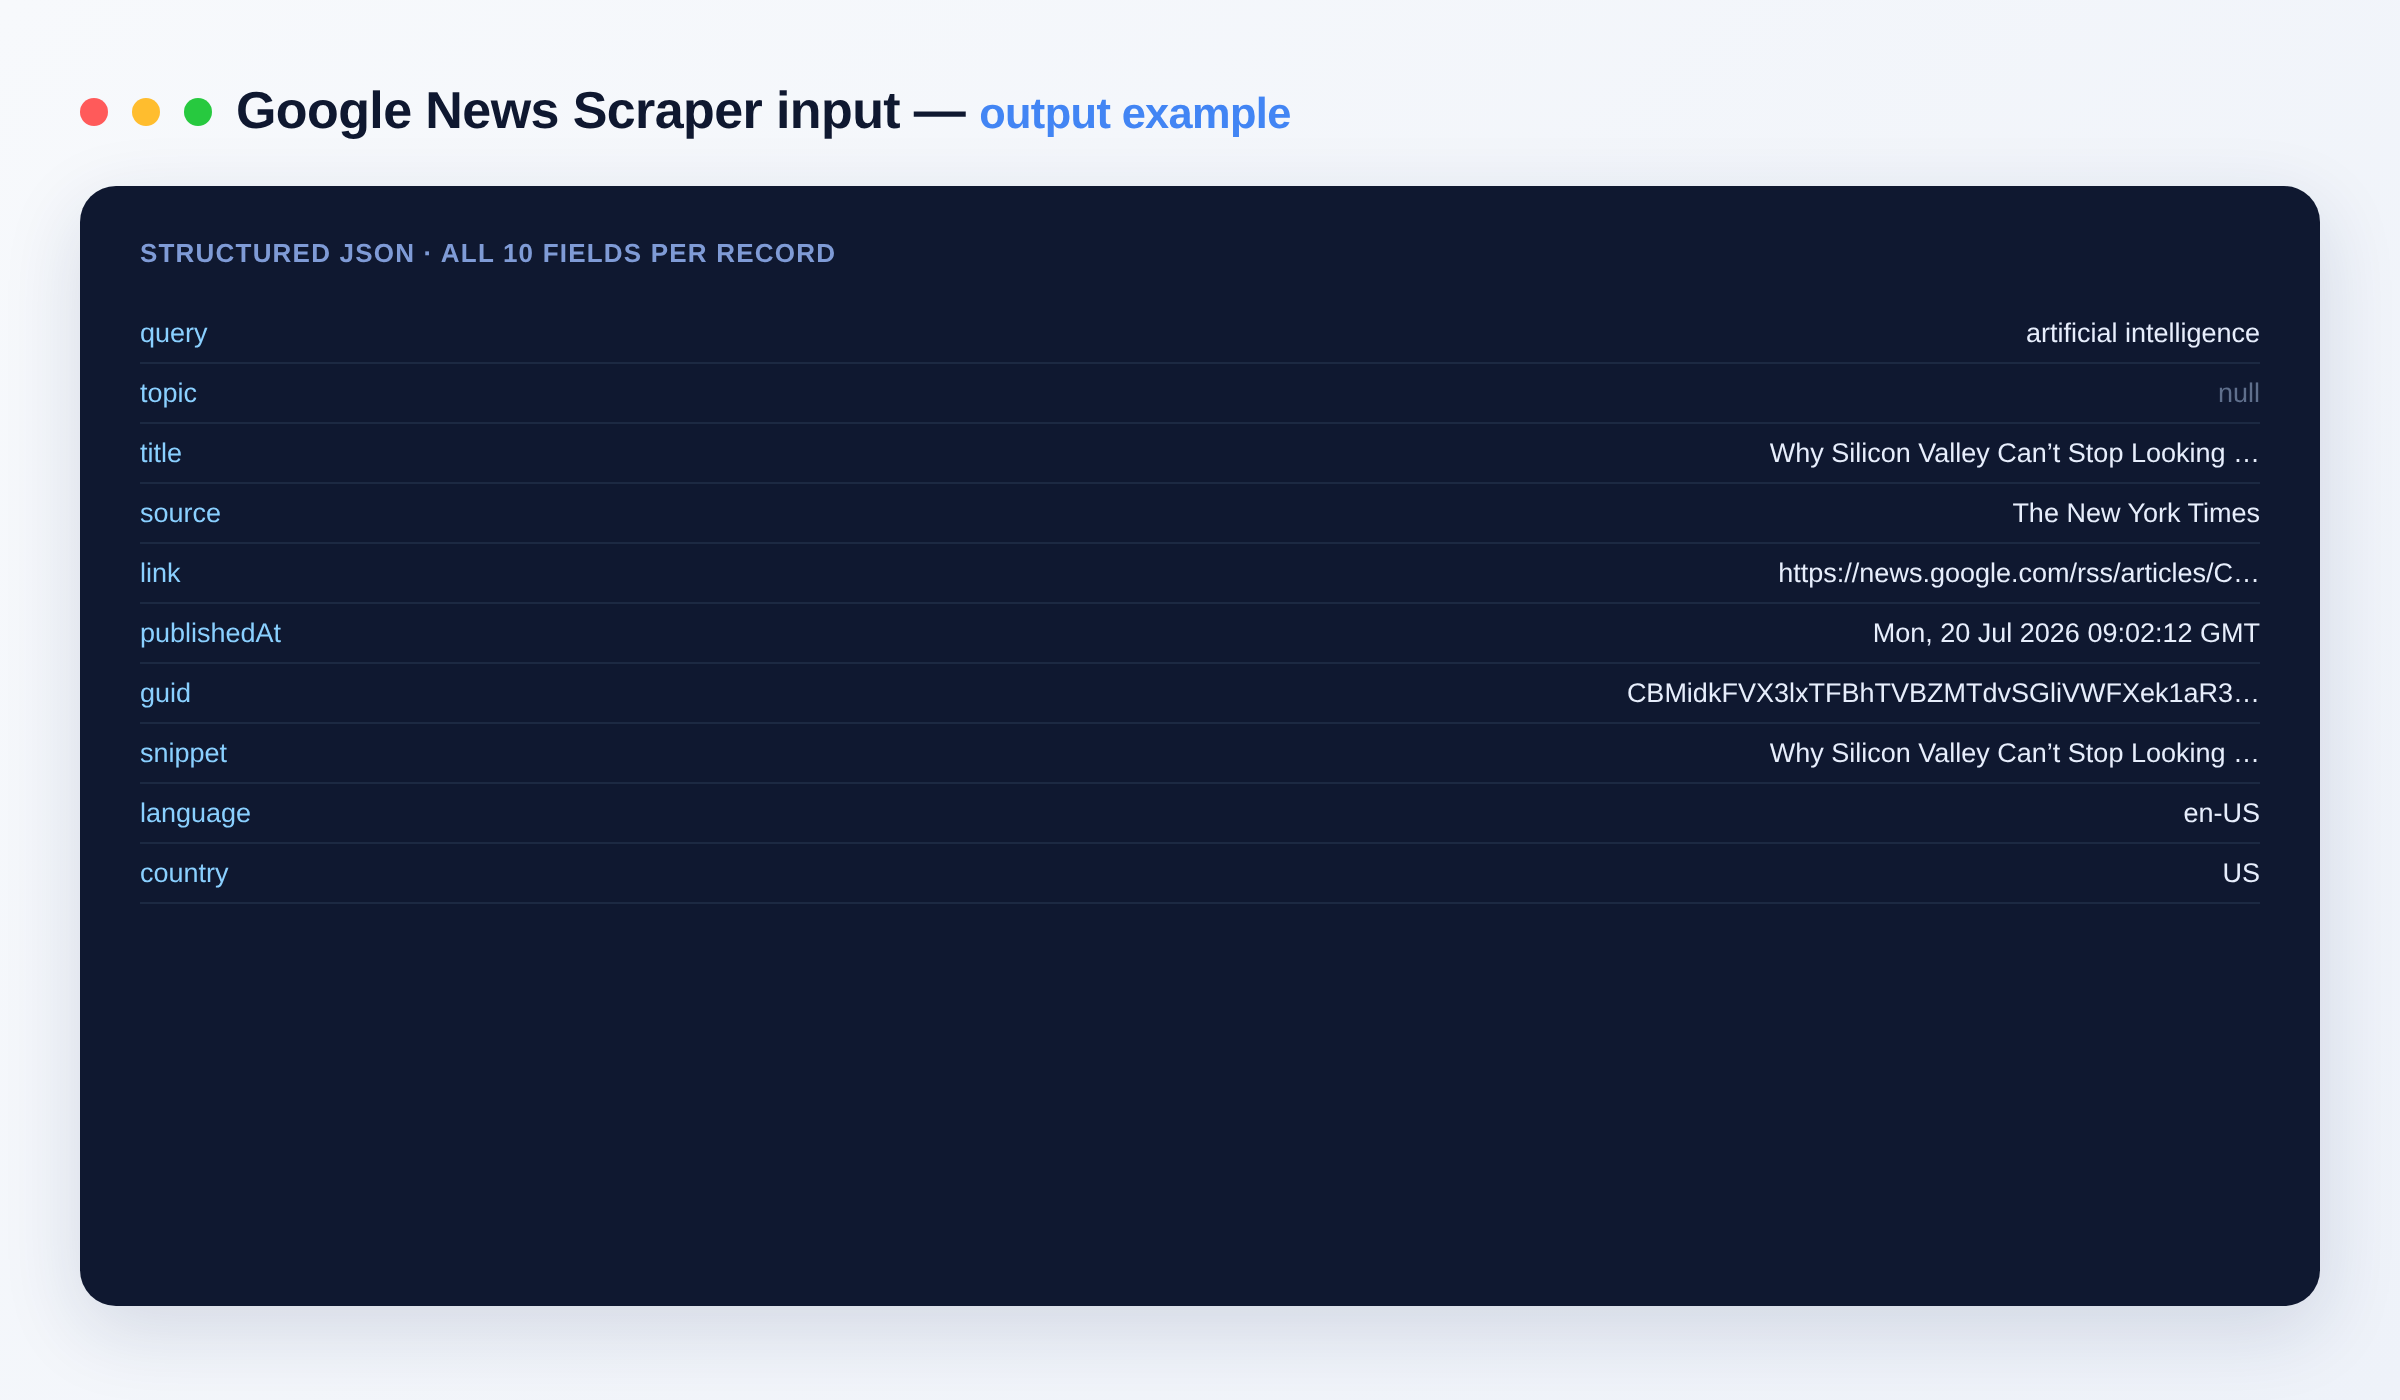
| Field | Notes |
|---|---|
title |
Clean headline (Google's trailing " - Source" is stripped out). |
source |
Publisher name (e.g. Reuters, BBC). |
publishedAt |
Publish time (RFC-822). |
link |
Google News article link. |
snippet |
Short text snippet when the feed provides one. |
query / topic |
Which search term or section the article came from. |
language / country |
The edition used (hl / gl). |
Results are de-duplicated across overlapping queries/topics within a run.
Input
{
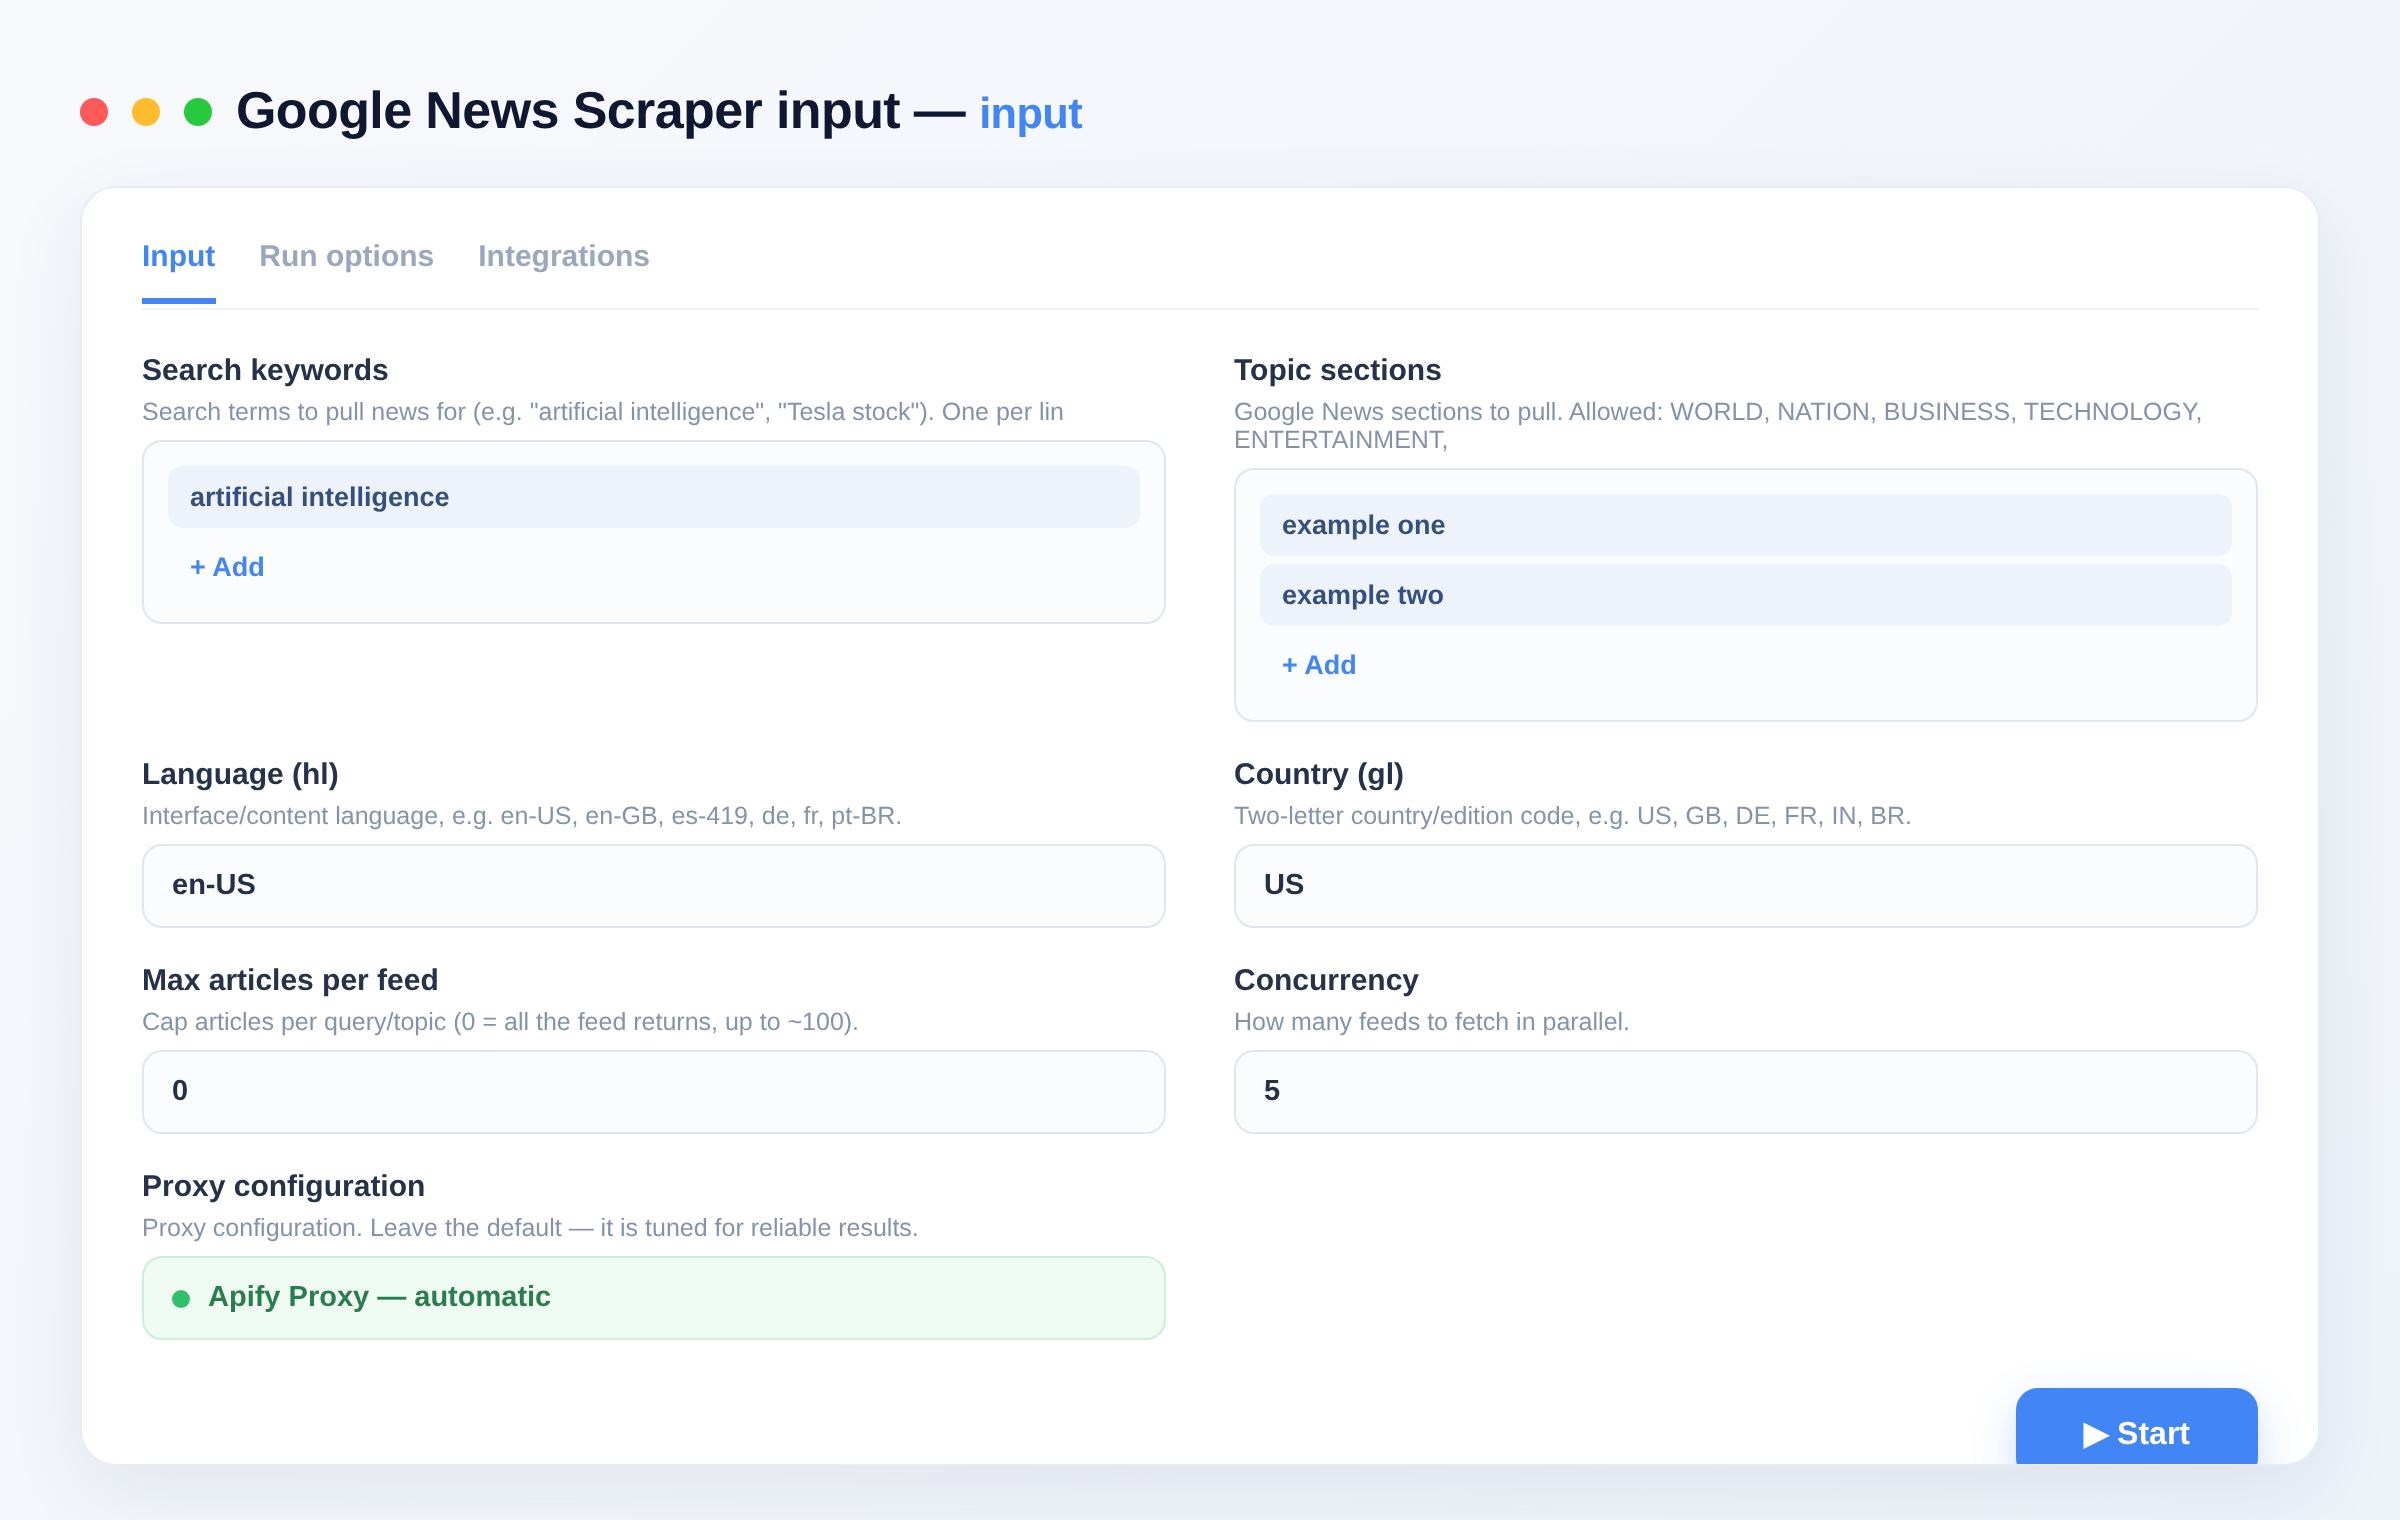
  "queries": ["artificial intelligence", "electric vehicles"],
  "topics": ["TECHNOLOGY", "BUSINESS"],
  "language": "en-US",
  "country": "US",
  "maxItemsPerFeed": 0
}
- queries — search terms, one per line.
- topics — sections:
WORLD, NATION, BUSINESS, TECHNOLOGY, ENTERTAINMENT, SPORTS, SCIENCE, HEALTH. - language (
hl) / country (gl) — the Google News edition, e.g.en-GB/GB,de/DE. - maxItemsPerFeed — cap per feed (0 = all, ~100).
- maxConcurrency — feeds fetched in parallel.
- proxyConfiguration — optional; only if you hit rate limits.
Output (one row per article)
{
  "query": "artificial intelligence",
  "title": "The Case for Nationalizing Artificial Intelligence",
  "source": "Jacobin",
  "link": "https://news.google.com/rss/articles/CBMi...",
  "publishedAt": "Thu, 09 Jul 2026 14:47:17 GMT",
  "snippet": "…",
  "language": "en-US",
  "country": "US"
}
Output schema
| Field | Type | Description |
|---|---|---|
query |
string | Search term the article was found under (empty for topic feeds). |
topic |
string | Topic section the article came from (empty for keyword queries). |
title |
string | Clean headline with the trailing " - Source" removed. |
source |
string | Publisher name (e.g. Reuters, BBC). |
link |
string (URL) | Google News article link; opens the publisher's page. |
publishedAt |
string | Publish time in RFC-822 format. |
guid |
string | Unique identifier for the article within the feed. |
snippet |
string | Short text snippet when the feed provides one. |
language |
string | Language edition used (hl), e.g. en-US. |
country |
string | Country edition used (gl), e.g. US. |
Use cases
- Media monitoring — track a brand, product or executive across every publisher.
- Competitor tracking — watch rivals' announcements and coverage in near real time.
- PR reporting — measure share of voice and pickup for a campaign.
- Research datasets — build a labelled corpus of headlines by topic and edition.
- News alerting — trigger downstream workflows whenever new matching articles appear.
FAQ
Do I need an account or API key? No. The Actor pulls from Google News's public RSS feeds, so it needs no login, API key, or Google account.
How many articles can I get per run?
Each individual Google News feed returns up to ~100 of the most relevant recent items. Combine several queries, topics, and country editions to widen coverage; maxItemsPerFeed caps how many are kept per feed (0 = all).
Is scraping Google News legal?
The Actor collects only publicly available headline metadata (title, source, publish time, link, snippet). Use it responsibly and in line with Google's terms; the link opens the original publisher's page.
What's the output format? A JSON dataset with one row per article, de-duplicated across overlapping queries and topics within a run. Export as JSON, CSV, or Excel from the Apify Console or API.
Can I filter or limit results?
Yes. Scope results with queries, topics (sections like TECHNOLOGY or BUSINESS), language/country editions, and maxItemsPerFeed.
Can I connect this Actor to other apps? The Google News Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Round out your media-monitoring stack with:
- Reddit Scraper — posts, comments, users, and subreddits without login.
- Telegram Channel Scraper — public posts from Telegram channels, no login.
- Hacker News Scraper — stories, comments, and users from Hacker News.
- Website Content Crawler — crawl article pages into clean text for analysis or RAG.
Notes
Each Google News feed returns up to ~100 of the most relevant recent items. Use
several keywords/topics (and country editions) for broader coverage. link is the
Google News article link (opens the publisher's page). Only publicly available
headline data is collected.
Input
| Field | Type | Description |
|---|---|---|
queriesSearch keywords | array | Search terms to pull news for (e.g. "artificial intelligence", "Tesla stock"). One per line. |
topicsTopic sections | array | Google News sections to pull. Allowed: WORLD, NATION, BUSINESS, TECHNOLOGY, ENTERTAINMENT, SPORTS, SCIENCE, HEALTH. |
languageLanguage (hl) | string | Interface/content language, e.g. en-US, en-GB, es-419, de, fr, pt-BR. Default: "en-US" |
countryCountry (gl) | string | Two-letter country/edition code, e.g. US, GB, DE, FR, IN, BR. Default: "US" |
maxItemsPerFeedMax articles per feed | integer | Cap articles per query/topic (0 = all the feed returns, up to ~100). Default: 0 |
maxConcurrencyConcurrency | integer | How many feeds to fetch in parallel. Default: 5 |
proxyConfigurationProxy configuration | object | Proxy configuration. Leave the default — it is tuned for reliable results. Default: {"useApifyProxy": false} |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~google-news-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "queries": [
    "artificial intelligence"
  ],
  "topics": []
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/google-news-scraper").call(run_input={
"queries": [
"artificial intelligence"
],
"topics": []
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/google-news-scraper').call({
"queries": [
"artificial intelligence"
],
"topics": []
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Article scraped One Google News article with headline, source, publish time, link and snippet | $0.0043 | $0.0021 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
North Data Scraper
Look up European companies on North Data: legal name, former names, register number, address, founding date, LEI, business purpose, managing directors and officers, and recent register publications. Germany, UK, France, Austria and 20+ countries. Bulk lookups.
2,467 runs · 5 users · $0.004 / company
Website Content Crawler
Extract clean, readable content from any list of websites: page title, meta description, headings, main body text, word count and link/image counts. Optional same-domain crawl. Bulk-ready. Great for LLM/RAG ingestion, content audits and research.
206 runs · 20 users · $0.0024 / page scraped
SpyFu Domain Scraper
Bulk SEO and PPC reports for any domain from SpyFu: organic keywords, monthly SEO clicks and value, Google Ads budget, paid keywords, top keywords, competitors, top countries and monthly history. Competitor research for agencies. Export CSV/JSON.
185 runs · 7 users · $0.008 / domain report
Trustpilot Reviews Scraper
Scrape Trustpilot reviews and company ratings by company domain or Trustpilot URL: star rating, title, text, reviewer name & country, verification, date, company reply, plus company TrustScore and total reviews.
146 runs · 4 users · $0.0006 / review scraped
ACRA Singapore Company Registry Scraper
Search and export Singapore's full ACRA corporate registry: UEN, entity name, status, incorporation date, address, SSIC industry codes, officers, former names and audit firms. Filter by name, status, entity type or industry. Public open data, no setup.
138 runs · 10 users · $0.01 / company scraped
Wayback Machine Scraper
List every Internet Archive (Wayback Machine) snapshot of a URL or whole domain: timestamp, snapshot URL, status code, MIME type and content digest. Filter by date, status and dedupe. For SEO, OSINT and historical research. No setup.
135 runs · 15 users · $0.002 / snapshot scrapedSend the site and the fields. We build it and you get it first.