YouTube Scraper
hipersoft/youtube-scraper
All-in-one YouTube API: get video metadata, full transcripts, comments with replies, channel data, and search results in a single call. No setup, fast and cheap.
Total users
52Monthly users
16Total runs
350Per video scraped
$0.0032Last rebuilt
Oct 26, 2026Overview
Scrape YouTube at scale into clean JSON, CSV, Excel or XML. This YouTube scraper extracts video metadata, full transcripts, comments with reply threads, channel profiles, playlists and search results — all from one Actor, with no API key and no quotas. A faster, lower-cost alternative to the official YouTube Data API.
Most YouTube scrapers make you run three or four separate tools — one for metadata, one for transcripts, one for comments — and bill you for each. This one does it all in a single run.
What does the YouTube Scraper do?
The YouTube Scraper crawls and extracts public YouTube data by video URL, playlist URL, channel URL or search term. Point it at a video, a Shorts link, a playlist, a @handle or channel, or a search query, and it returns structured data points — views, likes, duration, publish date, subscriber counts, transcripts, comments and more — ready for analytics, datasets, LLM pipelines or lead generation.
What data can you scrape from YouTube?
| Group | Fields |
|---|---|
| 🎥 Video | id, title, description, description links, view count, like count, duration (+ seconds), publish date, keywords/tags, thumbnails, is-monetized, comments-turned-off, is-Short, is-Live, family-safe flag, category |
| 📝 Transcript | full text, timestamped segments (start + duration), ready-to-use SRT subtitles, language, auto-generated flag, list of available languages |
| 💬 Comments | comment text, author handle, like count, published time, reply threads, creator/verified flags, reply count |
| 📺 Channel | name, handle, channel ID, subscriber count, total views, video count, country, join date, avatar, description, external & social links |
| 🔍 Search | every matching video with full metadata, ranked by YouTube relevance |
Use cases
- Feed transcripts to an LLM — summaries, RAG knowledge bases, content repurposing and translation at scale.
- Comment & sentiment analysis — mine top comments and reply threads for any video or channel.
- Influencer & lead generation — pull subscriber counts, contact emails and social links from channel profiles.
- Competitor & trend research — track a niche via search results, top videos and channel catalogs.
- Brand & content monitoring — watch mentions, engagement and new uploads over time.
- Build a video dataset — views, likes, duration and metadata for thousands of videos.
- Content strategy — find high-performing formats, keywords and titles in your space.
- Academic & market research — study engagement, topics and audience signals from public data.
How to scrape YouTube data
- Click Try for free / Start to open the YouTube Scraper.
- Paste video URLs, playlist URLs, a search query, or channel URLs (bare video IDs and
@handlesalso work). - Toggle the add-ons you want — transcripts, comments, and channel enrichment — and set limits.
- Click Run.
- Download the results as JSON, CSV, Excel or XML, or pull them from the API.
Input
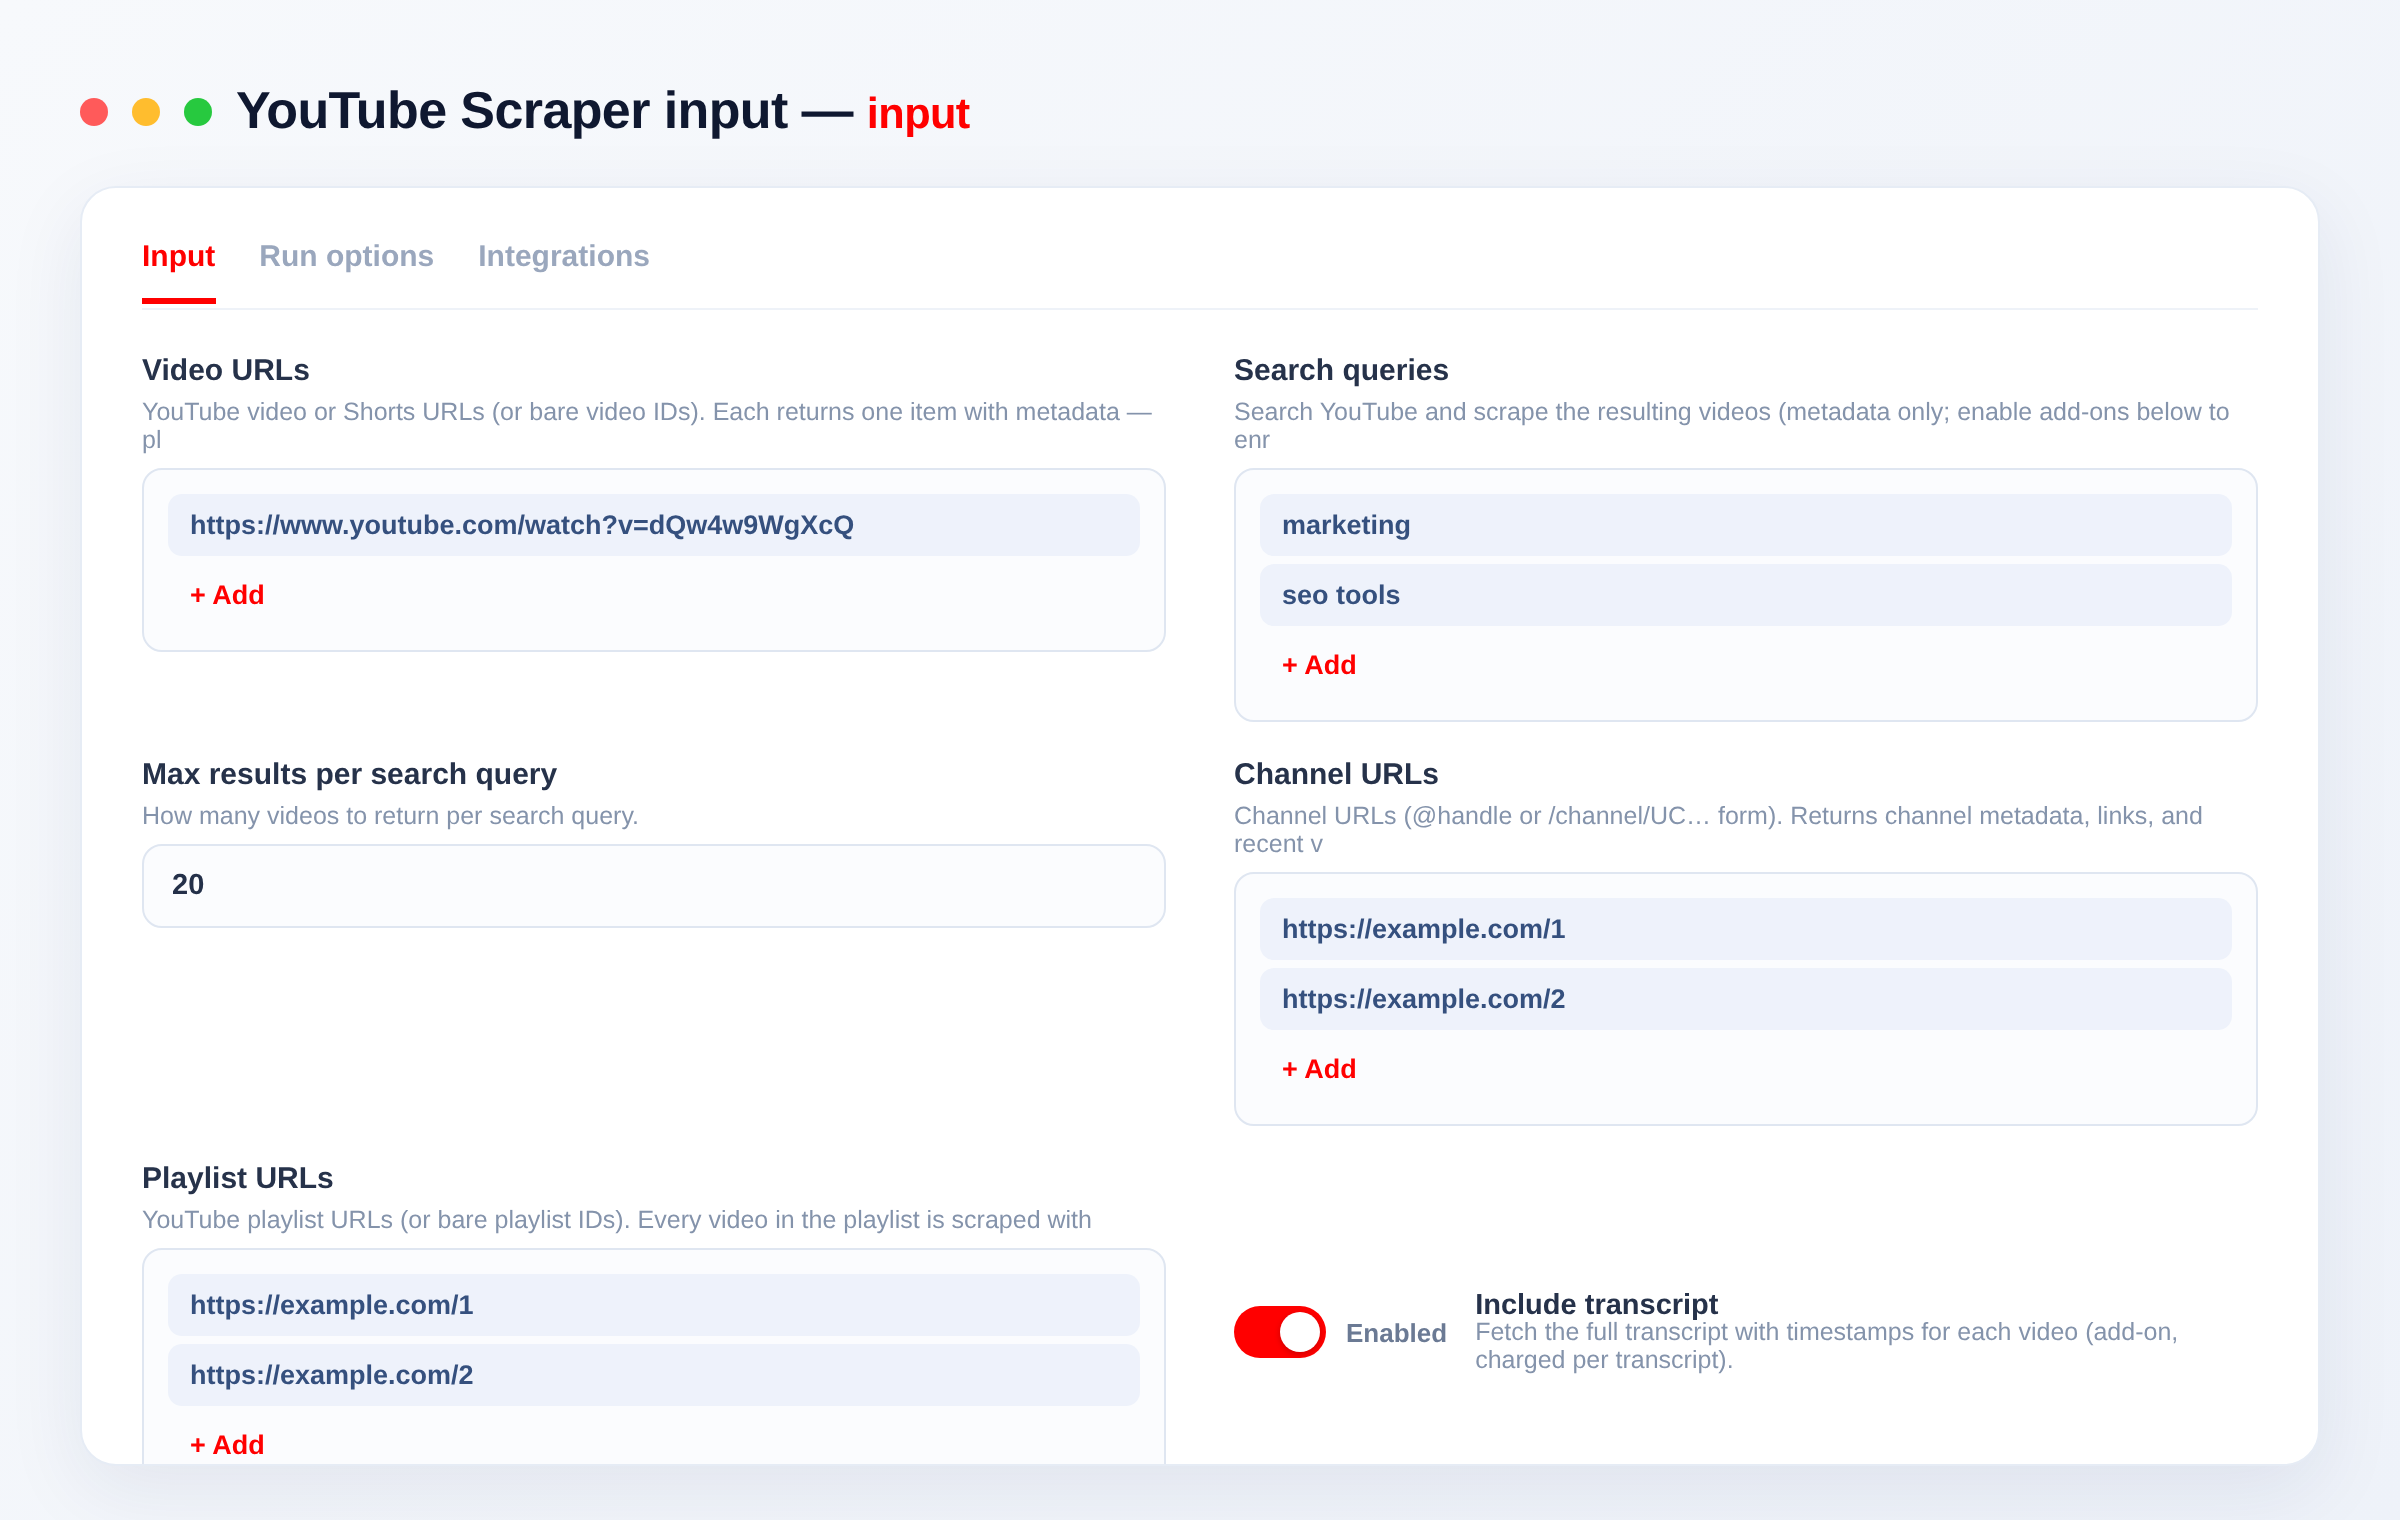
Provide any mix of video URLs, search queries and channel URLs, then toggle the add-ons.
{
  "videoUrls": ["https://www.youtube.com/watch?v=aircAruvnKk"],
  "playlistUrls": ["https://www.youtube.com/playlist?list=PLZHQObOWTQDNU6R1_67000Dx_ZCJB-3pi"],
  "searchQueries": ["machine learning tutorial"],
  "maxResultsPerQuery": 20,
  "channelUrls": ["https://www.youtube.com/@3blue1brown"],
  "includeTranscript": true,
  "transcriptLanguage": "en",
  "includeComments": true,
  "maxComments": 100,
  "includeChannel": true
}
| Field | Type | Description |
|---|---|---|
videoUrls |
array | YouTube video or Shorts URLs (or bare 11-char video IDs). |
playlistUrls |
array | Playlist URLs (or IDs) — every video in the playlist is scraped with full metadata. |
searchQueries |
array | Search terms; each result is scraped as a video. |
maxResultsPerQuery |
integer | Videos returned per search query, and per playlist (default 20). |
channelUrls |
array | Channel URLs — @handle or /channel/UC…. |
includeTranscript |
boolean | Attach the full transcript (text, segments, SRT) to each video. |
transcriptLanguage |
string | Preferred transcript language code, e.g. en, es, de. |
includeComments |
boolean | Attach comments with reply threads to each video. |
maxComments |
integer | Max comments per video, including replies. |
includeChannel |
boolean | Attach the uploader's channel profile to each video. |
Scrape YouTube by URL or search term
Pass exact videoUrls when you know the videos, or searchQueries to discover them — mix both in one run.
Scrape YouTube transcripts and subtitles
Enable includeTranscript for the full transcript, timestamped segments and downloadable SRT subtitles, with transcriptLanguage selection and an auto-generated fallback.
Scrape YouTube comments
Enable includeComments to pull top comments including reply threads, each with author, like count and verified/creator flags.
Output
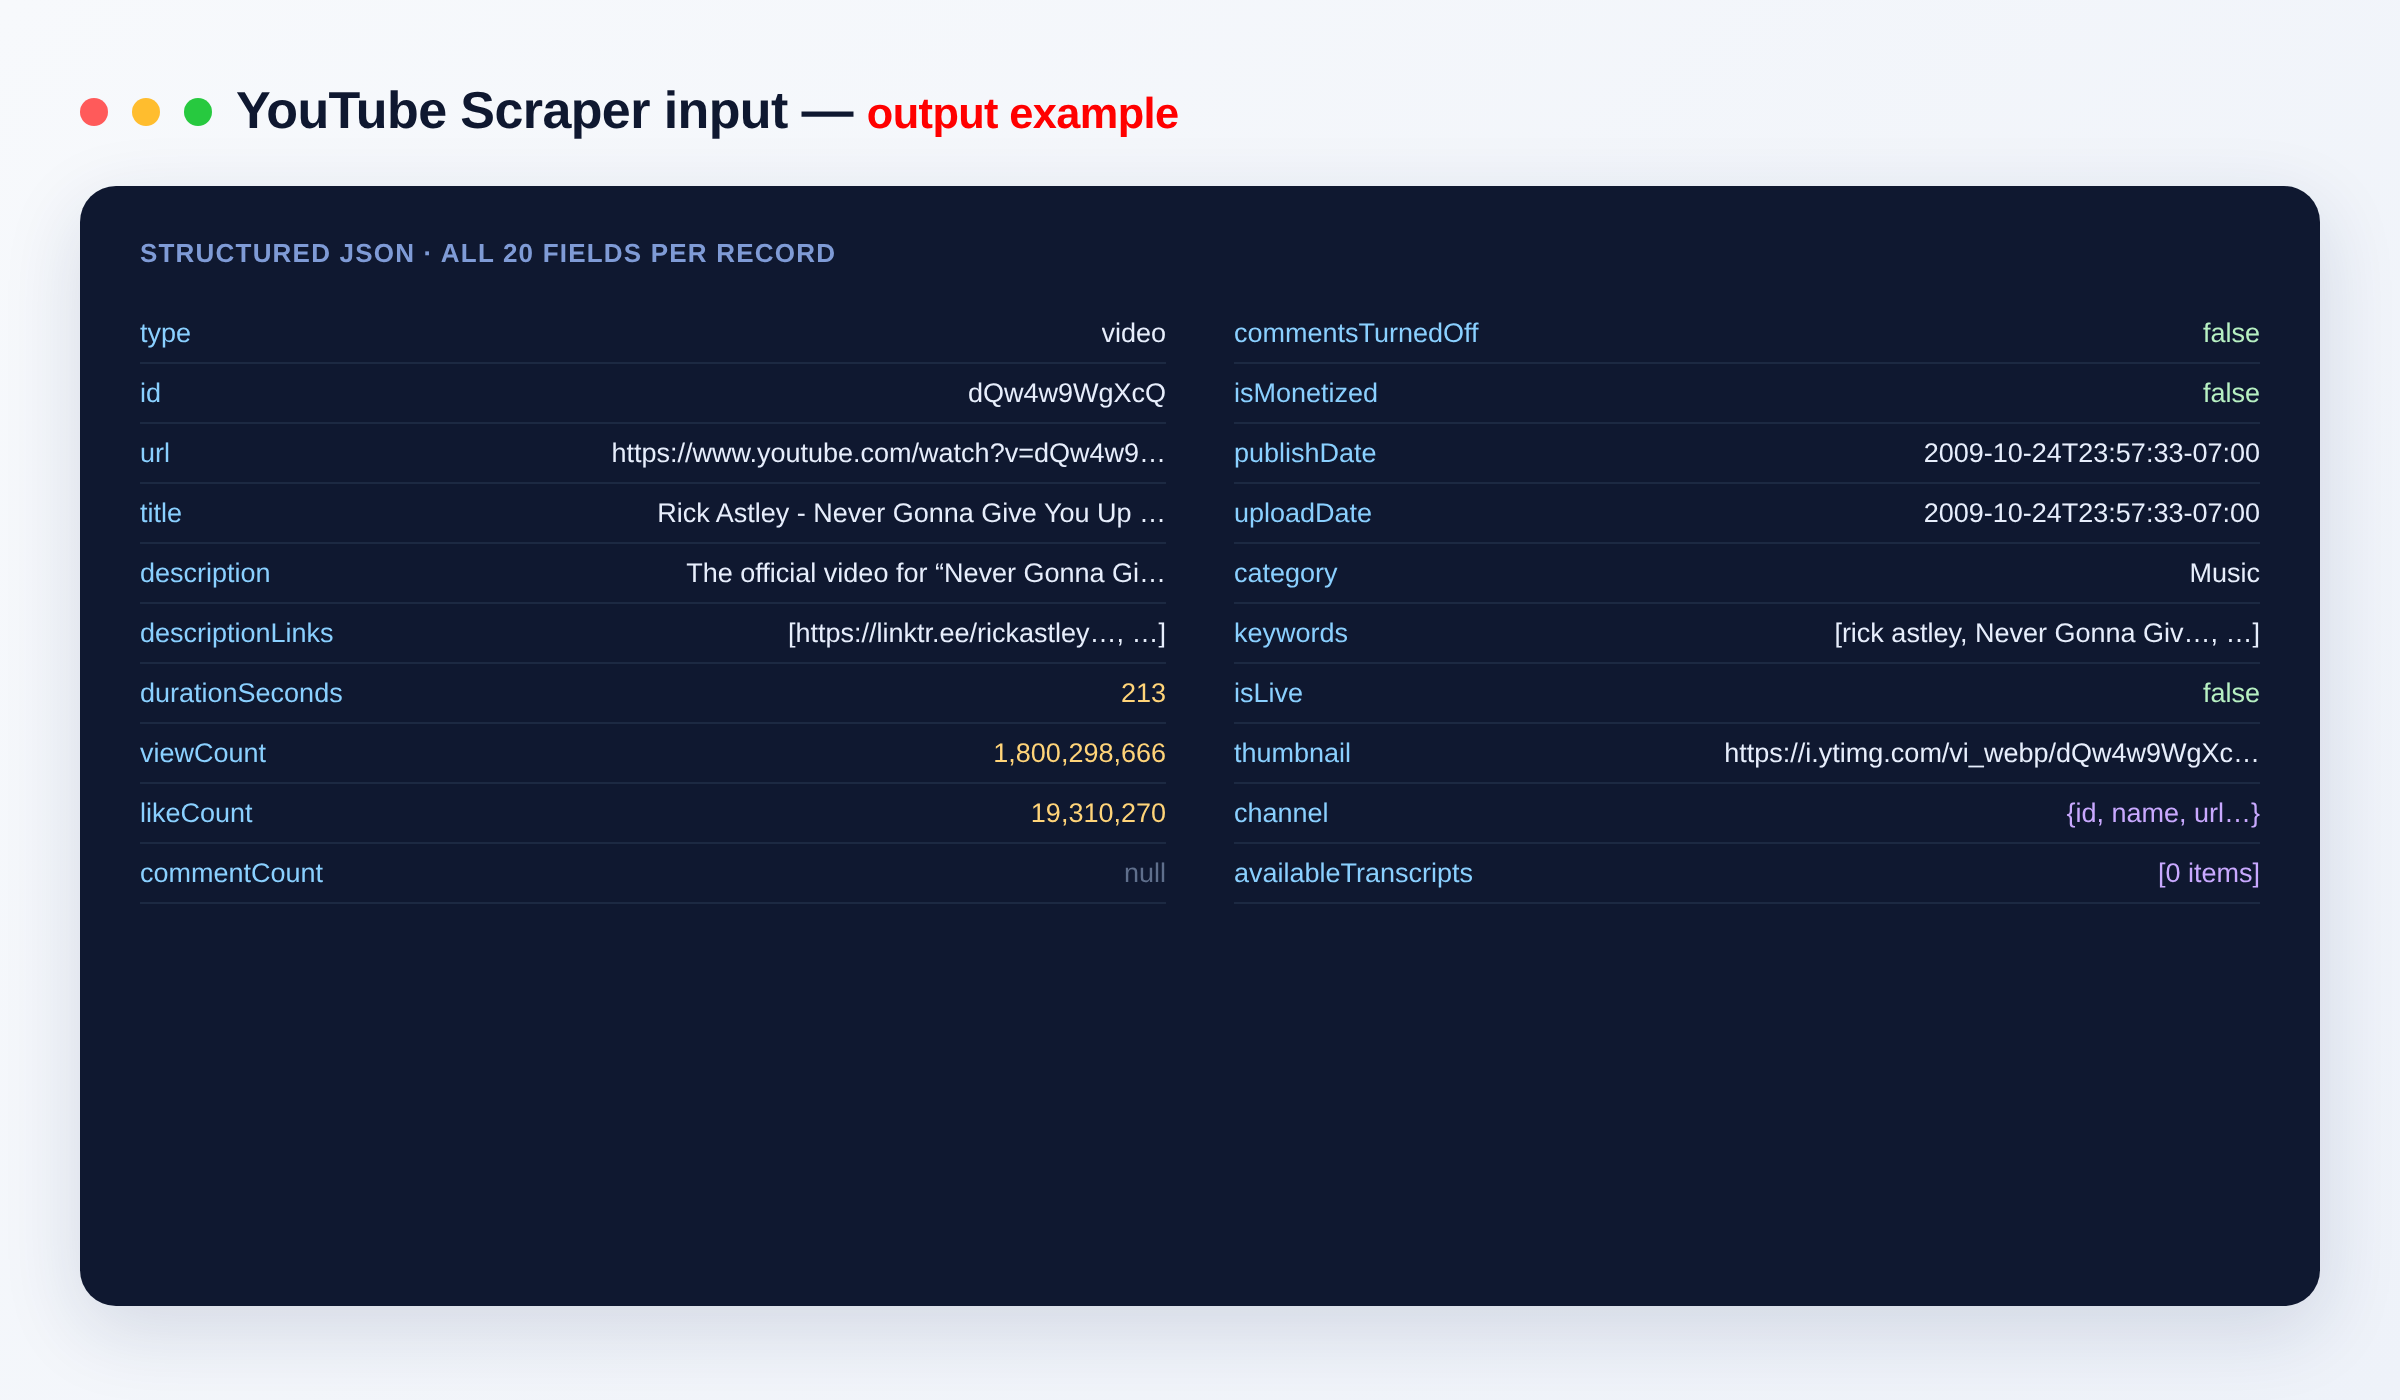
Each video is one dataset item:
{
  "type": "video",
  "id": "aircAruvnKk",
  "title": "But what is a neural network? | Deep learning chapter 1",
  "viewCount": 23621207,
  "likeCount": 551760,
  "commentCount": 8300,
  "durationSeconds": 1120,
  "publishDate": "2017-10-05T08:11:25-07:00",
  "descriptionLinks": ["https://www.patreon.com/3blue1brown", "https://3b1b.co/nn1-thanks"],
  "isMonetized": true,
  "commentsTurnedOff": false,
  "keywords": ["neural network", "deep learning"],
  "channel": { "name": "3Blue1Brown", "handle": "@3blue1brown", "subscriberCount": 8460000, "links": ["…"] },
  "transcript": {
    "available": true,
    "language": "en",
    "segments": [ { "start": 4.2, "duration": 3.1, "text": "This is a 3." } ],
    "fullText": "This is a 3. It's sloppily written …",
    "srt": "1\n00:00:04,200 --> 00:00:07,300\nThis is a 3.\n…"
  },
  "comments": [
    { "author": "@user", "text": "Great video!", "likeCount": 13000, "replies": ["…"] }
  ]
}
Channels and standalone search results are emitted as type: "channel" and type: "search-result" items with their own fields.
Output schema (video items)
| Field | Type | Description |
|---|---|---|
type |
string | Item type — video, channel or search-result. |
id |
string | YouTube video ID. |
url |
string (URL) | Canonical watch URL of the video. |
title |
string | Video title. |
description |
string | Full video description text. |
descriptionLinks |
array | Links found in the description. |
durationSeconds |
integer | Video length in seconds. |
viewCount |
integer | Total view count. |
likeCount |
integer | Total like count. |
commentCount |
string | Number of comments (as shown by YouTube). |
commentsTurnedOff |
boolean | Whether comments are disabled on the video. |
isMonetized |
boolean | Whether the video appears to be monetized. |
publishDate |
string (ISO date) | When the video was published. |
uploadDate |
string (ISO date) | When the video was uploaded. |
category |
string | YouTube category, e.g. Education. |
keywords |
array | Video tags/keywords. |
isLive |
boolean | Whether the item is a live stream. |
thumbnail |
string (URL) | Thumbnail image URL. |
channel |
object | Channel info — name, handle, subscriberCount and links. |
availableTranscripts |
array | Transcript languages available for the video. |
When enabled, video items also include a transcript object (segments, fullText, srt) and a comments array (author, text, likeCount, replies).
Need YouTube comments, transcripts or other platforms?
This Actor already bundles comments, transcripts and channel data — but if you're building a wider dataset, pair it with our other scrapers:
- TVmaze Scraper — TV shows, episodes and cast with IMDb IDs and ratings.
- Spotify Scraper — tracks, artists, albums and playlists.
- SoundCloud Scraper — tracks, artists and play counts.
- Twitch Scraper — streams, channels and viewer stats.
- Apple Podcasts Scraper — podcast shows and episodes.
FAQ
Do I need a YouTube API key? No. The YouTube Scraper needs no official API key and has no quotas — just add your inputs and run.
How many videos can I scrape per run?
As many as you like. Set maxResultsPerQuery per search, and pass any mix of video URLs, search queries and channel URLs in one run to scale up to thousands.
Can I scrape YouTube transcripts and subtitles?
Yes — enable includeTranscript for the full text, timestamped segments and ready-to-use SRT subtitles, with language selection.
Can I scrape YouTube comments?
Yes — enable includeComments for top comments including reply threads, with author, like count and verified flags.
Can I scrape a whole YouTube playlist?
Yes — pass playlist URLs in playlistUrls and every video in the playlist is scraped with full metadata (and transcripts/comments if enabled). Use maxResultsPerQuery to cap how many videos per playlist.
Can I download videos or audio? No. This Actor extracts metadata, transcripts, comments and channel data — text and numbers only, not media files.
What export formats are supported? JSON, CSV, Excel and XML, plus webhooks and the Apify API.
Can I automate or integrate the YouTube Scraper? Yes. The YouTube Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes — get a notification, or kick off another process such as loading your data downstream.
Is scraping YouTube legal? The Actor collects only public data. You are responsible for how you use it and for complying with YouTube's terms and applicable laws.
Notes
Original clean-room implementation. Collects only public YouTube data; you are responsible for how you use the data and for complying with YouTube's terms. This is an independent tool and is not affiliated with or endorsed by YouTube.
Input
| Field | Type | Description |
|---|---|---|
videoUrlsVideo URLs | array | YouTube video or Shorts URLs (or bare video IDs). Each returns one item with metadata — plus transcript, comments, and channel info if enabled below. |
searchQueriesSearch queries | array | Search YouTube and scrape the resulting videos (metadata only; enable add-ons below to enrich each hit). |
maxResultsPerQueryMax results per search query | integer | How many videos to return per search query. Default: 20 |
channelUrlsChannel URLs | array | Channel URLs (@handle or /channel/UC… form). Returns channel metadata, links, and recent videos. |
playlistUrlsPlaylist URLs | array | YouTube playlist URLs (or bare playlist IDs). Every video in the playlist is scraped with full metadata — plus transcript/comments/channel if enabled. Capped by 'Max results per search query'. |
includeTranscriptInclude transcript | boolean | Fetch the full transcript with timestamps for each video (add-on, charged per transcript). Default: true |
transcriptLanguageTranscript language | string | Preferred transcript language code (e.g. en, es, de). Falls back to the first available track, including auto-generated. Default: "en" |
includeCommentsInclude comments | boolean | Fetch top comments including reply threads for each video (add-on, charged per comment). Default: false |
maxCommentsMax comments per video | integer | Upper limit of comments (incl. replies) per video. Default: 100 |
includeChannelInclude channel details | boolean | Fetch the uploader channel's profile (subscribers, links, description) for each video (add-on, charged per channel). Default: false |
proxyConfigurationProxy configuration | object | Proxy configuration. Leave the default — it is tuned for reliable results. Default: {"useApifyProxy": true, "apifyProxyGroups": ["RESIDENTIAL"]} |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~youtube-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "videoUrls": [
    "https://www.youtube.com/watch?v=dQw4w9WgXcQ"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/youtube-scraper").call(run_input={
"videoUrls": [
"https://www.youtube.com/watch?v=dQw4w9WgXcQ"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/youtube-scraper').call({
"videoUrls": [
"https://www.youtube.com/watch?v=dQw4w9WgXcQ"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Video scraped Metadata for one video (title, views, likes, etc.) | $0.0032 | $0.0032 |
| Transcript scraped Full transcript with timestamps for one video | $0.006 | $0.006 |
| Comment scraped One comment or reply extracted from a video | $0.0016 | $0.0016 |
| Channel scraped One channel profile with links and recent videos | $0.004 | $0.004 |
| Search result One video returned from a search query | $0.002 | $0.002 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Website Contact Scraper
Extract business emails, phone numbers and social media profiles from any list of websites. De-obfuscates emails, reads Organization schema, and optionally crawls contact/about pages. Bulk-ready.
1,576 runs · 69 users · $0.0024 / website scraped
Threads Downloader
Download Threads photos, videos and carousel posts by URL. Paste threads.net or threads.com links and get ready-to-use download links plus direct media URLs, a thumbnail, media type and count — one row per URL as JSON, CSV or Excel. Cheap, bulk, built for creators and n8n.
799 runs · 4 users · $0.003 / post downloaded
TikTok Video Downloader
Download TikTok videos without watermark in bulk. Paste video or photo-slideshow URLs and get a clean HD MP4 download link plus full metadata: caption, author, play/like/comment/share counts, sound and cover — one row per post as JSON, CSV or Excel. For creators, research and n8n.
678 runs · 9 users · $0.0035 / video downloaded
Reddit Scraper
Scrape Reddit posts and comments by subreddit, keyword, author or thread URL. Get titles, self-text, scores, upvote ratio, comment counts, comment trees and permalinks — one clean row per post or comment. Export as JSON, CSV or Excel.
568 runs · 15 users · $0.0034 / post scraped
Spotify Scraper
Search Spotify and scrape public metadata for tracks, artists, albums and playlists: names, artists, popularity, followers, genres, release dates, duration, ISRC, preview URL and more. No Spotify login or API key required. For music research, catalogs and analytics.
478 runs · 9 users · $0.0034 / item scraped
Reddit Video, Image & GIF Downloader
Download Reddit videos, images and GIFs by post URL. Paste reddit.com or redd.it links and get ready-to-use download links — videos as a single playable MP4 with audio, images and galleries as direct links — one row per URL as JSON, CSV or Excel. Cheap, bulk, built for creators and n8n.
453 runs · 16 users · $0.003 / item scrapedSend the site and the fields. We build it and you get it first.