Letterboxd Scraper
hipersoft/letterboxd-scraper
Scrape Letterboxd films with ratings, rating counts, genres, director, cast, runtime and synopsis. Feed it film pages, a user's films/watchlist/diary, any list URL, or browse pages. For film data, recommendations and research.
Total users
7Monthly users
1Total runs
139Per film scraped
$0.0042Last rebuilt
Oct 26, 2026Overview
Extract rich film data from Letterboxd — average rating, number of ratings, watches, likes, fans, genres, directors, cast, runtime, synopsis, countries, languages, studios, themes, streaming availability and poster — into clean JSON, CSV or Excel. Point it at individual films, a user's watchlist or diary, any list, a director or actor, a genre, a browse page, or just a search term. Fast and reliable.
Great for film datasets, recommendation engines, ranking & analytics, watchlist backups and research.
What you can scrape
- 🎬 Single films —
letterboxd.com/film/parasite-2019/(or a bare slug likeparasite-2019) - 👤 A user's watchlist or diary —
letterboxd.com/USERNAME/watchlist/,.../films/diary/ - 📋 Any list —
letterboxd.com/USERNAME/list/LIST-NAME/ - 🎬 A director or actor's films —
letterboxd.com/director/greta-gerwig/,/actor/NAME/ - 🎭 A genre —
letterboxd.com/films/genre/horror/, or the Genre field - 🔥 Browse pages — popular this week, popular all-time, highest rated, newest
- 🔎 Search — pass a title or keyword and get matching films
Give it any mix as Start URLs (plus optional search/genre) and it pulls full metadata for every film.
Example input
{
  "startUrls": [
    "https://letterboxd.com/films/popular/this/week/",
    "https://letterboxd.com/schaffrillas/watchlist/",
    "https://letterboxd.com/film/parasite-2019/"
  ],
  "search": "blade runner",
  "sort": "FilmPopularityThisWeek",
  "maxFilms": 200,
  "includeStatistics": true
}
What you get
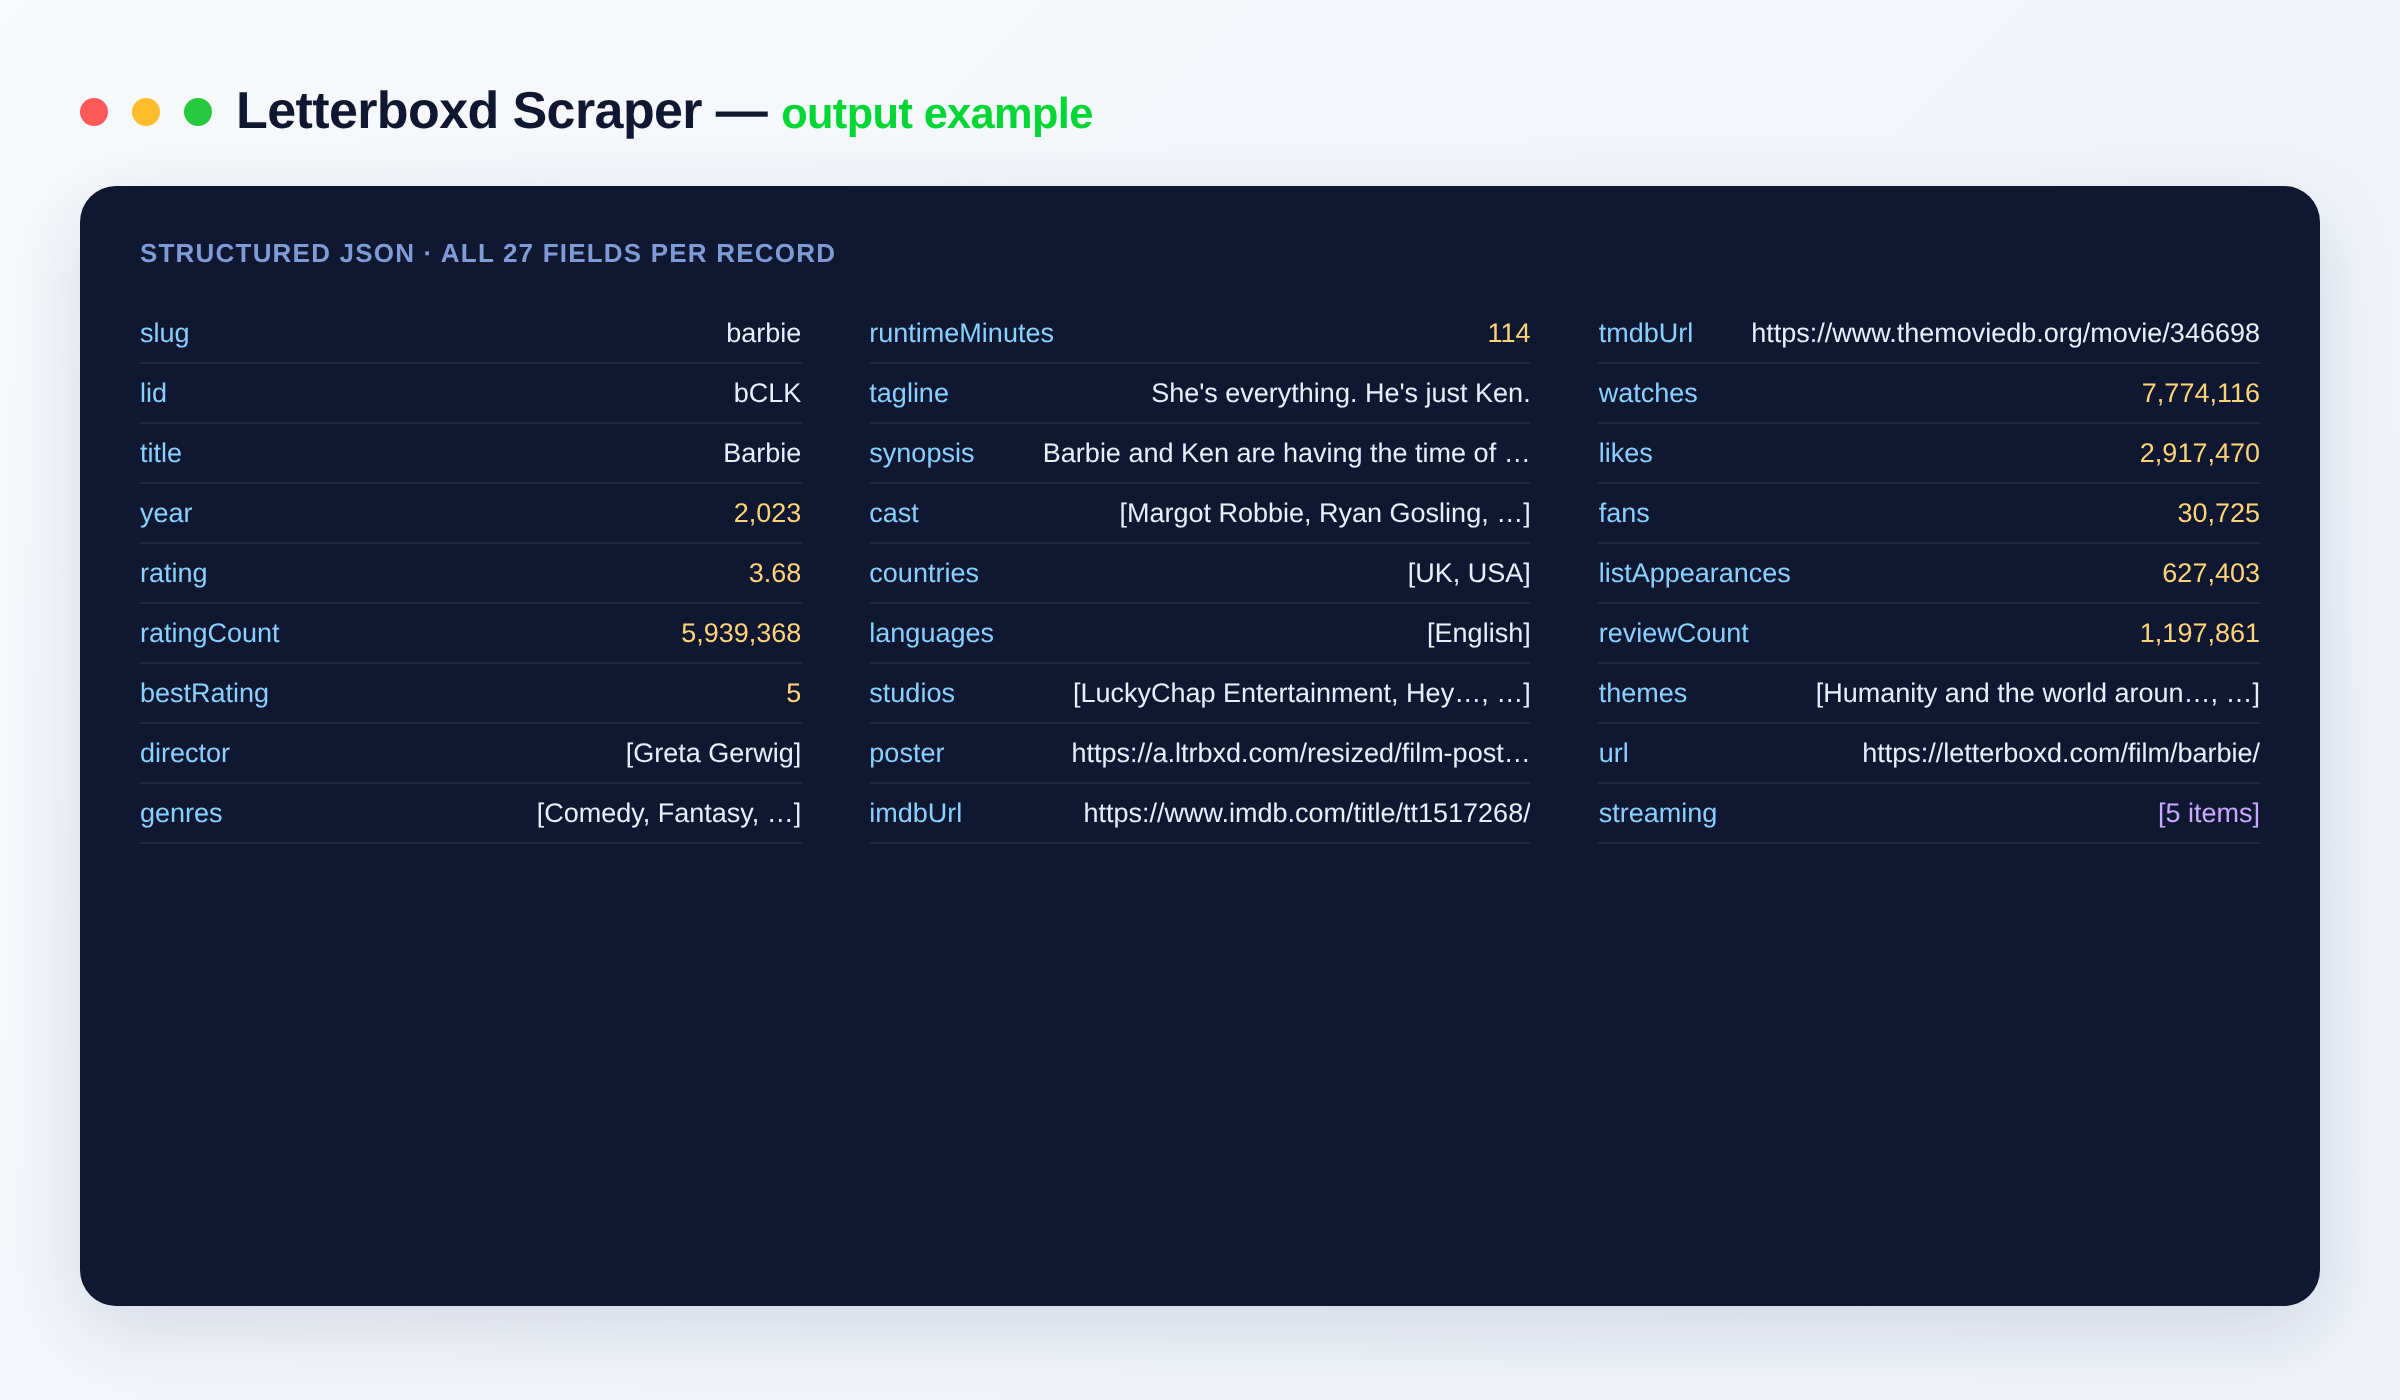
One row per film:
{
  "title": "Parasite",
  "year": 2019,
  "rating": 4.52,
  "ratingCount": 5664177,
  "watches": 8600000,
  "likes": 4200000,
  "fans": 210000,
  "reviewCount": 480000,
  "director": ["Bong Joon Ho"],
  "genres": ["Thriller", "Comedy", "Drama"],
  "runtimeMinutes": 133,
  "cast": ["Song Kang-ho", "Lee Sun-kyun", "Cho Yeo-jeong", "…"],
  "countries": ["South Korea"],
  "languages": ["Korean", "English"],
  "studios": ["Barunson E&A"],
  "themes": ["…"],
  "synopsis": "…",
  "poster": "https://a.ltrbxd.com/resized/film-poster/…jpg",
  "imdbUrl": "https://www.imdb.com/title/tt6751668/",
  "tmdbUrl": "https://www.themoviedb.org/movie/496243",
  "url": "https://letterboxd.com/film/parasite-2019/"
}
Output schema
| Field | Type | Description |
|---|---|---|
slug |
string | Letterboxd film slug (e.g. parasite-2019) |
lid |
string | Letterboxd internal film ID |
title |
string | Film title |
year |
string | Release year |
rating |
string | Average Letterboxd rating (out of 5) |
ratingCount |
integer | Number of ratings |
bestRating |
integer | Maximum possible rating on the scale |
director |
array | Director(s) |
genres |
array | Genre tags |
runtimeMinutes |
string | Runtime in minutes |
tagline |
string | Film tagline |
synopsis |
string | Plot synopsis |
cast |
array | Cast members |
countries |
array | Production countries |
languages |
array | Spoken languages |
studios |
array | Production studios |
poster |
string | Poster image URL |
imdbUrl |
string | Link to the film on IMDb |
tmdbUrl |
string (URL) | Link to the film on TMDB |
watches |
integer | Number of users who logged a watch |
likes |
integer | Number of likes |
fans |
integer | Number of fans |
listAppearances |
integer | Number of lists the film appears on |
reviewCount |
integer | Number of written reviews |
themes |
array | Theme tags |
url |
string (URL) | Link to the film's Letterboxd page |
streaming |
array | Where the film is available to stream/rent/buy (when includeAvailability is on) |
Input fields
| Field | Description |
|---|---|
startUrls |
Film pages, a user's watchlist/ or films/diary/, a list/, a director//actor/ page, a films/genre/ page, or browse/popular pages. Bare film slugs also work. |
search |
Optional free-text film search (title or keyword). |
genre |
Optional genre to browse (e.g. horror, comedy, drama, science fiction, documentary). |
sort |
Sort order for browse/genre pages: popular this week, popular all-time, highest rated, newest, or name. |
maxFilms |
Max films to scrape in total across all inputs (up to 100,000). |
includeStatistics |
Include rating count, watches, likes, fans, review and list counts (on by default). |
includeAvailability |
Include where each film is available to stream/rent/buy (adds a streaming field). |
Use cases
- Build a film dataset — ratings, rating counts, genres and crew for thousands of titles
- Recommendation & ranking — use real Letterboxd ratings, rating counts and popularity as signal
- Watchlist backup — export a user's watchlist to a spreadsheet
- Popularity & rating analysis — scrape a browse page and crunch the numbers
- Enrich your movie app — pull posters, runtime, cast, synopsis and IMDb/TMDB links by title or URL
FAQ
How many films can I scrape?
Set maxFilms up to 100,000. Browse pages and watchlists are paged through automatically.
Can I scrape a specific user's watchlist?
Yes — use their watchlist/ URL as a start URL.
How does billing work? Pay per film scraped — you only pay for the films you actually get.
Do I need any setup? No — just add your inputs and run. Fast and reliable.
Is this only public data? Yes. It returns only publicly available Letterboxd data.
Can I connect this to other tools? The Letterboxd Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JavaScript/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Notes
Original clean-room implementation. Returns only public Letterboxd data; you are responsible for how you use the data and for complying with Letterboxd's terms. This is an independent tool and is not affiliated with or endorsed by Letterboxd.
Input
| Field | Type | Description |
|---|---|---|
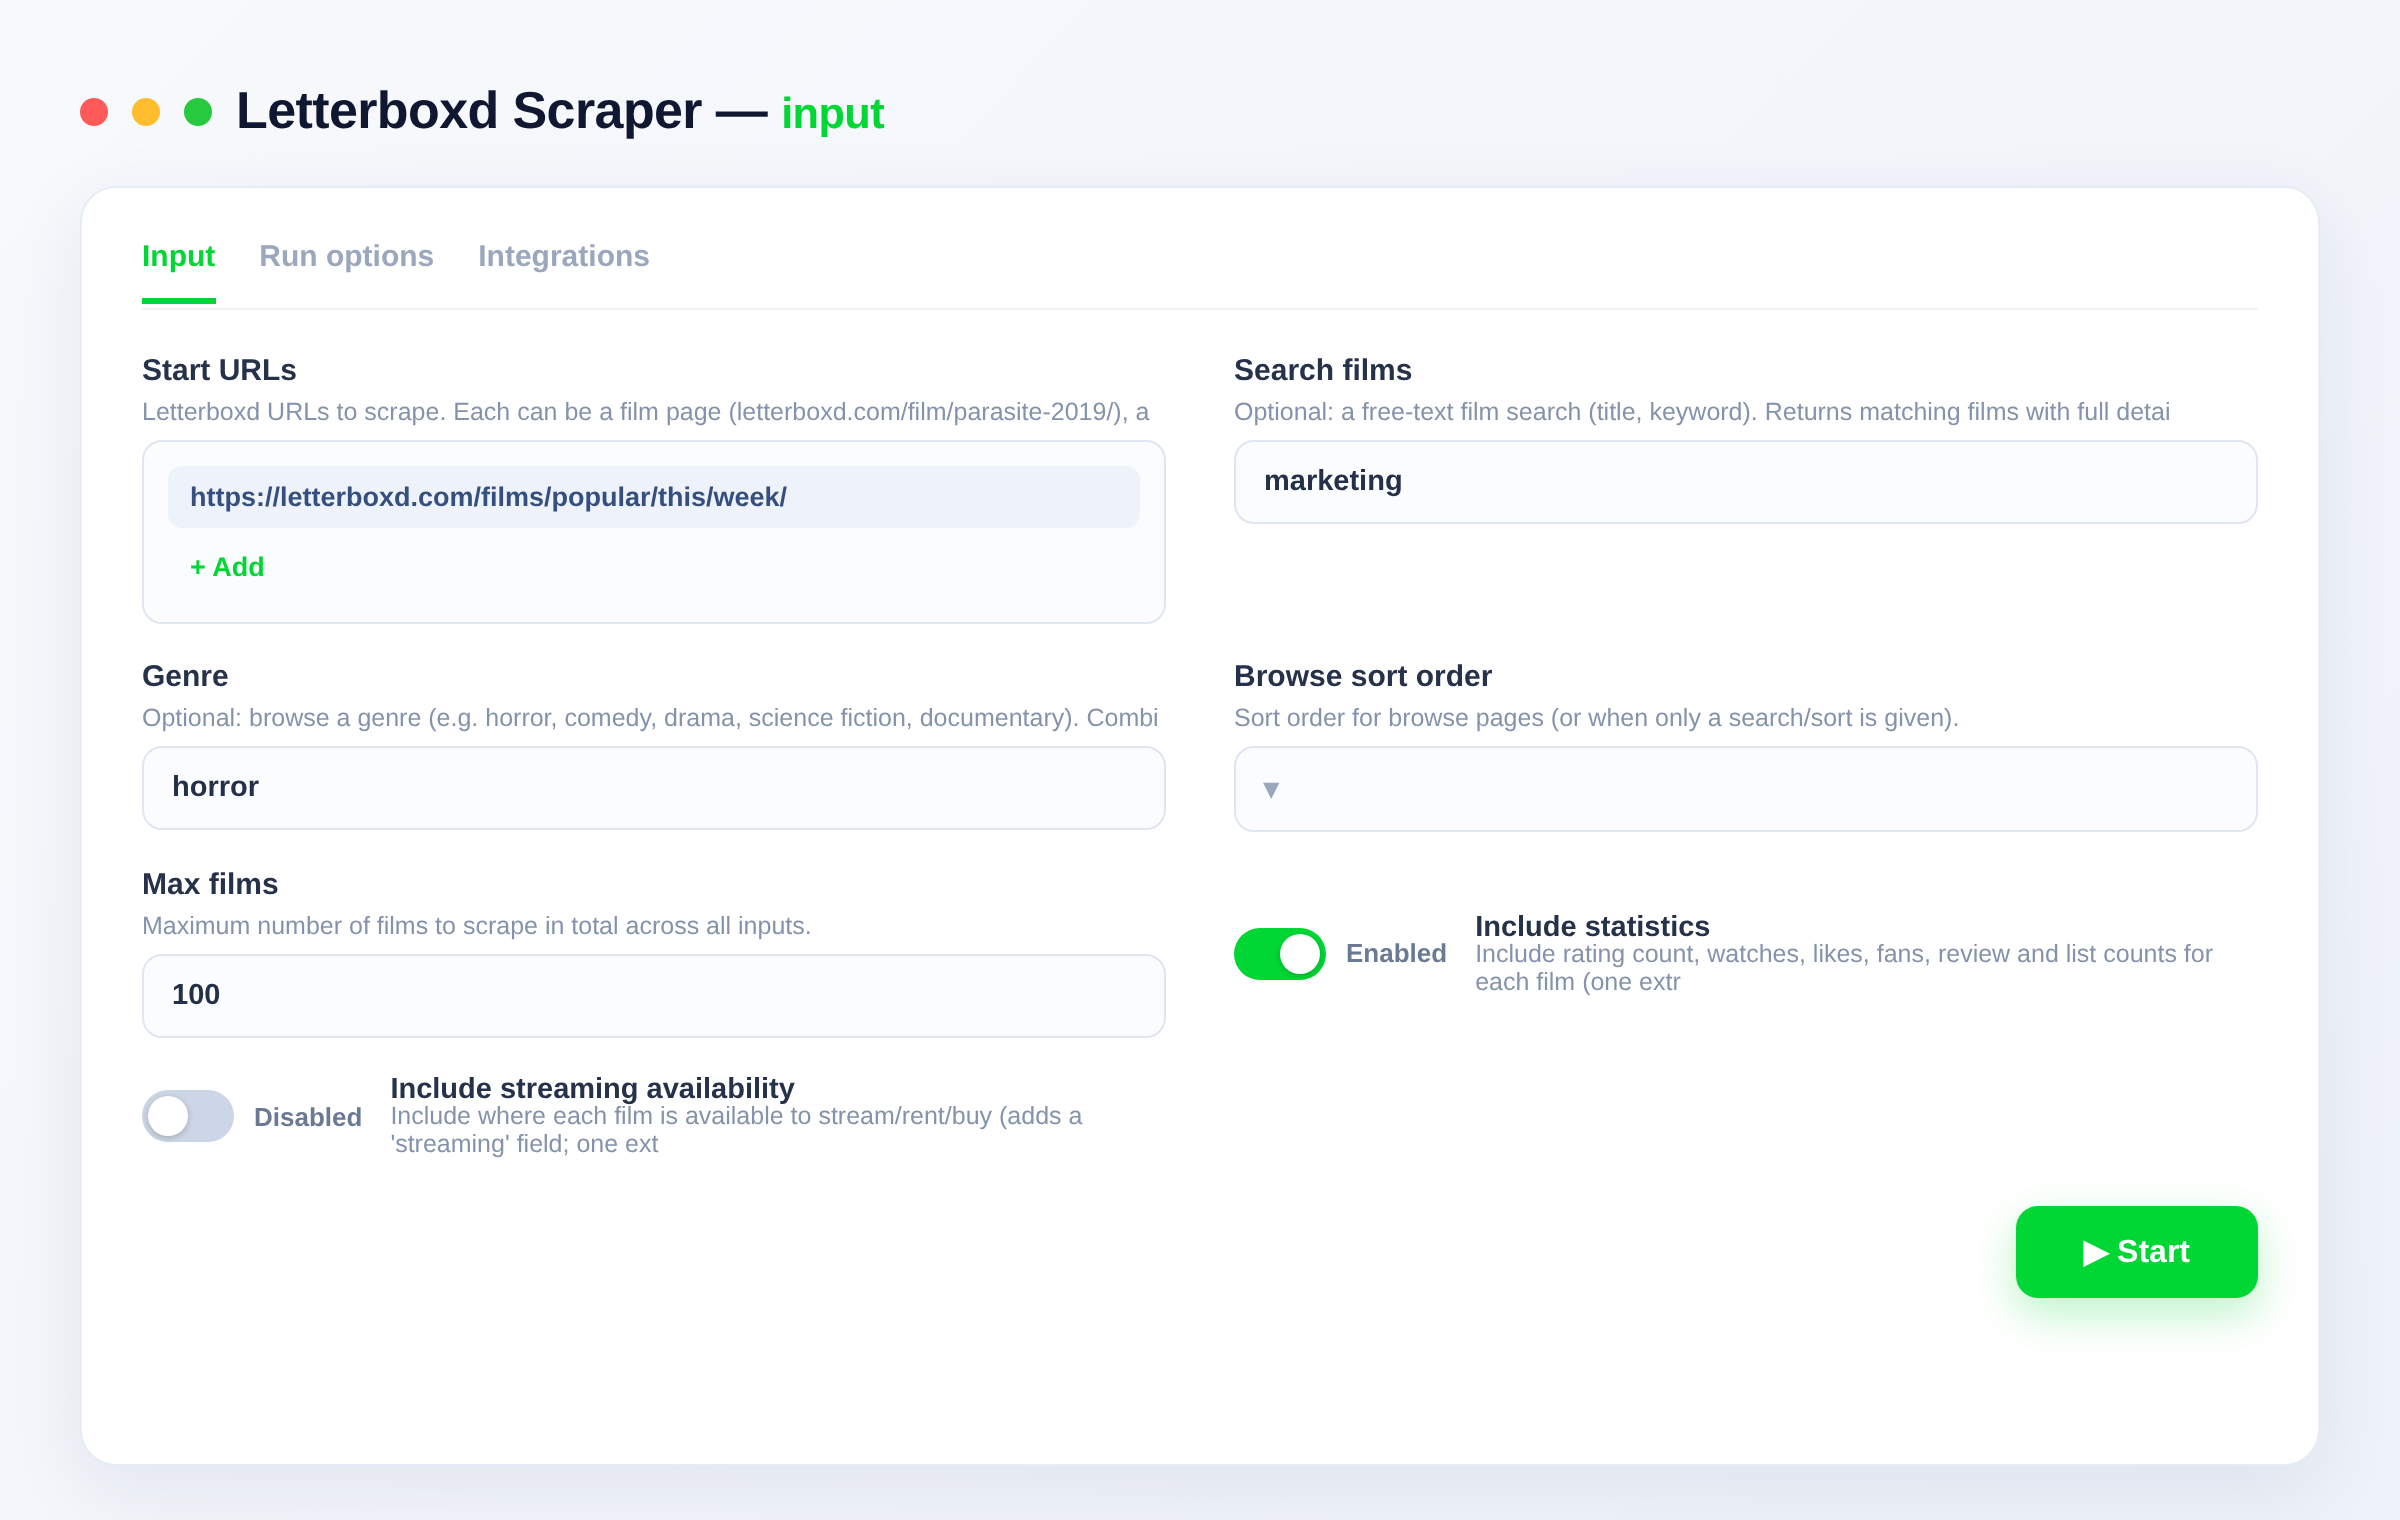
startUrlsStart URLs | array | Letterboxd URLs to scrape. Each can be a film page (letterboxd.com/film/parasite-2019/), a user's watchlist (letterboxd.com/USER/watchlist/) or diary (letterboxd.com/USER/films/diary/), a list (letterboxd.com/USER/list/NAME/), a director/actor page (letterboxd |
searchSearch films | string | Optional: a free-text film search (title, keyword). Returns matching films with full details. |
genreGenre | string | Optional: browse a genre (e.g. horror, comedy, drama, science fiction, documentary). Combined with the sort order below. |
sortBrowse sort order | string · , FilmPopularityThisWeek, FilmPopularity, RatingHighToLow, ReleaseDateLatestFirst, FilmName | Sort order for browse pages (or when only a search/sort is given). |
maxFilmsMax films | integer | Maximum number of films to scrape in total across all inputs. Default: 100 |
includeStatisticsInclude statistics | boolean | Include rating count, watches, likes, fans, review and list counts for each film (one extra lookup per film). Default: true |
includeAvailabilityInclude streaming availability | boolean | Include where each film is available to stream/rent/buy (adds a 'streaming' field; one extra lookup per film). Default: false |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~letterboxd-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "startUrls": [
    "https://letterboxd.com/films/popular/this/week/"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/letterboxd-scraper").call(run_input={
"startUrls": [
"https://letterboxd.com/films/popular/this/week/"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/letterboxd-scraper').call({
"startUrls": [
"https://letterboxd.com/films/popular/this/week/"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Film scraped One film scraped with full metadata. | $0.0042 | $0.0021 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Europe PMC Scraper
Bulk-scrape life-science and biomedical literature from Europe PMC (40M+ records: PubMed, PMC, preprints, patents): title, abstract, authors, journal, year, DOI, PMID/PMCID, citation count, MeSH terms, open-access flag and full-text/PDF links. Thousands per run. No setup.
325 runs · 5 users · $0.001 / article scraped
arXiv Papers Scraper
Search and extract arXiv papers: title, abstract, authors, categories, published/updated dates, DOI, journal reference, and direct PDF links. Filter by category and sort by newest, recently updated or relevance. Fetch by arXiv ID too. For research, lit reviews and AI/ML monitoring. No setup.
140 runs · 2 users · $0.0025 / paper scraped
OpenLibrary Book Scraper
Search millions of books on OpenLibrary by keyword, author, subject or ISBN and get title, authors, publisher, year, subjects, ISBNs, edition count, ratings, page count and cover. Clean, no setup.
124 runs · 5 users · $0.002 / book scraped
Semantic Scholar Scraper
Bulk-scrape academic papers from Semantic Scholar's 200M+ corpus: title, abstract, AI TLDR summary, authors, venue, year, citation & influential-citation counts, fields of study, DOI/PubMed/arXiv IDs and open-access PDF links. Filter by year, field and citations. Thousands per run. No setup.
123 runs · 7 users · $0.001 / paper scraped
Wikipedia Scraper
Search Wikipedia or look up exact articles and get the full plain-text content, summary, categories, image, Wikidata ID and monthly pageview trends. Any language. Great for research, RAG and AI datasets. No setup.
121 runs · 1 users · $0.001 / article scraped
OpenAlex Scholarly Works Scraper
Search 250M+ academic papers via OpenAlex: title, abstract, authors, institutions, venue, citation count, DOI, open-access status and topics. Filter by year, type and open access. For research, R&D and lit reviews. No setup.
118 runs · 1 users · $0.001 / work scrapedSend the site and the fields. We build it and you get it first.