Glassdoor Jobs Scraper
hipersoft/glassdoor-scraper
Scrape Glassdoor job listings by keyword, location or search URL: title, company, rating, salary range, full description, skills, company size, industry and website. 20 countries, with date, job type, remote and salary filters.
Total users
1Monthly users
0Total runs
10Per job scraped
$0.0004Last rebuilt
Nov 4, 2026Overview
Glassdoor Jobs Scraper extracts job listings from Glassdoor by keyword, location or search link: job title, company, company rating, salary range, full job description, skills, location, coordinates, company size, industry, revenue, website and apply link. Search 20 country sites, with date, job type, remote, Easy Apply, rating and salary filters.
What does Glassdoor Jobs Scraper do?
Give it keywords such as data analyst and locations such as Chicago, or paste Glassdoor search links, and get one clean row per job. Export to JSON, CSV or Excel. A test run collected 1,237 unique jobs across four searches in under four minutes, every one with its full description.
What data can you scrape from Glassdoor?
| Data | Fields |
|---|---|
| Job | jobId, title, occupation, description, descriptionHtml, snippet, skills, attributes, daysAgo, postedDate, easyApply, sponsored |
| Salary | salaryMin, salaryMedian, salaryMax, salaryCurrency, salaryPeriod, salarySource |
| Location | location, city, state, country, postalCode, latitude, longitude |
| Company | company, companyId, companyRating, companyLogo, companySize, companyWebsite, companyType, companyRevenue, companyHeadquarters, companyFounded, companyCeo, industry, sector |
| Links | url, applyUrl, jobSource |
Not every job has every field. Many salaries are Glassdoor estimates, and salarySource tells you which ones.
Use cases
- Salary benchmarking: compare pay ranges by title, city and company.
- Job market research: track demand for roles and skills across regions.
- Recruiting and staffing leads: find companies hiring now, with size, industry and website.
- Job boards and alerts: feed fresh listings into your own site or a daily digest.
- Career tools: build datasets of job descriptions for matching and analysis.
How to scrape Glassdoor jobs
- Open Glassdoor Jobs Scraper.
- Add keywords and locations, or paste Glassdoor search URLs.
- Pick a country site and any filters.
- Click Start.
- Export to JSON, CSV, Excel or XML.
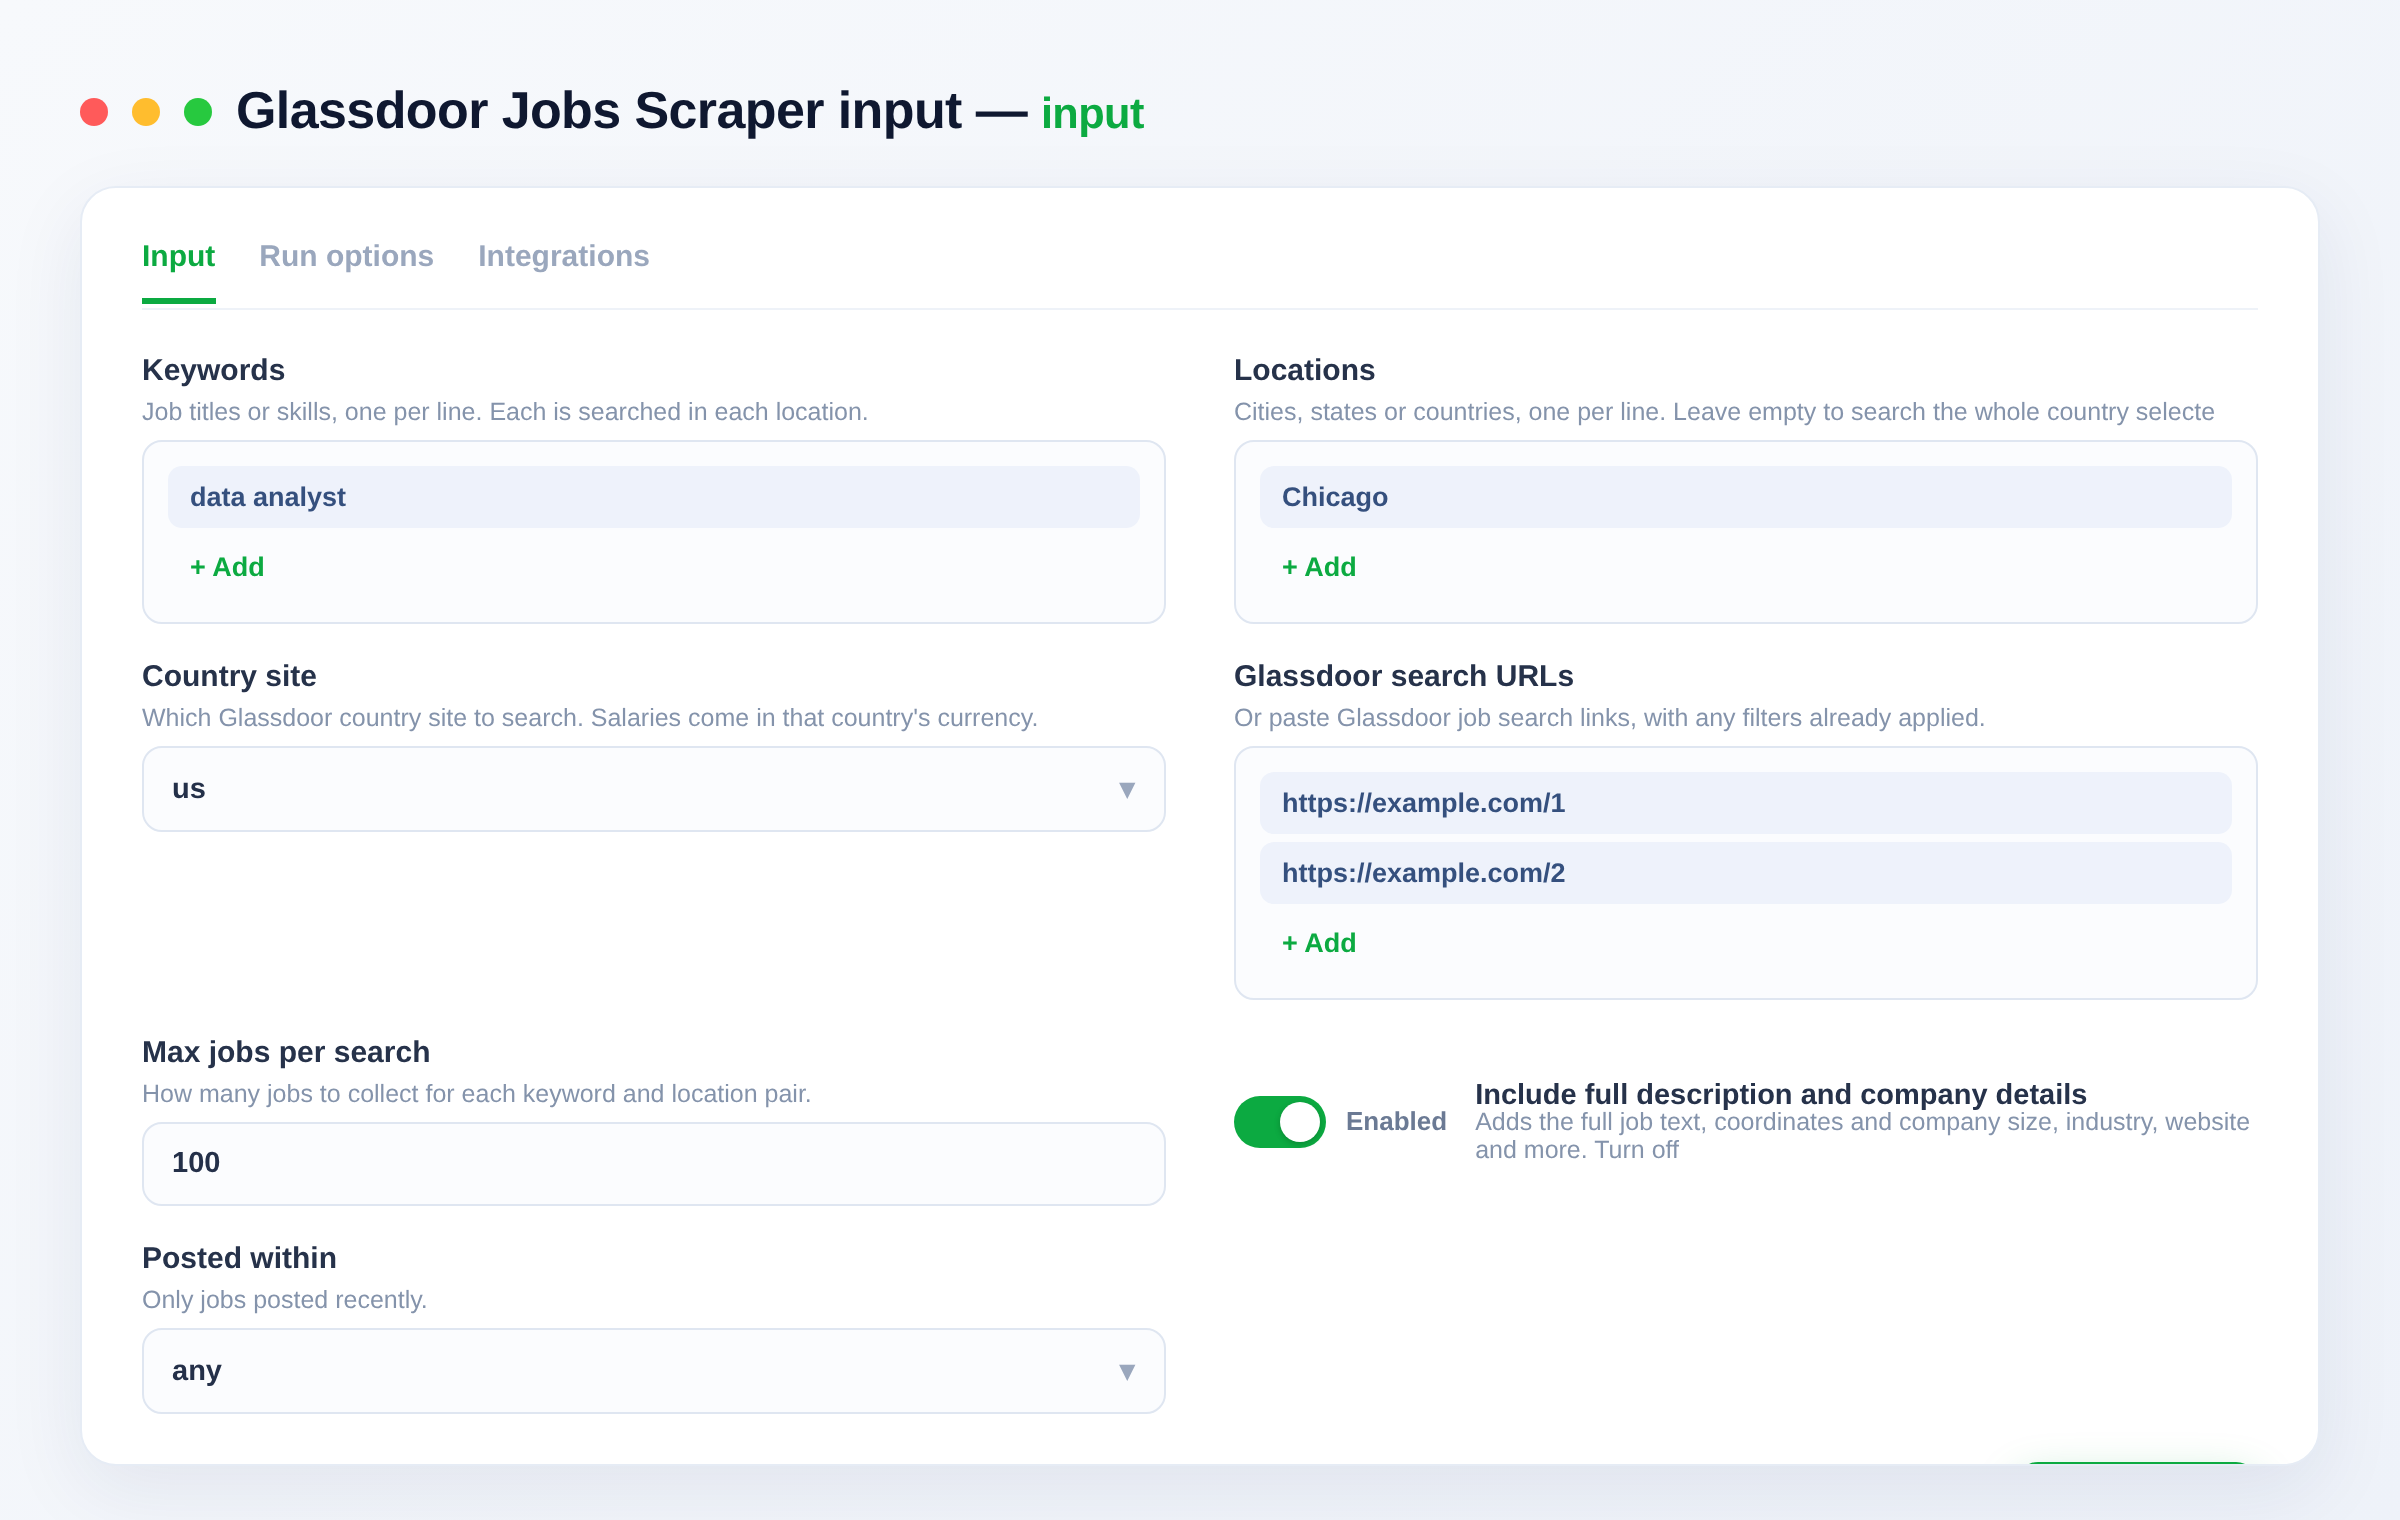
Input
{
  "keywords": ["data analyst"],
  "locations": ["Chicago", "Texas"],
  "country": "us",
  "postedWithinDays": "7",
  "jobType": "fulltime",
  "minSalary": 80000,
  "maxResultsPerSearch": 100
}
| Field | Description |
|---|---|
keywords |
Job titles or skills. Each is searched in each location. |
locations |
Cities, states or countries. Leave empty to search the whole country site. |
country |
Country site: us, uk, ca, au, in, sg, de, fr, es, it, nl, ie, at, be, ch, nz, hk, mx, br, ar. |
searchUrls |
Glassdoor job search links, with any filters already applied. |
maxResultsPerSearch |
Jobs per keyword and location pair (default 100, about 600 at most). |
includeDescription |
Full job text and company details. On by default. Turn off for faster runs with the short snippet only. |
postedWithinDays |
any, 1, 3, 7, 14 or 30. |
jobType |
any, fulltime, parttime, contract, internship or temporary. |
remoteOnly / easyApplyOnly |
Only remote jobs, or only Easy Apply jobs. |
minCompanyRating |
any, 1, 2, 3 or 4. |
minSalary / maxSalary |
Annual salary range, in the local currency. |
Output
A real row from a test run, with long text shortened.
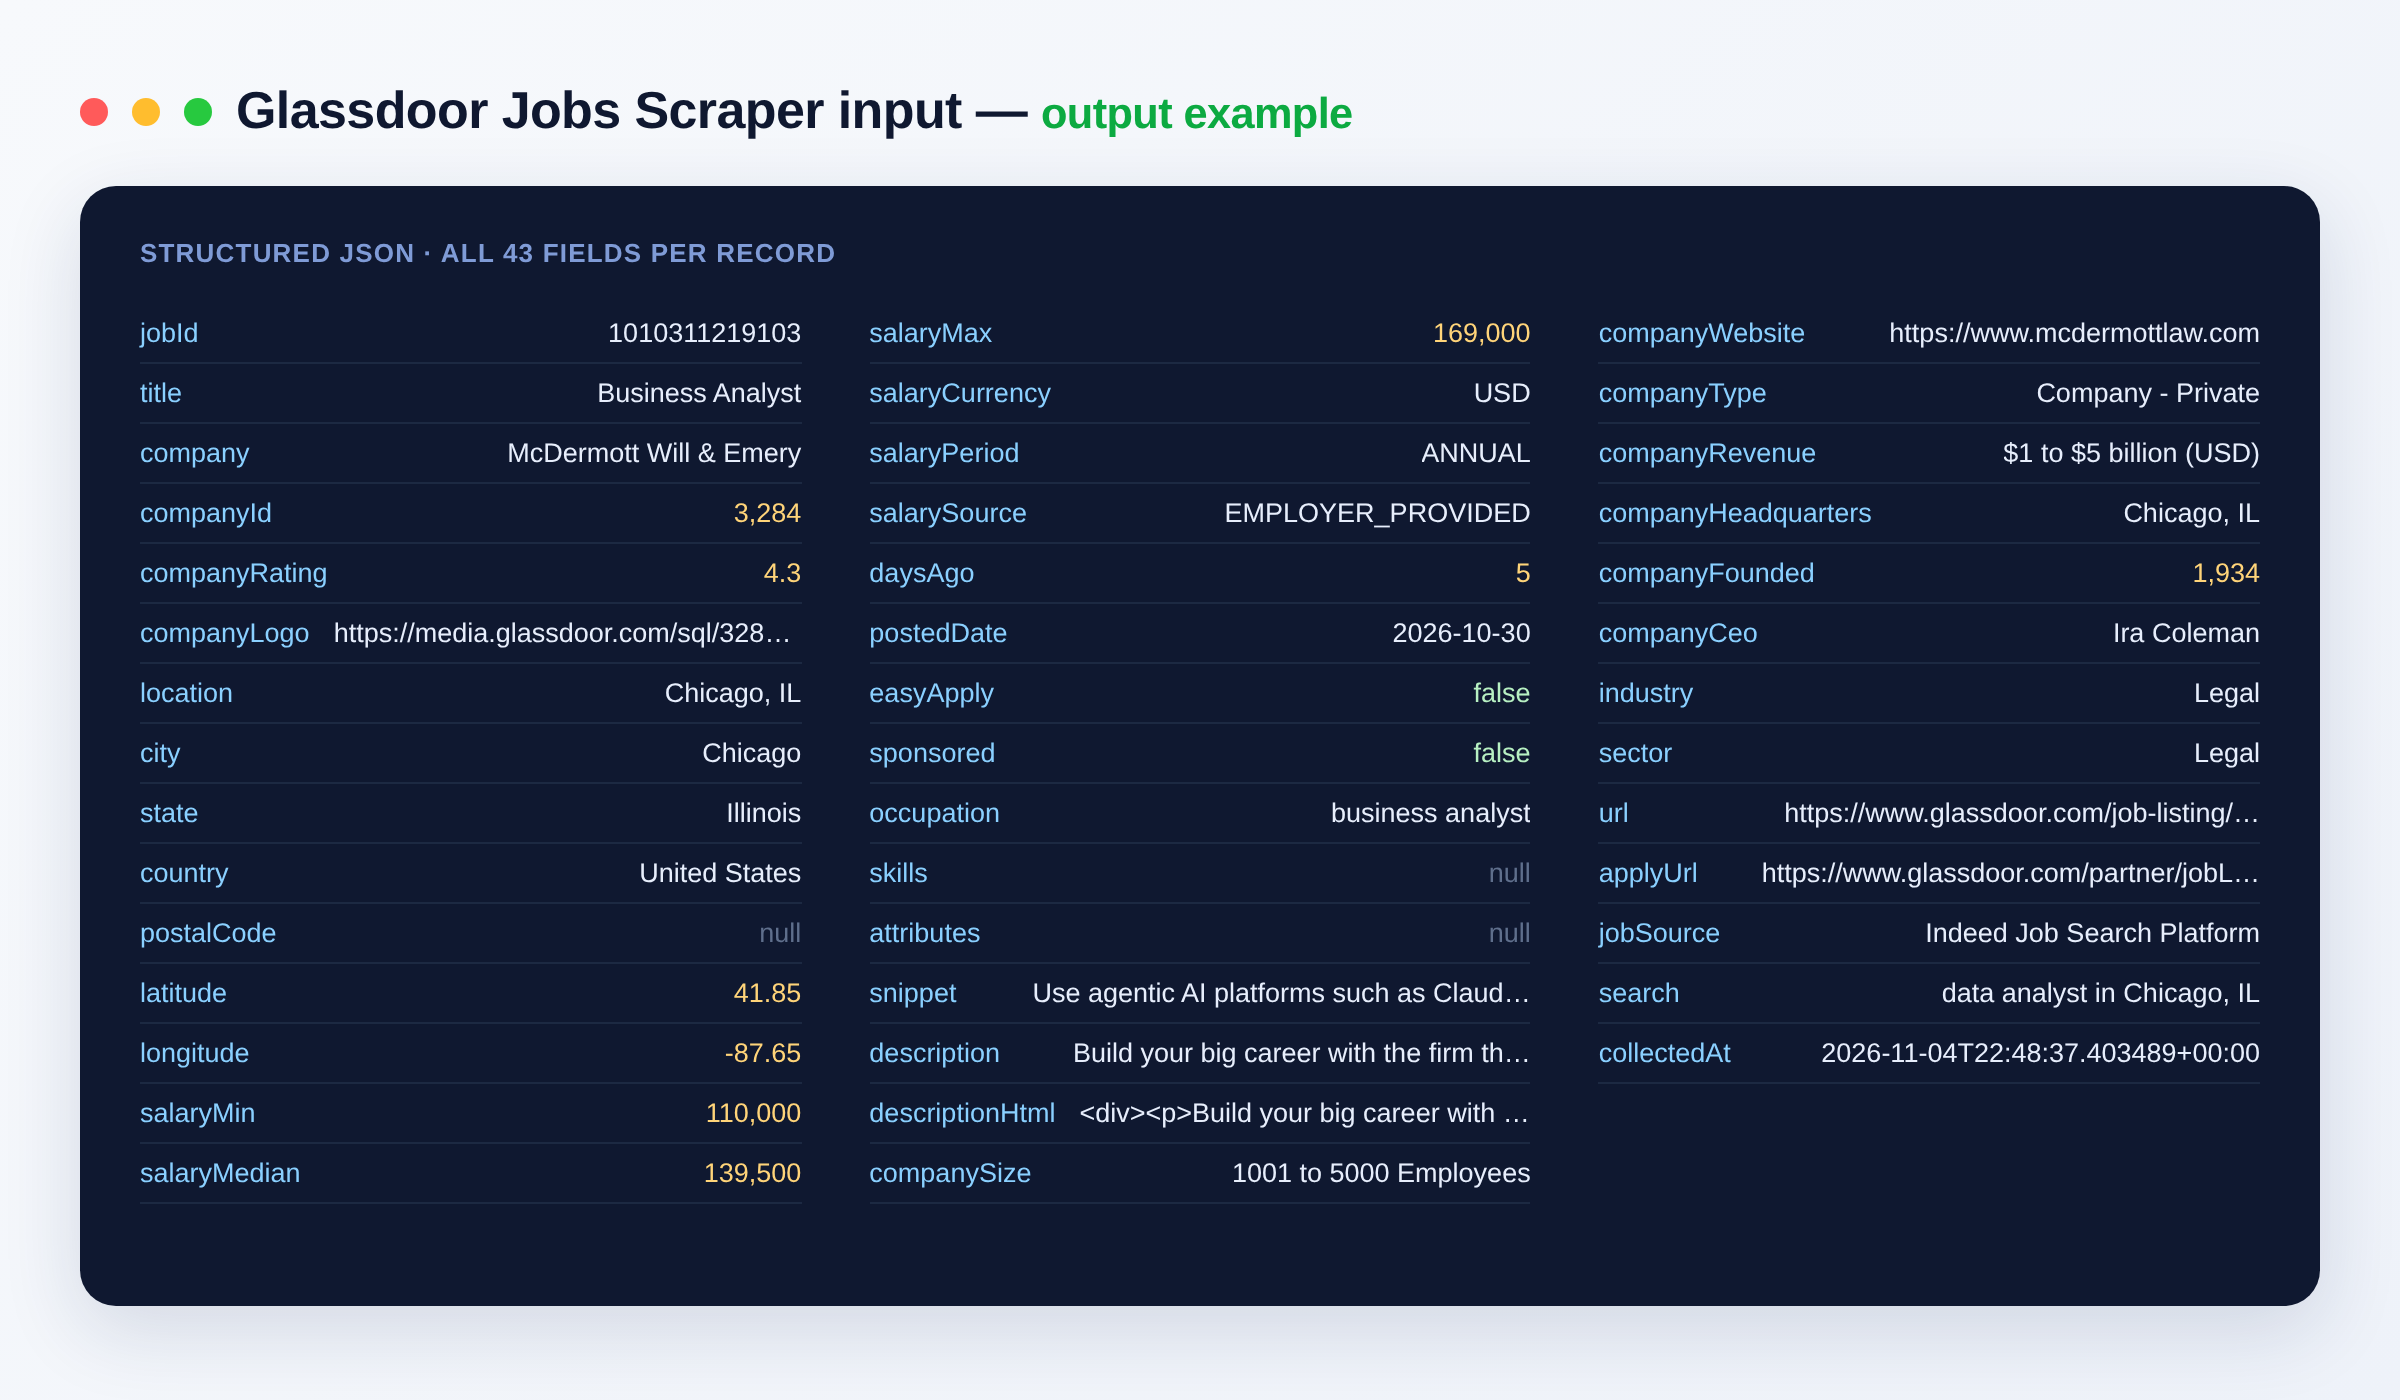
{
  "jobId": "1010194279608",
  "title": "Python developer",
  "company": "Intone Networks",
  "companyId": 375310,
  "companyRating": 4,
  "location": "Chicago, IL",
  "city": "Chicago",
  "state": "Illinois",
  "country": "United States",
  "latitude": 41.85,
  "longitude": -87.65,
  "salaryMin": 87083,
  "salaryMedian": 103616,
  "salaryMax": 123288,
  "salaryCurrency": "USD",
  "salaryPeriod": "ANNUAL",
  "salarySource": "ESTIMATED",
  "easyApply": false,
  "occupation": "software developer",
  "description": "Top 5 Skill sets 1. Programming Language: Python ...",
  "companySize": "201 to 500 Employees",
  "companyWebsite": "www.intonenetworks.com",
  "companyType": "Company - Private",
  "companyRevenue": "$5 to $25 million (USD)",
  "companyHeadquarters": "Iselin, NJ",
  "industry": "Information Technology Support Services",
  "sector": "Information Technology",
  "url": "https://www.glassdoor.com/job-listing/python-developer-intone-networks-JV_IC1128808_KO0,16_KE17,32.htm?jl=1010194279608"
}
Other job scrapers
- Indeed Scraper: job listings from Indeed.
- LinkedIn Jobs Scraper: job listings from LinkedIn.
- Google Jobs Scraper: jobs from across the web.
FAQ
How much does it cost? You pay per job delivered, shown on the Pricing tab. A job found by two searches is charged once. Set a maximum cost per run and it stops cleanly at that limit, storing only what you paid for.
How many jobs can I get? Each search reaches about 600 jobs. For more, split it by city, job type or date, and add each as its own search.
Which countries are covered? 20 Glassdoor country sites, including the US, UK, Canada, Australia, India, Singapore, Germany and France. Salaries come in the local currency.
Are the salaries real?
They're the ranges Glassdoor shows. salarySource says whether a range came from the employer or is a Glassdoor estimate. salaryMin, salaryMedian and salaryMax are the low, middle and high points of that range.
Why are some fields empty?
Glassdoor doesn't show every field on every job. Smaller employers often have no rating, revenue or CEO listed. If full text can't be loaded for a job, you still get its short snippet.
Can I connect this to other tools? Yes, through integrations on the Apify platform: Make, Zapier, Slack and more. You can also use the API or schedule regular runs.
Is it legal to scrape Glassdoor? It returns publicly listed job information. You are responsible for how you use it, including Glassdoor's terms and privacy law.
Notes
Independent tool, not affiliated with Glassdoor. Returns only public data; you are responsible for how you use it.
Feedback
How did it go? Good or bad, a review helps other users decide and tells us what to improve. Something broken or missing? Open an issue and we'll look into it.
Input
| Field | Type | Description |
|---|---|---|
keywordsKeywords | array | Job titles or skills, one per line. Each is searched in each location. |
locationsLocations | array | Cities, states or countries, one per line. Leave empty to search the whole country selected below. |
countryCountry site | string · us, uk, ca, au, in, sg… | Which Glassdoor country site to search. Salaries come in that country's currency. Default: "us" |
searchUrlsGlassdoor search URLs | array | Or paste Glassdoor job search links, with any filters already applied. |
maxResultsPerSearchMax jobs per search | integer | How many jobs to collect for each keyword and location pair. Default: 100 |
includeDescriptionInclude full description and company details | boolean | Adds the full job text, coordinates and company size, industry, website and more. Turn off for faster runs with the short snippet only. Default: true |
postedWithinDaysPosted within | string · any, 1, 3, 7, 14, 30 | Only jobs posted recently. Default: "any" |
jobTypeJob type | string · any, fulltime, parttime, contract, internship, temporary | Only this employment type. Default: "any" |
remoteOnlyRemote only | boolean | Only remote jobs. Default: false |
easyApplyOnlyEasy Apply only | boolean | Only jobs with Easy Apply. Default: false |
minCompanyRatingMin company rating | string · any, 1, 2, 3, 4 | Only companies rated at least this. Default: "any" |
minSalaryMin salary | integer | Minimum annual salary, in the local currency. |
maxSalaryMax salary | integer | Maximum annual salary, in the local currency. |
proxyConfigurationProxy | object | Optional. The default works for all countries. |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~glassdoor-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "keywords": [
    "data analyst"
  ],
  "locations": [
    "Chicago"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/glassdoor-scraper").call(run_input={
"keywords": [
"data analyst"
],
"locations": [
"Chicago"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/glassdoor-scraper').call({
"keywords": [
"data analyst"
],
"locations": [
"Chicago"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Job scraped One Glassdoor job delivered, with full description and company details. | $0.0004 | $0.0002 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Dribbble Shots Scraper
Scrape public design shots from Dribbble: title, high-res image, tags, likes, views and designer credit. Filter by category or sort, export JSON, CSV or Excel.
368 runs · 5 users · $0.003 / shot scraped
Computrabajo Scraper
Scrape Computrabajo job listings across Latin America (Mexico, Colombia, Argentina, Chile, Peru and more): title, company, location, salary, posted date and apply URL. Filter by country and keyword. No setup.
210 runs · 4 users · $0.002 / listing scraped
Kraken Market Data Scraper
Fetch Kraken spot market data in bulk: ticker stats (ask, bid, last, 24h high/low/volume/vwap), OHLC candles for any interval, order book depth (top bids/asks), and tradable pair metadata. Fast, clean and cheap.
168 runs · 4 users · $0.001 / pair scraped
Bayt Scraper
Scrape Bayt.com job listings across the Middle East (UAE, Saudi Arabia, Egypt, Qatar and more): title, company, location, posted date and apply URL. Filter by country and keyword.
136 runs · 4 users · $0.003 / job scraped
GitHub Scraper
Search GitHub and scrape repositories (stars, forks, language, topics, license, dates) or user profiles (name, company, location, bio, followers, public email, repos). Uses the GitHub REST API; optional token for higher rate limits. For developer lead generation, OSS research and recruiting.
134 runs · 7 users · $0.0008 / item scraped
Hacker News Scraper
Scrape Hacker News stories, comments, Ask HN, Show HN, jobs and polls by keyword, points, comments and date range. Sort by relevance or newest. Title, URL, author, points, comment count, text and HN link. Fast clean HTTP via the HN Algolia API, no setup.
133 runs · 2 users · $0.004 / item scrapedSend the site and the fields. We build it and you get it first.