eJobs.ro Jobs Scraper
hipersoft/ejobs-scraper
Scrape job ads from eJobs.ro, Romania's largest job board: title, hiring company, city and county with coordinates, industry, department, career level, contract type, dates and the full job description. Filter by keyword, city or employer and export to JSON, CSV, Excel or XML.
Total users
13Monthly users
11Total runs
113Per job scraped
$0.002Last rebuilt
Oct 26, 2026Overview
Scrape eJobs.ro, Romania's largest job board, and turn thousands of live job ads into clean, structured data. This eJobs scraper collects the job title, hiring company, city and county, industry, department, career level, contract type, education level, publication and expiry dates, apply link and the full job description — as HTML and as readable plain text. Export everything to JSON, CSV, Excel or XML, or pull it straight from the API. Fast, reliable, and you pay only per job you actually get.
What does the eJobs.ro Scraper do?
The eJobs.ro Scraper is a job-board crawler that extracts every public job ad on eJobs.ro into a flat, analysis-ready table. Search by keyword the way you would on the site (java, contabil, sofer, cluj), pull every open role from a specific employer, or hand it a list of job links. Each result is one tidy row with dozens of data points — no copy-pasting, no manual exports, no page-by-page browsing.
Because every numeric code on the board is resolved into a readable label, you get IT / Telecom instead of an industry id and Senior-Level (> 5 ani) instead of a career-level id. Romanian diacritics are handled for you, so a filter typed as iasi still matches Iași.
What data can you scrape from eJobs.ro?
| Data point | Description |
|---|---|
title |
Job title exactly as published |
url |
Direct link to the job ad |
companyName |
Hiring company |
companyAlias |
Trading / brand name where the employer uses one |
companyVerified |
Whether the employer is a verified account |
companyUrl |
Link to the company profile |
companyWebsite |
Employer's own website |
companyWebsites |
Every website the employer lists |
companyCity, companyAddress |
Employer head-office location |
companyOpenJobs |
How many ads that employer currently has open |
locations |
Every listed work location: city, county, street address, latitude, longitude |
cities, counties |
Flat arrays of city and county names |
locationsText |
All cities in one readable string |
isRemote |
Whether the role can be done from home |
isNationwide |
Whether the ad covers the whole country |
industries |
Industry labels (IT / Telecom, Construcții, Sănătate…) |
departments |
Department labels (Vânzări, Marketing, Financiar…) |
careerLevels |
Seniority (Entry-Level, Mid-Level, Senior-Level, Manager…) |
contractTypes |
Full time, Part time, Internship, Proiect… |
educationLevels |
Required education level |
positions |
Number of open positions in the ad |
publishedAt, republishedAt |
When the ad went live / was refreshed (ISO 8601) |
expiresAt, lastModifiedAt |
When the ad closes / was last edited (ISO 8601) |
applyUrl |
External application link when the employer supplies one |
description / descriptionText |
Full job description, HTML and plain text |
idealCandidate / idealCandidateText |
Requirements and ideal-candidate section |
companyDescription / companyDescriptionText |
Employer's own description |
scrapedAt |
When the row was collected (ISO 8601) |
Use cases
- Build a job board or aggregator — keep a Romanian jobs feed fresh with a scheduled run and one row per ad.
- Recruitment market research — measure hiring demand by city, county, industry, department and seniority over time.
- Salary and skills analysis — mine thousands of full descriptions for required skills, tools, languages and pay signals.
- Lead generation for staffing agencies — find companies that are actively hiring, with verified status, website and open-role counts.
- Competitive hiring intelligence — track exactly which roles a competitor is opening, where, and how fast they refresh them.
- Talent sourcing and job alerts — filter to remote roles, a city or a seniority level and push matches into Slack or email.
- Academic and economic research — build a longitudinal dataset of the Romanian labour market from public postings.
- Enrich a CRM or ATS — attach live hiring signals to accounts you already track.
How to scrape eJobs.ro job data
- Add the eJobs.ro Scraper to your Apify account and open the input form.
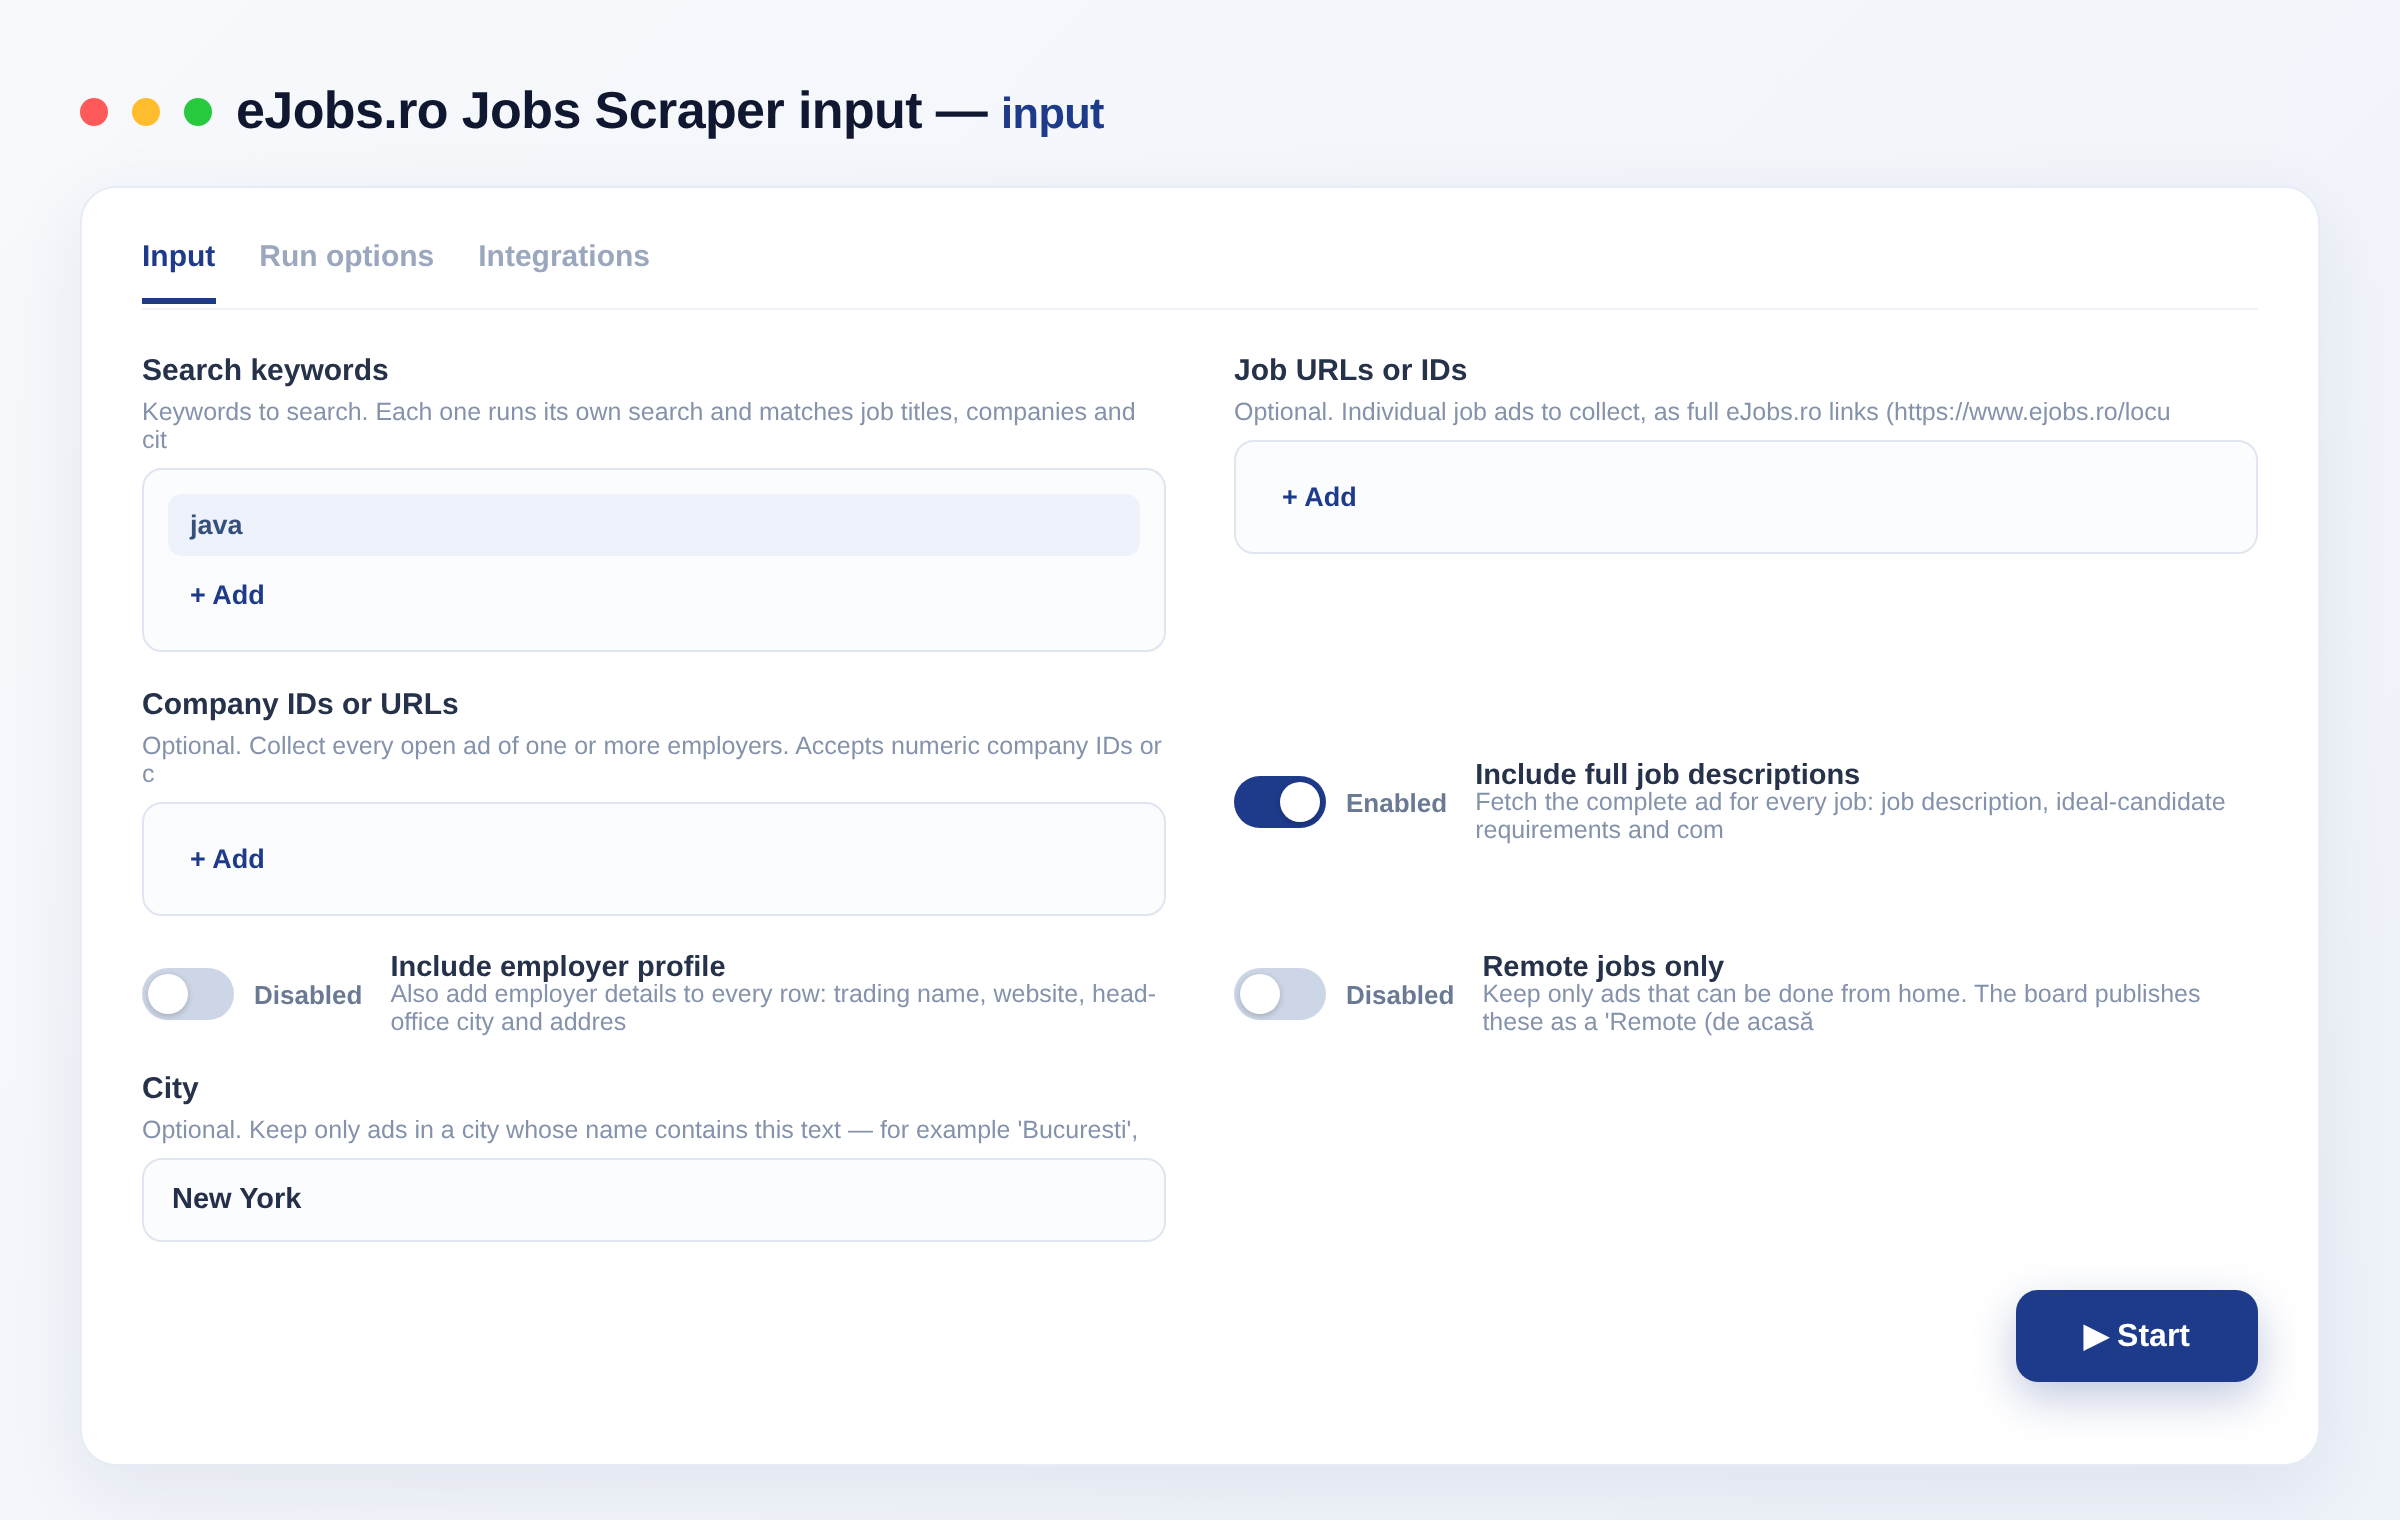
- Type one or more search keywords — a role (
java,contabil), a city (cluj), or both (inginer bucuresti). Leave it empty to collect the latest ads across the whole board. - Optionally narrow the results with city, county, industry, department, contract type, career level, company or remote only, and with posted within (days).
- Set Max items if you want a smaller sample, and decide whether to include full descriptions and the employer profile.
- Click Start, then download the dataset as JSON, CSV, Excel or XML — or fetch it from the Apify API.
Input
Scrape by keyword, by employer, or by URL
Three entry points, and you can combine them in one run:
- Search keywords — the everyday way to use the board. Every keyword runs its own search.
- Company IDs or URLs — pulls every open ad of one or more employers.
- Job URLs or IDs — grabs specific ads you already have links to.
Leave all three empty and the scraper collects the latest job ads on the board.
Example input
{
  "searchQueries": ["java", "contabil"],
  "city": "Cluj",
  "contractType": "Full time",
  "careerLevel": "Senior",
  "postedWithinDays": 30,
  "includeDescriptions": true,
  "includeCompanyProfile": true,
  "maxItems": 500
}
Input reference
| Field | Type | Description |
|---|---|---|
searchQueries |
array | Keywords to search — matches job titles, companies and cities |
jobUrls |
array | Specific job links or numeric job IDs |
companyIds |
array | Company IDs or company page links — collects every open ad of that employer |
includeDescriptions |
boolean | Fetch the full ad text (description, ideal candidate, company description). Default true |
includeCompanyProfile |
boolean | Add employer website, head office and open-role count to every row. Default false |
remoteOnly |
boolean | Keep only work-from-home roles |
city |
string | Keep only ads in a matching city (diacritic-insensitive) |
county |
string | Keep only ads in a matching county (județ) |
industry |
string | Keep only ads in a matching industry |
department |
string | Keep only ads in a matching department |
contractType |
string | Keep only ads with a matching contract type |
careerLevel |
string | Keep only ads with a matching seniority level |
company |
string | Keep only ads from employers whose name matches |
postedWithinDays |
integer | Keep only ads published or refreshed in the last N days (0 = no limit) |
maxItemsPerQuery |
integer | Cap per keyword / employer (0 = no cap) |
maxItems |
integer | Overall cap for the run (0 = no cap) |
proxyConfiguration |
object | Optional proxy settings — not required by default |
Output
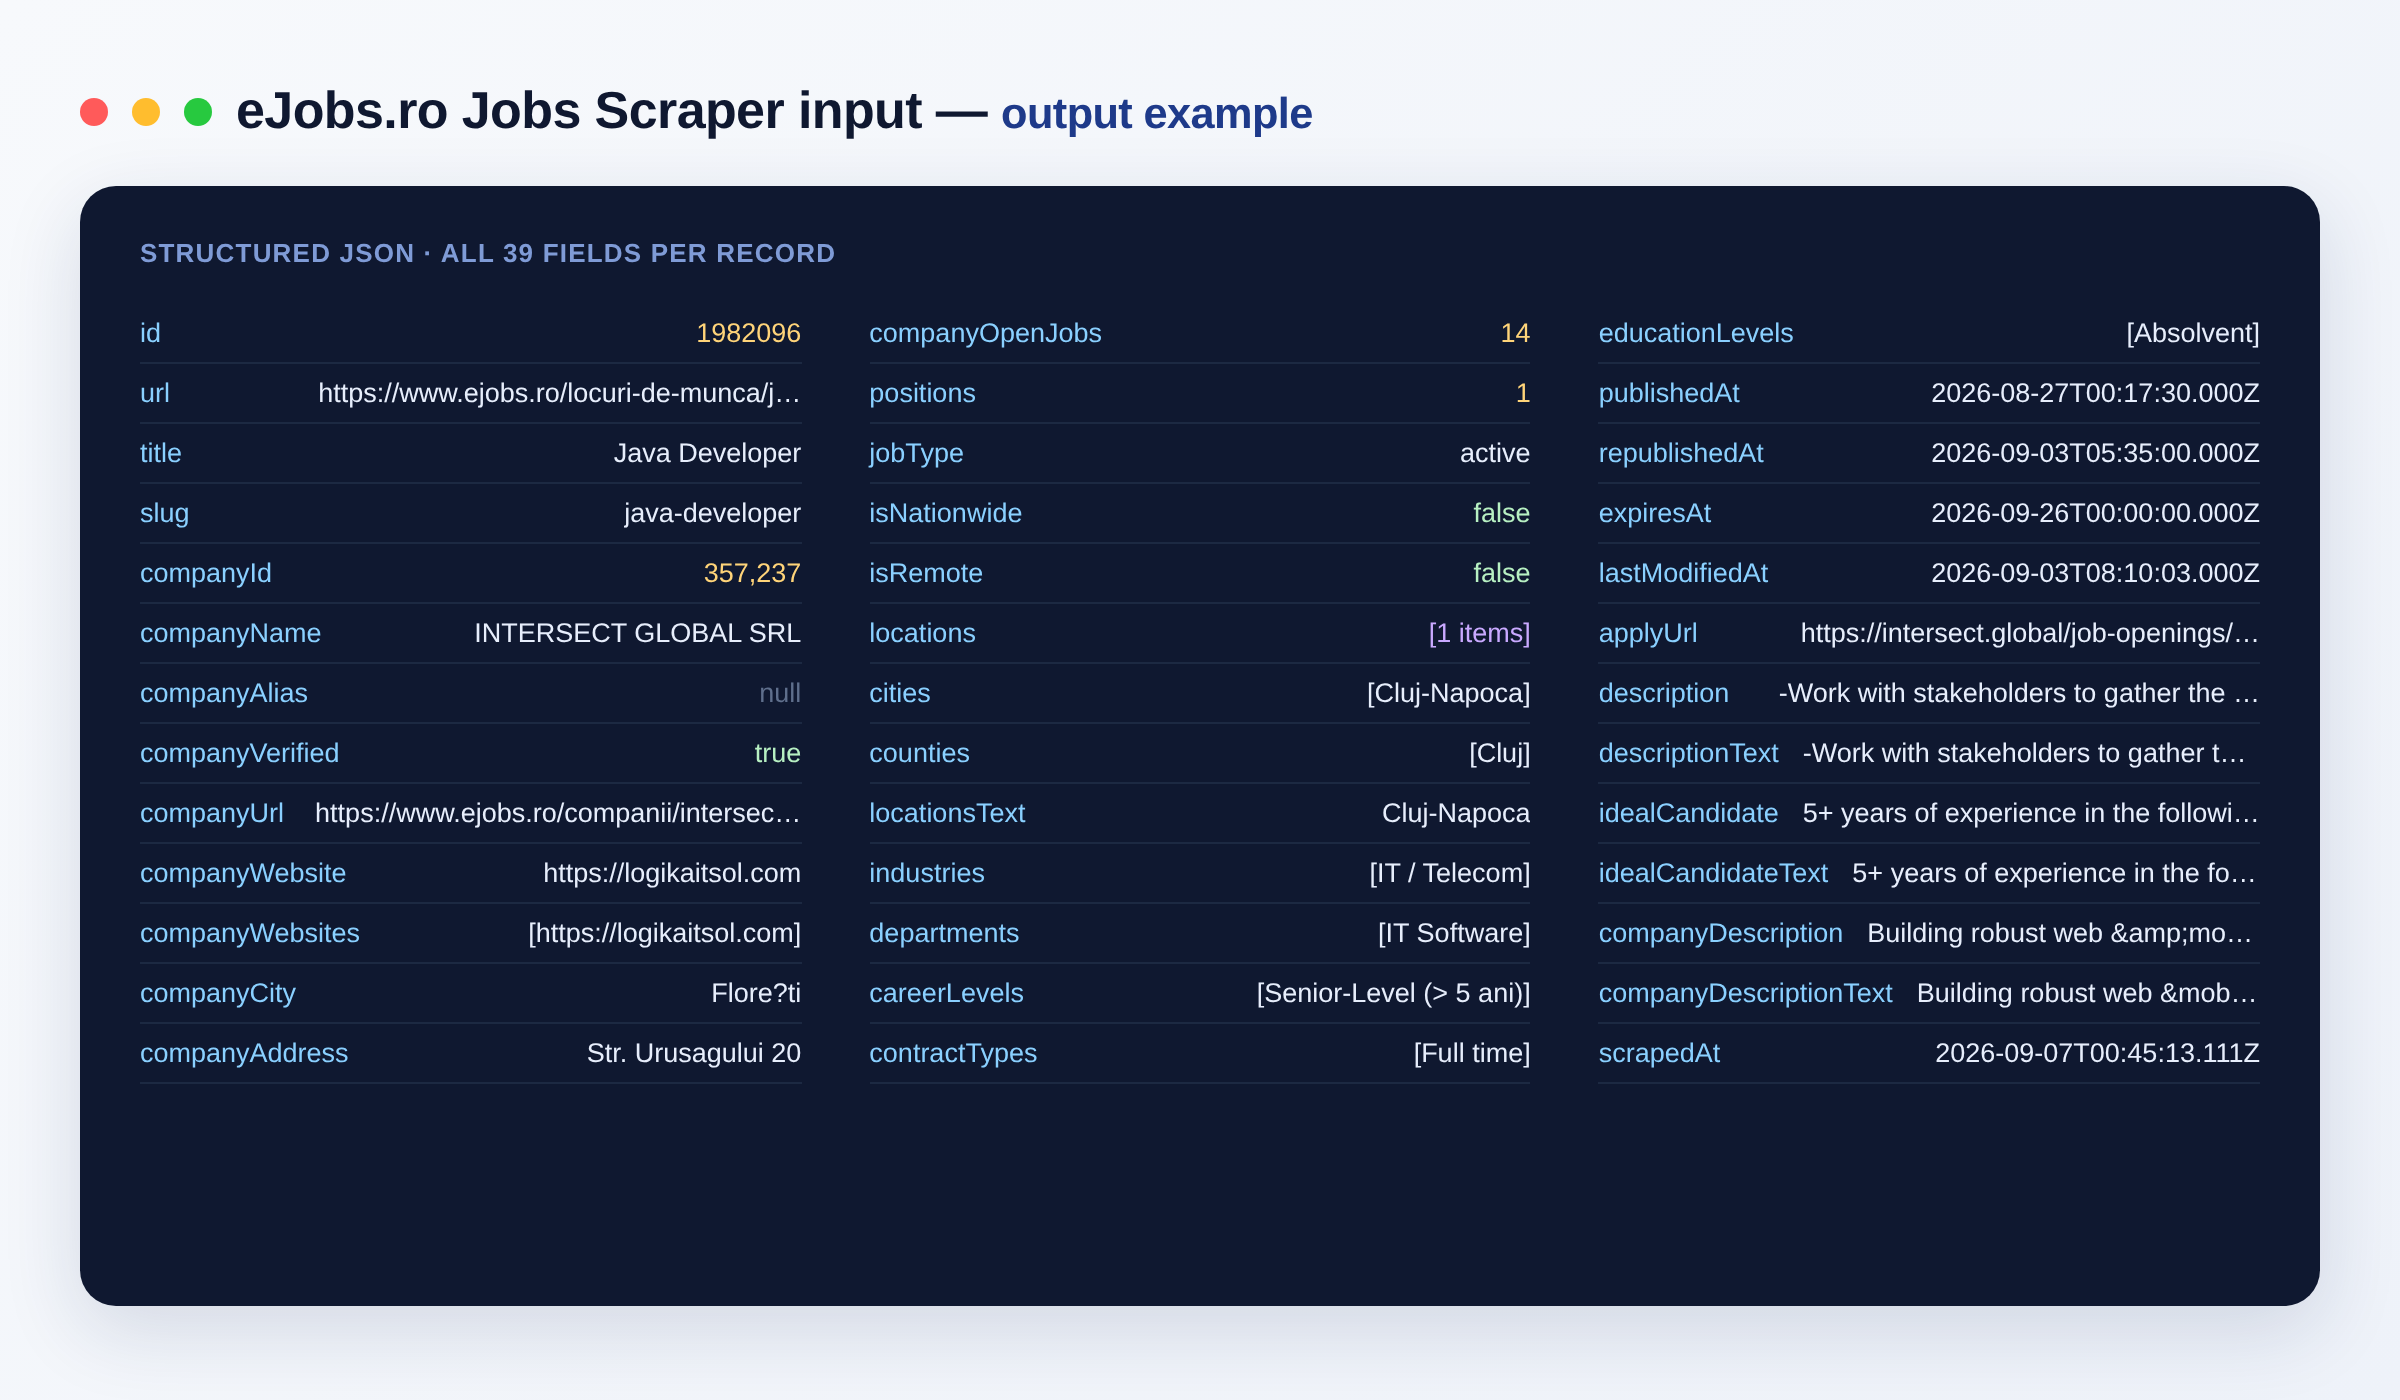
Every job is one flat record:
{
  "id": 1982096,
  "url": "https://www.ejobs.ro/locuri-de-munca/java-developer/1982096",
  "title": "Java Developer",
  "companyName": "INTERSECT GLOBAL SRL",
  "companyVerified": true,
  "companyUrl": "https://www.ejobs.ro/companii/intersect-global-srl",
  "companyOpenJobs": 12,
  "positions": 1,
  "isRemote": false,
  "isNationwide": false,
  "locations": [
    { "city": "Cluj-Napoca", "county": "Cluj", "address": "Str. Republicii 9", "latitude": 46.77, "longitude": 23.6 }
  ],
  "cities": ["Cluj-Napoca"],
  "counties": ["Cluj"],
  "locationsText": "Cluj-Napoca",
  "industries": ["IT / Telecom"],
  "departments": ["IT Software"],
  "careerLevels": ["Senior-Level (> 5 ani)"],
  "contractTypes": ["Full time"],
  "educationLevels": ["Facultate"],
  "publishedAt": "2026-08-27T00:17:27.000Z",
  "republishedAt": "2026-09-03T05:35:00.000Z",
  "expiresAt": "2026-09-26T00:00:00.000Z",
  "applyUrl": null,
  "descriptionText": "We are looking for a Java Developer to join…",
  "idealCandidateText": "5+ years of experience with Java and Spring…",
  "scrapedAt": "2026-09-07T00:34:04.024Z"
}
Output schema
| Field | Type | Description |
|---|---|---|
id |
integer | Job ad ID on the board |
url |
string (URL) | Direct link to the job ad |
title |
string | Job title |
slug |
string | URL slug of the ad |
companyId |
integer | Employer ID |
companyName |
string | Employer legal name |
companyAlias |
string | Employer trading / brand name |
companyVerified |
boolean | Whether the employer account is verified |
companyUrl |
string (URL) | Employer profile page |
companyWebsite |
string (URL) | Employer's own website |
companyWebsites |
array | Every website the employer lists |
companyCity |
string | Employer head-office city |
companyAddress |
string | Employer head-office address |
companyOpenJobs |
integer | Ads that employer currently has open |
positions |
integer | Open positions in this ad |
jobType |
string | Ad status as published |
isNationwide |
boolean | Ad covers the whole country |
isRemote |
boolean | Role can be done from home |
locations |
array | Objects with city, county, address, latitude, longitude |
cities |
array | City names |
counties |
array | County (județ) names |
locationsText |
string | All cities in one readable string |
industries |
array | Industry labels |
departments |
array | Department labels |
careerLevels |
array | Seniority labels |
contractTypes |
array | Contract-type labels |
educationLevels |
array | Required education levels |
publishedAt |
string (ISO date) | First publication |
republishedAt |
string (ISO date) | Last refresh |
expiresAt |
string (ISO date) | Ad expiry |
lastModifiedAt |
string (ISO date) | Last edit |
applyUrl |
string (URL) | External application link |
description |
string | Full job description (HTML) |
descriptionText |
string | Full job description (plain text) |
idealCandidate |
string | Requirements section (HTML) |
idealCandidateText |
string | Requirements section (plain text) |
companyDescription |
string | Employer description (HTML) |
companyDescriptionText |
string | Employer description (plain text) |
scrapedAt |
string (ISO date) | When the row was collected |
Need job data from other markets?
- StepStone Scraper — jobs across Germany, Austria and the Benelux
- France Travail Scraper — the French public employment service
- Arbeitnow Scraper — German and English-speaking roles in Europe
- Reed Scraper — one of the UK's biggest job boards
- Indeed Scraper — worldwide job search
- Company Jobs Scraper — careers pages of individual employers
FAQ
How many jobs can I scrape from eJobs.ro?
As many as your searches return. Each keyword walks the full result list the board serves for it, and you can run as many keywords, employers and job links in one run as you like. Use maxItems to cap a run.
Do I need an account, a login or any setup? No. Add the actor, type a keyword, press Start. There is nothing to install and no credentials to supply.
How does billing work? Pay per result. You are charged for each job row stored in your dataset, so a run that returns nothing costs you effectively nothing. There are no monthly platform fees to use the actor.
Can I get the full job description?
Yes — it is on by default. Every row carries the job description, the ideal-candidate requirements and the employer's own description, each as HTML and as clean plain text. Switch includeDescriptions off for a faster, lighter listing-only export.
Can I scrape all jobs from one company?
Yes. Put the company IDs (or company page links) into companyIds and the scraper collects every open ad for those employers, including the count of roles they currently have live.
Can I filter to remote jobs only? Yes. Tick Remote jobs only and the run keeps just the work-from-home ads. You can combine it with a keyword, a seniority level or a contract type.
Which export formats are supported? JSON, CSV, Excel, XML and HTML table from the Apify console, plus the dataset API for programmatic access.
How fresh is the data?
Every run reads the board live, and each row carries publishedAt, republishedAt and scrapedAt timestamps so you always know how recent an ad is. Schedule the actor hourly or daily to keep a dataset current.
Can I integrate this with my own tools? The eJobs.ro Scraper can be connected with almost any cloud service or web app thanks to integrations on the Apify platform. It works with Make, Zapier, Slack, Airbyte, GitHub, Google Drive and many more, plus the Apify API, JS/Python clients and MCP. Or use webhooks to trigger an action whenever a run finishes.
Is scraping eJobs.ro legal? This scraper collects only public job listings — the same information any visitor can read on the site. It never touches candidate profiles, CVs or any personal data behind a login. You are responsible for using the data in line with applicable law and the site's terms.
Notes
Original clean-room implementation. Returns only public data; you are responsible for compliance with eJobs.ro's terms. Not affiliated with eJobs.ro.
Input
| Field | Type | Description |
|---|---|---|
searchQueriesSearch keywords | array | Keywords to search. Each one runs its own search and matches job titles, companies and cities — for example 'java', 'contabil', 'sofer', 'cluj' or 'inginer bucuresti'. Leave empty to collect the latest job ads instead. |
jobUrlsJob URLs or IDs | array | Optional. Individual job ads to collect, as full eJobs.ro links (https://www.ejobs.ro/locuri-de-munca//) or bare numeric IDs. |
companyIdsCompany IDs or URLs | array | Optional. Collect every open ad of one or more employers. Accepts numeric company IDs or company page links. |
includeDescriptionsInclude full job descriptions | boolean | Fetch the complete ad for every job: job description, ideal-candidate requirements and company description (each as HTML and as plain text). Turn off for a faster, lighter listing-only export. Default: true |
includeCompanyProfileInclude employer profile | boolean | Also add employer details to every row: trading name, website, head-office city and address, and how many ads that company currently has open. Default: false |
remoteOnlyRemote jobs only | boolean | Keep only ads that can be done from home. The board publishes these as a 'Remote (de acasă)' location. Default: false |
cityCity | string | Optional. Keep only ads in a city whose name contains this text — for example 'Bucuresti', 'Cluj', 'Timisoara' or 'Iasi'. |
countyCounty | string | Optional. Keep only ads in a county (judet) whose name contains this text — for example 'Cluj', 'Ilfov' or 'Brasov'. |
industryIndustry | string | Optional. Keep only ads whose industry contains this text — for example 'IT', 'Constructii', 'Sanatate' or 'Transport'. |
departmentDepartment | string | Optional. Keep only ads whose department contains this text — for example 'Vanzari', 'Marketing', 'Financiar' or 'Productie'. |
contractTypeContract type | string | Optional. Keep only ads whose contract type contains this text — for example 'Full time', 'Part time', 'Internship' or 'Proiect'. |
careerLevelCareer level | string | Optional. Keep only ads whose career level contains this text — for example 'Entry-Level', 'Middle', 'Senior' or 'Manager'. |
companyCompany name | string | Optional. Keep only ads whose hiring company name contains this text. |
postedWithinDaysPosted within (days) | integer | Optional. Keep only ads published or re-published in the last N days. 0 = no date limit. Default: 0 |
maxItemsPerQueryMax items per search | integer | Maximum jobs to keep from each keyword, company or feed (0 = as many as the source returns). Default: 0 |
maxItemsMax items | integer | Overall cap on jobs collected in this run (0 = no limit). Default: 0 |
proxyConfigurationProxy configuration | object | Proxy settings. Not required by default. If you experience reduced results, enable Apify Proxy for the most reliable access. Default: {"useApifyProxy": false} |
API
curl -X POST "https://api.apify.com/v2/acts/hipersoft~ejobs-scraper/run-sync-get-dataset-items?token=$APIFY_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{
  "searchQueries": [
    "java"
  ]
}'
from apify_client import ApifyClient
client = ApifyClient("YOUR_APIFY_TOKEN")
run = client.actor("hipersoft/ejobs-scraper").call(run_input={
"searchQueries": [
"java"
]
})
for item in client.dataset(run["defaultDatasetId"]).iterate_items():
print(item)import { ApifyClient } from 'apify-client';
const client = new ApifyClient({ token: 'YOUR_APIFY_TOKEN' });
const run = await client.actor('hipersoft/ejobs-scraper').call({
"searchQueries": [
"java"
]
});
const { items } = await client.dataset(run.defaultDatasetId).listItems();
console.log(items);Pricing
| Event | Price | Paid plans from |
|---|---|---|
| Job scraped One eJobs.ro job ad returned with all its fields. | $0.002 | $0.001 |
You pay only for what the run returns. Set a maximum cost per run and it stops cleanly at that limit.
Related scrapers
Dribbble Shots Scraper
Scrape public design shots from Dribbble: title, high-res image, tags, likes, views and designer credit. Filter by category or sort, export JSON, CSV or Excel.
359 runs · 5 users · $0.003 / shot scraped
Computrabajo Scraper
Scrape Computrabajo job listings across Latin America (Mexico, Colombia, Argentina, Chile, Peru and more): title, company, location, salary, posted date and apply URL. Filter by country and keyword. No setup.
206 runs · 4 users · $0.002 / listing scraped
Kraken Market Data Scraper
Fetch Kraken spot market data in bulk: ticker stats (ask, bid, last, 24h high/low/volume/vwap), OHLC candles for any interval, order book depth (top bids/asks), and tradable pair metadata. Fast, clean and cheap.
165 runs · 4 users · $0.001 / pair scraped
Bayt Scraper
Scrape Bayt.com job listings across the Middle East (UAE, Saudi Arabia, Egypt, Qatar and more): title, company, location, posted date and apply URL. Filter by country and keyword.
134 runs · 4 users · $0.003 / job scraped
GitHub Scraper
Search GitHub and scrape repositories (stars, forks, language, topics, license, dates) or user profiles (name, company, location, bio, followers, public email, repos). Uses the GitHub REST API; optional token for higher rate limits. For developer lead generation, OSS research and recruiting.
131 runs · 7 users · $0.0008 / item scraped
Hacker News Scraper
Scrape Hacker News stories, comments, Ask HN, Show HN, jobs and polls by keyword, points, comments and date range. Sort by relevance or newest. Title, URL, author, points, comment count, text and HN link. Fast clean HTTP via the HN Algolia API, no setup.
130 runs · 2 users · $0.004 / item scrapedSend the site and the fields. We build it and you get it first.